Projet 2 · Traduction automatiqueProjet 2 · Traduction automatique
PrintedImprimé le·aylart.github.io/learn·
CC BY-NC 4.0
What machine translation isQu'est-ce que la traduction automatique
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
What a translation system has to doCe qu'un système de traduction doit faire
A memory and a translation system
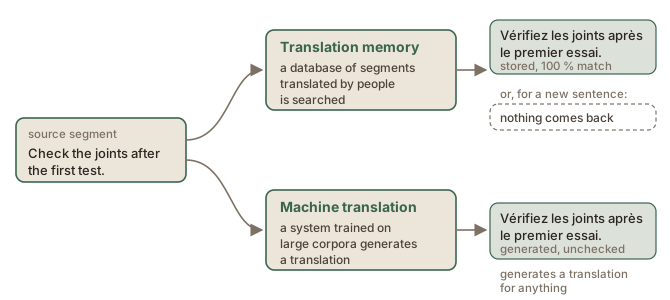
When you open a segment in a CAT tool and see a pre-filled suggestion for a
translation, that translation has either been retrieved from a translation
memory or been generated by a machine translation system
(Figure 1figure 1).
Figure 1. The same sentence sent to a translation memory and to a machine translation system.
a translation of any text, including text nobody ever translated
Strength
consistency, for content that was translated before
an answer for every segment, old or new
Weakness
nothing for new text
quality is not guaranteed, and the output gives no sign of how reliable it is
A translation memory and a machine translation system compared.
The second of the two, the machine translation system, is the subject of
this module, and the term is defined widely enough to cover every system of
the kind.
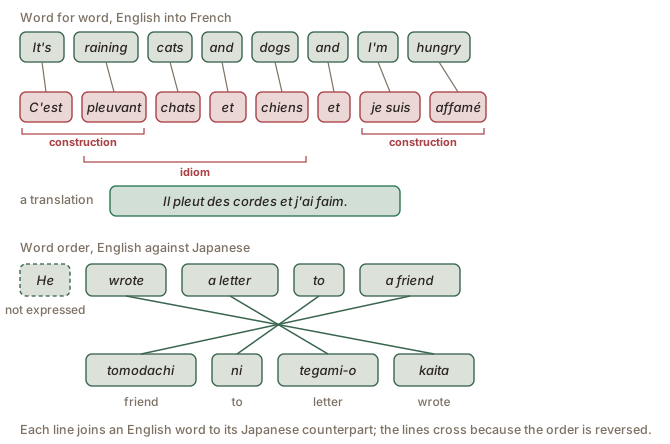
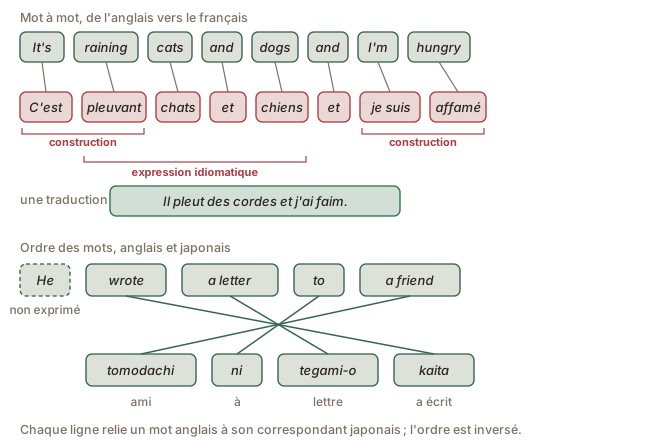
If translation were replacing each word with its equivalent, a bilingual
dictionary would be a translation system. Figure 2figure 2 shows two of the ways that fails.
Figure 2. Word for word, an English sentence into French, and the same sentence in English and in Japanese. The Japanese example is from Jurafsky and Martin (2026).
Eight kinds of difference between languages and cultures defeat the
dictionary.
Difference
Example
Consequence for a system
Word order
English He wrote a letter to a friend; Japanese tomodachi ni tegami-o kaita, word for word friend to letter wrote
the words have to be moved, and sometimes the whole sentence rebuilt
One word, several words
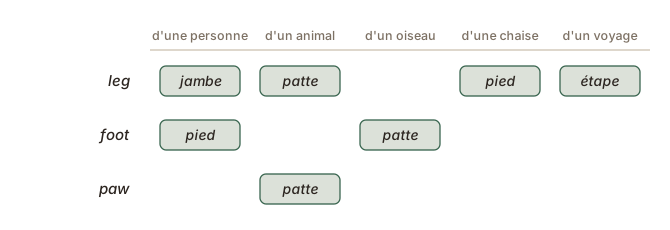
English bass is Spanish lubina (the fish) or bajo (the instrument); German has Wand (inside) and Mauer (outside) for wall
a sense has to be chosen from the context
What is left unsaid
Spanish Mostró su hallazgo a un descifrador ambulante has no subject; English needs He showed his find to a wandering decoder
a word the target grammar requires has to be supplied, and one it does without dropped
A different construction
English I am hungry, with an adjective; French j’ai faim, with a noun. English I like coffee; Spanish me gusta el café, where the coffee is the subject and pleases me
the same idea has to be rebuilt with the part of speech and the construction the target language uses
A word with no equivalent
Dutch gezellig, for a warm, convivial atmosphere; Mandarin xiào, for which English makes do with filial piety (Jurafsky & Martin, 2026)
a phrase, a near-equivalent or a loan has to stand in for the missing word
Figurative language and idioms
English it’s raining cats and dogs; French il pleut des cordes
the literal wording has to give way to the image the target language uses
Cultural knowledge
a Quebec text mentions le cégep; an English one mentions Grade 11 or Thanksgiving, which falls in October in Canada and in November in the United States
an explanation or an equivalent has to be added for readers who do not share the reference
Text-type conventions
an English manual says Press the button (imperative), a French one Appuyer sur le bouton (infinitive); a Japanese novel repeats a word where an English one would vary it
the text has to be reshaped to the conventions of its genre in the target culture, beyond the sentence
Eight differences between languages and cultures that defeat word-for-word replacement. The first three rows follow Jurafsky and Martin (2026); the others are mine, with one example borrowed from them.
Some of these, though not all and not to the same degree, are the
difficulties translators face when they learn to translate well.
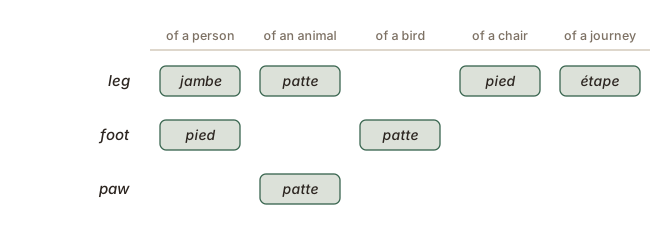
The second difference is drawn in Figure 3figure 3.
Figure 3. English leg, foot and paw against their French translations. Example from Jurafsky and Martin (2026).
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Une mémoire et un système de traduction
Quand vous ouvrez un segment dans un outil de TAO et que vous y trouvez une
proposition de traduction déjà remplie, cette traduction a été soit retrouvée
dans une mémoire de traduction, soit générée par un système de traduction
automatique
(Figure 1figure 1).
Figure 1. La même phrase envoyée à une mémoire de traduction et à un système de traduction automatique.
une traduction de n’importe quel texte, y compris un texte que personne n’a jamais traduit
Force
la cohérence, pour les contenus déjà traduits
une réponse pour chaque segment, ancien ou nouveau
Faiblesse
rien pour un texte nouveau
la qualité n’est pas garantie, et le résultat n’indique en rien s’il est fiable
Une mémoire de traduction et un système de traduction automatique comparés.
Le second des deux, le système de traduction automatique, est le sujet de ce
module, et le terme est défini assez largement pour couvrir tous les systèmes
du genre.
Si traduire consistait à remplacer chaque mot par son équivalent, un
dictionnaire bilingue serait un système de traduction. La Figure 2figure 2 montre deux des façons dont cela échoue.
Figure 2. Mot à mot, une phrase anglaise vers le français, et la même phrase en anglais et en japonais. L'exemple japonais vient de Jurafsky et Martin (2026).
Huit types de différences entre langues et entre cultures mettent le
dictionnaire en échec.
Différence
Exemple
Conséquence pour un système
L’ordre des mots
anglais He wrote a letter to a friend ; japonais tomodachi ni tegami-o kaita, mot à mot ami à lettre a écrit
il faut déplacer les mots, et parfois reconstruire toute la phrase
Un mot, plusieurs mots
l’anglais bass se dit en espagnol lubina (le poisson) ou bajo (l’instrument) ; l’allemand a Wand (à l’intérieur) et Mauer (à l’extérieur) pour mur
il faut choisir un sens d’après le contexte
Ce qui reste implicite
l’espagnol Mostró su hallazgo a un descifrador ambulante n’a pas de sujet ; l’anglais exige He showed his find to a wandering decoder
il faut ajouter un mot que la grammaire cible exige, et retirer celui dont elle se passe
Une autre construction
l’anglais I am hungry, avec un adjectif ; le français j’ai faim, avec un nom. L’anglais I like coffee ; l’espagnol me gusta el café, où le café est le sujet et me plaît
la même idée doit être reconstruite avec la partie du discours et la construction qu’emploie la langue cible
Un mot sans équivalent
le néerlandais gezellig, pour une atmosphère chaleureuse et conviviale ; le mandarin xiào, que l’anglais rend tant bien que mal par filial piety (Jurafsky & Martin, 2026)
une périphrase, un quasi-équivalent ou un emprunt doit remplacer le mot manquant
Le langage figuré et les expressions idiomatiques
l’anglais it’s raining cats and dogs ; le français il pleut des cordes
la formulation littérale doit céder la place à l’image qu’emploie la langue cible
Les connaissances culturelles
un texte québécois mentionne le cégep ; un texte anglais mentionne Grade 11 ou Thanksgiving, qui tombe en octobre au Canada et en novembre aux États-Unis
il faut ajouter une explication ou un équivalent pour les lecteurs qui ne partagent pas la référence
Les conventions du type de texte
un manuel anglais dit Press the button (impératif), un manuel français Appuyer sur le bouton (infinitif) ; un roman japonais répète un mot là où un roman anglais le varierait
le texte doit être remodelé selon les conventions de son genre dans la culture cible, au-delà de la phrase
Huit différences entre langues et entre cultures qui mettent en échec le remplacement mot à mot. Les trois premières lignes suivent Jurafsky et Martin (2026) ; les autres sont de moi, avec un exemple qui leur est emprunté.
Certaines de ces difficultés, pas toutes et pas au même degré, sont celles
que les traducteurs affrontent quand ils apprennent à bien traduire.
La deuxième différence est dessinée à la Figure 3figure 3.
Figure 3. Les mots anglais leg, foot et paw et leurs traductions françaises. Exemple tiré de Jurafsky et Martin (2026).
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
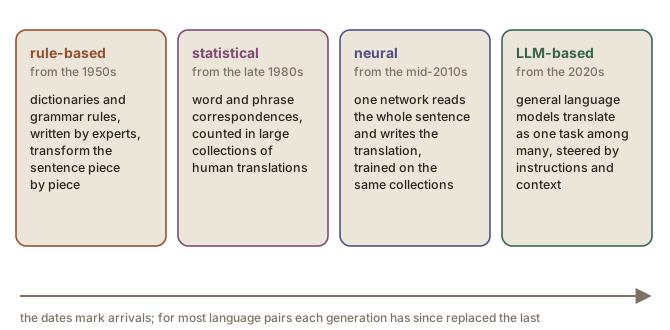
Figure 4. The four generations of machine translation. The dates mark when each approach arrived.
The dates of the four generations
The dates come from Jurafsky and Martin (2026), except the last; the detail of 1954 and 1966 from Hutchins (2003, 2004).
Late 1940s. Machine translation is proposed, soon after the first
computers.
1954. The first public demonstration of a prototype, the
Georgetown-IBM experiment, is widely reported: about sixty Russian
sentences are translated into English with a vocabulary of 250 words and
six rules. Russian was chosen for political reasons: with the Cold War
under way, the United States wanted above all to read what was being
written in the Soviet Union (Hutchins, 2004).
1966. The ALPAC report, commissioned by the agencies funding the
research in the United States, finds high-quality translation out of reach
and leads to a sharp cut in that funding for about twenty years
(Hutchins, 2003).ALPAC is the Automatic Language Processing Advisory Committee, set up in 1964 and chaired by John R. Pierce of Bell Telephone Laboratories; its only concern was the US government’s need to read Russian documents. The report itself is Language and Machines (National Research Council, 1966, doi:10.17226/9547); it concluded that “there is no immediate or predictable prospect of useful machine translation” and recommended machine aids for translators and better evaluation instead (Hutchins, 2003).
Some systems are built anyway, among them Météo, which translates Canadian
weather forecasts from English into French from the 1970s, and Systran.
Around 1990. Statistical methods arrive, made possible by large
bilingual corpora such as the Hansard, the proceedings of the Canadian
Parliament in both languages.
2023. WMT, the Conference on Machine Translation, includes large
language models among the systems of its yearly comparison for the first
time (Kocmi et al., 2023) (see also the WMT shared task chapter, in the Machine translation module) (voir aussi le chapitre La tâche partagée WMT, dans le module Traduction automatique).
Older generations survive where the translated text a neural system needs
does not exist: a narrow domain, or a language pair with little of it.
Sources
Hutchins, J. (2003). ALPAC: The (In)Famous Report. In S. Nirenburg, H. L. Somers & Y. A. Wilks (Eds.), Readings in Machine Translation (pp. 131–136). The MIT Press. https://doi.org/10.7551/mitpress/5779.003.0014
Hutchins, W. J. (2004). The Georgetown-IBM experiment demonstrated in January 1954. Proceedings of the 6th Conference of the Association for Machine Translation in the Americas: Technical Papers, 102–114. https://aclanthology.org/2004.amta-papers.12/
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2023). Findings of the 2023 Conference on Machine Translation (WMT23): LLMs Are Here but Not Quite There Yet. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), Singapore, 1–42. https://doi.org/10.18653/v1/2023.wmt-1.1
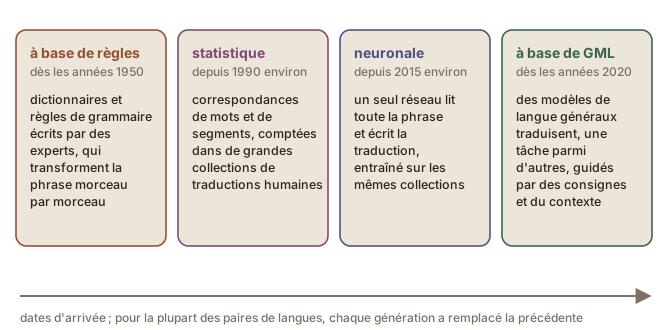
Figure 4. Les quatre générations de la traduction automatique. Les dates marquent l'arrivée de chaque approche.
Les dates des quatre générations
Les dates viennent de Jurafsky et Martin (2026), sauf la dernière ; le détail de 1954 et de 1966 vient de Hutchins (2003, 2004).
Fin des années 1940. La traduction automatique est proposée, peu après
les premiers ordinateurs.
1954. La première démonstration publique d’un prototype, l’expérience
Georgetown-IBM, est largement rapportée : une soixantaine de phrases russes
sont traduites en anglais avec un vocabulaire de 250 mots et six règles. Le
russe a été choisi pour des raisons politiques : en pleine guerre froide,
les États-Unis voulaient avant tout lire ce qui s’écrivait en Union
soviétique (Hutchins, 2004).
1966. Le rapport ALPAC, commandé par les organismes qui finançaient la
recherche aux États-Unis, conclut qu’une traduction de haute qualité est
hors de portée et entraîne une forte réduction de ce financement pendant
une vingtaine d’années
(Hutchins, 2003).ALPAC est l’Automatic Language Processing Advisory Committee, créé en 1964 et présidé par John R. Pierce, des Bell Telephone Laboratories ; sa seule préoccupation était le besoin du gouvernement américain de lire des documents russes. Le rapport lui-même est Language and Machines (National Research Council, 1966, doi:10.17226/9547) ; il concluait que « there is no immediate or predictable prospect of useful machine translation » [ma traduction : « il n’y a aucune perspective immédiate ou prévisible de traduction automatique utile »] et recommandait plutôt des aides informatiques pour les traducteurs et une meilleure évaluation (Hutchins, 2003).
Quelques systèmes sont tout de même construits, dont Météo, qui traduit les
bulletins météorologiques canadiens de l’anglais vers le français à partir
des années 1970, et Systran.
Vers 1990. Les méthodes statistiques arrivent, rendues possibles par de
grands corpus bilingues comme le Hansard, les débats du Parlement canadien
dans les deux langues.
2023. WMT, la Conference on Machine Translation, inclut pour la première
fois des grands modèles de langue parmi les systèmes de sa comparaison
annuelle (Kocmi et al., 2023) (see also the WMT shared task chapter, in the Machine translation module) (voir aussi le chapitre La tâche partagée WMT, dans le module Traduction automatique).
Les générations plus anciennes survivent là où les textes traduits qu’exige
un système neuronal n’existent pas : un domaine étroit, ou une paire de
langues qui en compte peu.
Sources
Hutchins, J. (2003). ALPAC: The (In)Famous Report. In S. Nirenburg, H. L. Somers & Y. A. Wilks (Eds.), Readings in Machine Translation (pp. 131–136). The MIT Press. https://doi.org/10.7551/mitpress/5779.003.0014
Hutchins, W. J. (2004). The Georgetown-IBM experiment demonstrated in January 1954. Proceedings of the 6th Conference of the Association for Machine Translation in the Americas: Technical Papers, 102–114. https://aclanthology.org/2004.amta-papers.12/
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2023). Findings of the 2023 Conference on Machine Translation (WMT23): LLMs Are Here but Not Quite There Yet. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), Singapore, 1–42. https://doi.org/10.18653/v1/2023.wmt-1.1
Machine translation in a translator's workLa traduction automatique dans le travail du traducteur
CAT tool, translation service or chatbot
Machine translation is requested from three kinds of place.
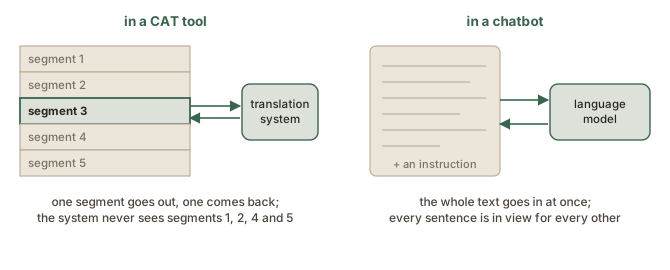
In a CAT tool. The tool divides the document into segments because its
translation memory works segment by segment, and the machine translation
connection sends those same segments, one at a time, so the system is given
one sentence with nothing before or after it. Only professional translators
work this way (see also the Wordfast: tags and machine translation chapter, in the CAT tools module) (voir aussi le chapitre Wordfast : balises et traduction automatique, dans le module Outils de TAO).
On a translation service, a website or an app, anyone pastes a sentence,
a paragraph or an entire file.
In a chatbot, the whole text goes in with an instruction.
The generation of the system decides how much of the surrounding text it
uses. Statistical and neural systems translate one sentence at a time
whatever they are given: a document pasted into a service
of that generation is cut into sentences, and each is translated in isolation,
as it would be in a CAT tool (see also the Neural translation page, in the Machine translation module) (voir aussi la page La traduction neuronale, dans le module Traduction automatique).
A large language model can take the whole text as its unit, so the
surrounding sentences are in view, and the errors change with it. Figure 5figure 5 shows the two extremes.
Figure 5. The same document translated segment by segment in a CAT tool and all at once in a chatbot.
a gender, a pronoun or a sense that the next sentence would have settled
a sentence or a paragraph dropped on the way; a passage smoothed into saying something slightly different
The two extremes compared: the input each gives the system and the errors each produces.
The pair of sentences below shows the first kind of error. A system that is
given only the first sentence has no way to settle the engineer’s gender,
which French needs in order to write ingénieur or ingénieure; the second
sentence settles it.
I spoke to the engineer this morning. She will send the drawings on Friday.
Läubli et al. (2018) found that raters comparing whole documents preferred
the human translation more clearly than raters comparing isolated sentences:
some errors of a fluent system only show once the surrounding sentences are
in view.
Post-editing
A person who corrects the draft a system produced is post-editing it.
For some uses the raw output is good enough: a text read once for its gist,
or a site where the reader is told that the translation was generated. In
the many cases where a wrong sentence has a cost, the output is a draft
whatever produced it, a neural system or a chatbot, and it has to be checked
against the source, because a fluent sentence does not show where it is
wrong (see also the Checking the answer page, in the Using LLMs module) (voir aussi la page Vérifier la réponse, dans le module Utiliser les GML).
The errors to expect depend on the generation that produced the draft: a term rendered by its most
common equivalent rather than the client’s, a calque of the source idiom, a
number or a name silently changed, a pronoun resolved the wrong way.
Unless you run a local translation system, any machine translation system
you use means that the texts you send for translation leave your computer and
go to the provider’s servers. The provider’s terms, the plan and your
settings decide what happens to them there (see also the Training, retention and privacy settings page, in the Using LLMs module) (voir aussi la page Entraînement, conservation et paramètres de confidentialité, dans le module Utiliser les GML).
Decide where the text goes before a client’s confidential document is pasted
anywhere.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Läubli, S., Sennrich, R., & Volk, M. (2018). Has machine translation achieved human parity? A case for document-level evaluation. Proceedings of EMNLP 2018, 4791–4796. https://aclanthology.org/D18-1512/
Moslem, Y., Haque, R., Kelleher, J. D., & Way, A. (2023). Adaptive Machine Translation with Large Language Models. Proceedings of the 24th Annual Conference of the European Association for Machine Translation (EAMT 2023), 227–237. https://aclanthology.org/2023.eamt-1.22/
Outil de TAO, service de traduction ou agent conversationnel
La traduction automatique est demandée depuis trois sortes d’endroits.
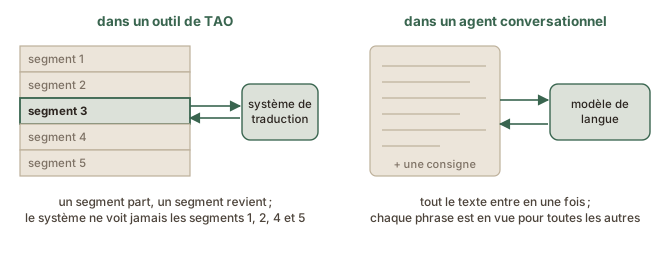
Dans un outil de TAO. L’outil découpe le document en segments parce que
sa mémoire de traduction fonctionne segment par segment, et la connexion de
traduction automatique envoie ces mêmes segments, un à la fois : le système
reçoit donc une phrase, sans rien avant ni après. Seuls les traducteurs
professionnels travaillent ainsi (see also the Wordfast: tags and machine translation chapter, in the CAT tools module) (voir aussi le chapitre Wordfast : balises et traduction automatique, dans le module Outils de TAO).
Sur un service de traduction, un site web ou une application, n’importe
qui colle une phrase, un paragraphe ou un fichier entier.
Dans un agent conversationnel, le texte entier entre avec une consigne.
La génération du système décide de la part du texte environnant qu’il
utilise. Les systèmes statistiques et neuronaux traduisent une phrase à la
fois, quoi qu’on leur donne : un document collé dans un service de cette
génération est découpé en phrases, et chacune est traduite isolément, comme
elle le serait dans un outil de TAO (see also the Neural translation page, in the Machine translation module) (voir aussi la page La traduction neuronale, dans le module Traduction automatique).
Un grand modèle de langue peut prendre le texte entier pour unité ; les
phrases voisines sont alors en vue, et les erreurs changent avec elles. La Figure 5figure 5 montre les deux extrêmes.
Figure 5. Le même document traduit segment par segment dans un outil de TAO et d'un seul coup dans un agent conversationnel.
un genre, un pronom ou un sens que la phrase suivante aurait tranché
une phrase ou un paragraphe perdu en route ; un passage lissé jusqu’à dire quelque chose de légèrement différent
Les deux extrêmes comparés : ce que chacun donne au système et les erreurs que chacun produit.
La paire de phrases ci-dessous montre le premier type d’erreur. Un système
qui ne reçoit que la première phrase n’a aucun moyen de trancher le genre de
la personne, que le français doit pourtant marquer pour écrire ingénieur ou
ingénieure ; la deuxième phrase le tranche.
I spoke to the engineer this morning. She will send the drawings on Friday.
Läubli et al. (2018) ont constaté que les évaluateurs qui comparaient des
documents entiers préféraient la traduction humaine plus nettement que ceux
qui comparaient des phrases isolées : certaines erreurs d’un système fluide
n’apparaissent que lorsque les phrases voisines sont en vue.
La postédition
Une personne qui corrige le brouillon produit par un système fait de la postédition.
Pour certains usages, le résultat brut suffit : un texte lu une fois pour en
saisir l’essentiel, ou un site où le lecteur est averti que la traduction a
été générée. Dans les nombreux cas où une phrase erronée a un coût, le
résultat est un brouillon, quel que soit le système qui l’a produit,
système neuronal ou agent conversationnel, et il doit être vérifié par
rapport à la source, parce qu’une phrase fluide ne montre pas où elle est
fausse (see also the Checking the answer page, in the Using LLMs module) (voir aussi la page Vérifier la réponse, dans le module Utiliser les GML).
Les erreurs à prévoir dépendent de la génération qui a produit le
brouillon : un terme rendu par son équivalent le plus courant plutôt que par
celui du client, un calque de l’expression idiomatique de la source, un
nombre ou un nom changé sans avertissement, un pronom résolu dans le mauvais
sens.
À moins d’utiliser un système de traduction local, tout système de traduction
automatique que vous employez implique que les textes que vous envoyez à
traduire quittent votre ordinateur pour les serveurs du fournisseur. Les
conditions du fournisseur, le forfait et vos réglages décident de ce qu’il en
advient (see also the Training, retention and privacy settings page, in the Using LLMs module) (voir aussi la page Entraînement, conservation et paramètres de confidentialité, dans le module Utiliser les GML).
Décidez où le texte va avant de coller le document confidentiel d’un client
où que ce soit.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Läubli, S., Sennrich, R., & Volk, M. (2018). Has machine translation achieved human parity? A case for document-level evaluation. Proceedings of EMNLP 2018, 4791–4796. https://aclanthology.org/D18-1512/
Moslem, Y., Haque, R., Kelleher, J. D., & Way, A. (2023). Adaptive Machine Translation with Large Language Models. Proceedings of the 24th Annual Conference of the European Association for Machine Translation (EAMT 2023), 227–237. https://aclanthology.org/2023.eamt-1.22/
Before neural networks: rules and statisticsAvant les réseaux de neurones : règles et statistiques
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
Rule-based translationLa traduction à base de règles
Dictionaries and rules
The first generation of systems translated the way a beginner with a
dictionary and a grammar might. For the green witch arrived, an
English-to-French system of this kind works through a list:
look each word up in its bilingual dictionary: the → la, green →
vert, witch → sorcière, arrived → est arrivée;
apply the rule that a French adjective follows its noun: sorcière vert;
apply the rule that it agrees in gender and number: sorcière verte;
assemble the sentence: la sorcière verte est arrivée.
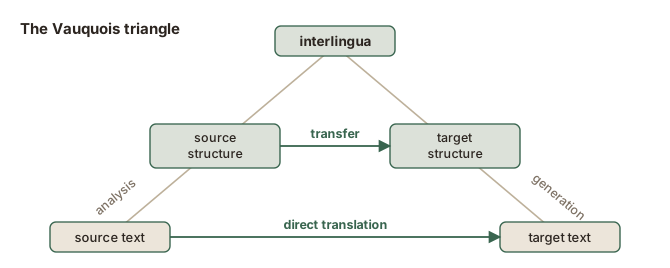
Jurafsky and Martin (2026) describe three designs, which differ in how much
of the source sentence is analyzed before anything is produced (Figure 1figure 1).
Figure 1. The Vauquois triangle, as given by Jurafsky and Martin (2026), who attribute it to Vauquois.
Design
Analysis before anything is written
Written for each language pair
Direct
nothing: the sentence is worked through word by word
a large bilingual dictionary whose every entry is a small program, translating one word and handling its reordering
Transfer
the grammatical structure of the source sentence
rules that turn a source structure into a target structure, then a generator, the part that writes the target sentence from that structure
Interlingua
the meaning, into a representation independent of both languages
in principle nothing specific to the pair: one analyzer per source language, one generator per target language
The three designs of rule-based translation.
Going up the triangle means more analysis on both sides and less knowledge
specific to the pair in the middle.
Strengths and limits
Strengths
Limits
Control. A wrong translation is traced to a rule or a dictionary entry, and corrected there.
Transparency. The path from the source to the output can be read, rule by rule.
Slow and expensive to build. In a direct or transfer system, each language pair and each direction needs its own dictionary and rules, written by linguists.
Hard to maintain. Rules interact, and a rule added for one case can break another.
The approach lost ground once enough translated text existed to learn from,
and it survives mainly for language pairs where that text does not exist.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Des dictionnaires et des règles
La première génération de systèmes traduisait comme le ferait un débutant
muni d’un dictionnaire et d’une grammaire. Pour the green witch arrived, un
système de ce type qui traduit de l’anglais vers le français suit une liste
d’étapes :
chercher chaque mot dans son dictionnaire bilingue : the → la,
green → vert, witch → sorcière, arrived → est arrivée ;
appliquer la règle selon laquelle l’adjectif français suit le nom :
sorcière vert ;
appliquer la règle d’accord en genre et en nombre : sorcière verte ;
assembler la phrase : la sorcière verte est arrivée.
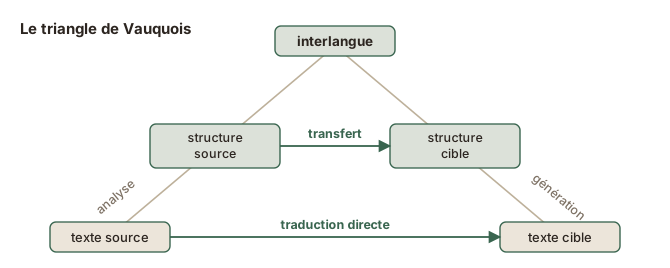
Jurafsky et Martin (2026) décrivent trois architectures, qui diffèrent par la
part de la phrase source analysée avant que quoi que ce soit soit produit
(Figure 1figure 1).
Figure 1. Le triangle de Vauquois, tel que le présentent Jurafsky et Martin (2026), qui l'attribuent à Vauquois.
Architecture
Analyse avant toute écriture
Ce qu’il faut écrire pour chaque paire de langues
Directe
aucune : la phrase est traitée mot par mot
un grand dictionnaire bilingue dont chaque entrée est un petit programme, qui traduit un mot et gère son déplacement dans la phrase
Transfert
la structure grammaticale de la phrase source
des règles qui transforment une structure source en structure cible, puis un générateur, la partie qui écrit la phrase cible à partir de cette structure
Interlangue
le sens, dans une représentation indépendante des deux langues
en principe rien de propre à la paire : un analyseur par langue source, un générateur par langue cible
Les trois architectures de la traduction à base de règles.
Plus on monte dans le triangle, plus l’analyse est poussée des deux côtés, et
moins il faut de connaissances propres à la paire de langues au milieu.
Forces et limites
Forces
Limites
Contrôle. Une traduction erronée se ramène à une règle ou à une entrée du dictionnaire, et se corrige à cet endroit.
Transparence. Le chemin de la phrase source au résultat se lit règle par règle.
Long et coûteux à construire. Dans un système direct ou à transfert, chaque paire de langues et chaque direction exigent leurs propres dictionnaire et règles, écrits par des linguistes.
Difficile à maintenir. Les règles interagissent, et une règle ajoutée pour un cas peut en défaire un autre.
Forces et limites de la traduction à base de règles.
L’approche a perdu du terrain dès que les textes traduits ont été assez
nombreux pour qu’on puisse en apprendre, et elle survit surtout pour les
paires de langues où ces textes n’existent pas.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
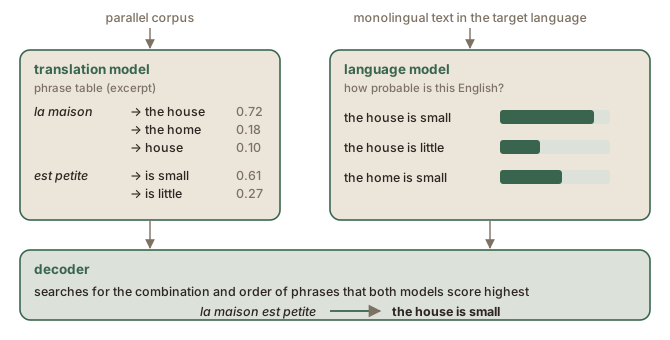
The parts of a statistical system are shown in Figure 2figure 2 (Jurafsky & Martin, 2026).
Figure 2. The three components of a statistical translation system. The phrase table and its probabilities are illustrative.
The translation model contains the bilingual knowledge: for each source
word or phrase, the target words or phrases paired with it in the corpus,
each with a probability. In the phrase-based systems that became
standard in the 2000s, this is a table of phrase pairs, the phrase table.
The decoder combines the two: it takes every phrase pair that matches
the source sentence and searches for the combination and order whose
probability is highest under both models together.
The reference textbook of this generation is Koehn (2010).
You can try the reasoning yourself on a menu in a language you do not read,
for example the four dishes in the table below. If you read Chinese, the
steps work the same way for a menu in any language you do not know.
On the menu
In English
虾仁炒饭
Shrimp fried rice
牛肉炒饭
Beef fried rice
牛肉面
Beef noodles
炒面
Fried noodles
Four dishes from a Chinese menu, with their English translations.
Two dishes are fried rice, and the only signs they have in common are
炒饭, so 炒饭 probably means fried rice.
Two dishes contain beef, and they have 牛肉 in common, so 牛肉 means
beef: two signs for one English word.
In 牛肉面, once 牛肉 is beef, the one sign left, 面, must be noodles.
In 炒面, once 面 is noodles, 炒 must be fried, which leaves 饭 in
炒饭 for rice.
In the first dish, 虾仁 is then the only candidate left for shrimp.
You have matched every sign to an English word without reading the menu,
only by comparing which signs and which English words occur together. Real
translations are less tidy: the same menu could translate 炒面 as chow
mein, and that dish would then tell you nothing about fried or noodles.
What the system does
A statistical system applies the same idea to millions of sentence pairs,
with counts in place of reasoning.
At the start, the system has no information about either language. Every word
of a source sentence is equally likely to translate every word of its
target sentence (Brown et al., 1993).
The system counts and recalculates, many times over. Words that keep
occurring in the same sentence pairs gain probability; once a word’s
translation is clear, the other words of the pair are left to share the
rest. The effect is close to the elimination you did on the menu. The
result is a word alignment: in each sentence pair, each word is paired
with its probable translation (Brown et al., 1993).
The system then collects phrase pairs, sequences of words that are
aligned only with each other, such as 炒面 and fried noodles (Koehn et
al., 2003).
The probability in the phrase table is a share. Of all the times a
source phrase was paired with something, it is the share of times it was
paired with this translation (Koehn et al., 2003). If 炒面 occurred
1 000 times, 700 times with fried noodles, 250 times with chow mein and
50 times with noodles, the three probabilities would be 0.70, 0.25 and
0.05 (illustrative numbers).
Whether the model produces text. In a statistical system the language
model does not produce any text of its own: the phrase table proposes the
candidates and the language model only scores them. An LLM produces the
text itself, one token at a time, by choosing among the tokens it gives a high
probability (see also the LLMs as next-word predictors chapter, in the LLM lifecycle module) (voir aussi le chapitre Les GML, prédicteurs du mot suivant, dans le module Cycle de vie des GML).
Dependence on the training data
The quality of a statistical system depends mainly on its training data:
the more translated words a system was trained on, the more reliable its
counts;
the closer the training data is to the text to translate, in domain and in
style, the better the output: a system trained on parliamentary proceedings
translates proceedings well and a product manual less well;
Brown, P. F., Della Pietra, S. A., Della Pietra, V. J., & Mercer, R. L. (1993). The Mathematics of Statistical Machine Translation: Parameter Estimation. Computational Linguistics, 19(2), 263–311. https://aclanthology.org/J93-2003/
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Koehn, P., Och, F. J., & Marcu, D. (2003). Statistical Phrase-Based Translation. Proceedings of the 2003 Human Language Technology Conference of the North American Chapter of the Association for Computational Linguistics, 127–133. https://aclanthology.org/N03-1017/
Tiedemann, J. (2012). Parallel Data, Tools and Interfaces in OPUS. Proceedings of the Eighth International Conference on Language Resources and Evaluation (LREC'12), Istanbul, 2214–2218. https://aclanthology.org/L12-1246/
Ziemski, M., Junczys-Dowmunt, M., & Pouliquen, B. (2016). The United Nations Parallel Corpus v1.0. Proceedings of the Tenth International Conference on Language Resources and Evaluation (LREC'16), Portorož, 3530–3534. https://aclanthology.org/L16-1561/
Modèle de traduction, modèle de langue et décodeur
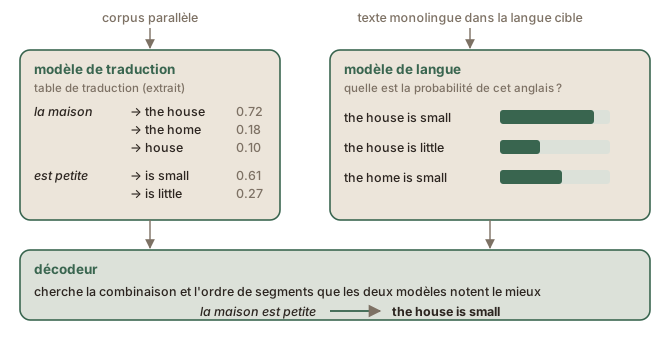
La Figure 2figure 2 présente les composantes d’un système statistique (Jurafsky & Martin, 2026).
Figure 2. Les trois composantes d'un système de traduction statistique. La table de traduction et ses probabilités sont fictives.
Le modèle de traduction contient les connaissances bilingues : pour
chaque mot ou segment source, les mots ou segments cibles qui lui sont
appariés dans le corpus, chacun avec une probabilité. Dans les systèmes
fondés sur les segments, devenus la norme dans les années 2000, il s’agit
d’une table de paires de segments, la table de traduction (angl. phrase
table).
Le décodeur combine les deux : il prend toutes les paires de segments qui
correspondent à la phrase source et cherche la combinaison et l’ordre dont la
probabilité est la plus élevée selon les deux modèles réunis.
L’ouvrage de référence de cette génération est celui de Koehn (2010).
Vous pouvez essayer ce raisonnement vous-même sur un menu dans une langue que
vous ne lisez pas, par exemple les quatre plats du tableau ci-dessous. Si vous
lisez le chinois, les étapes fonctionnent de la même façon avec un menu dans
n’importe quelle langue que vous ne connaissez pas.
Sur le menu
En français
虾仁炒饭
Riz sauté aux crevettes
牛肉炒饭
Riz sauté au bœuf
牛肉面
Nouilles au bœuf
炒面
Nouilles sautées
Quatre plats d'un menu chinois, avec leur traduction française.
Deux plats sont du riz sauté, et les seuls signes qu’ils ont en commun
sont 炒饭 : 炒饭 veut donc probablement dire riz sauté.
Deux plats contiennent du bœuf, et ils ont 牛肉 en commun : 牛肉 veut donc
dire bœuf, deux signes pour un seul mot français.
Dans 牛肉面, une fois 牛肉 identifié comme bœuf, le seul signe qui reste,
面, doit vouloir dire nouilles.
Dans 炒面, une fois 面 identifié comme nouilles, 炒 doit vouloir dire
sautées, ce qui laisse 饭, dans 炒饭, pour riz.
Dans le premier plat, 虾仁 est alors le seul candidat qui reste pour
crevettes.
Vous avez associé chaque signe à un mot français sans lire le menu,
uniquement en comparant quels signes et quels mots français apparaissent
ensemble. Les traductions réelles sont moins nettes : le même menu pourrait
traduire 炒面 par chow mein, et ce plat ne vous apprendrait alors rien sur
sautées ni sur nouilles.
Ce que fait le système
Un système statistique applique la même idée à des millions de paires de
phrases, avec des comptages à la place du raisonnement.
Au départ, le système ne dispose d’aucune information sur l’une ou l’autre langue. Chaque mot d’une
phrase source a autant de chances de traduire n’importe quel mot de sa
phrase cible (Brown et al., 1993).
Le système compte et recalcule, un grand nombre de fois. Les mots qui
reviennent sans cesse dans les mêmes paires de phrases gagnent en
probabilité ; une fois la traduction d’un mot établie, les autres mots de la
paire se partagent le reste. L’effet est proche de l’élimination que vous
avez faite sur le menu. Le résultat est un alignement des mots : dans
chaque paire de phrases, chaque mot est apparié à sa traduction probable
(Brown et al., 1993).
Le système recueille ensuite des paires de segments, des suites de mots
qui ne sont alignées qu’entre elles, comme 炒面 et nouilles sautées (Koehn
et al., 2003).
La probabilité dans la table de traduction est une proportion. Sur
toutes les fois où un segment source a été apparié à quelque chose, c’est la
proportion des fois où il a été apparié à cette traduction (Koehn et al.,
2003). Si 炒面 apparaissait 1 000 fois, dont 700 fois avec nouilles
sautées, 250 fois avec chow mein et 50 fois avec nouilles, les trois
probabilités seraient 0,70, 0,25 et 0,05 (chiffres fictifs).
Le modèle de langue et les grands modèles de langue
Si le modèle produit du texte. Dans un système statistique, le modèle de
langue ne produit aucun texte de lui-même : la table de traduction propose
les candidats, et le modèle de langue se contente de les noter. Un GML
produit lui-même le texte, un jeton à la fois, en choisissant parmi les
jetons auxquels il attribue une forte probabilité (see also the LLMs as next-word predictors chapter, in the LLM lifecycle module) (voir aussi le chapitre Les GML, prédicteurs du mot suivant, dans le module Cycle de vie des GML).
La dépendance aux données d’entraînement
La qualité d’un système statistique dépend surtout de ses données
d’entraînement :
plus le système a été entraîné sur un grand nombre de mots traduits, plus
ses comptages sont fiables ;
plus les données d’entraînement sont proches du texte à traduire, par le
domaine et par le style, meilleur est le résultat : un système entraîné sur
des débats parlementaires traduit bien des débats et moins bien un manuel de
produit ;
Brown, P. F., Della Pietra, S. A., Della Pietra, V. J., & Mercer, R. L. (1993). The Mathematics of Statistical Machine Translation: Parameter Estimation. Computational Linguistics, 19(2), 263–311. https://aclanthology.org/J93-2003/
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Koehn, P., Och, F. J., & Marcu, D. (2003). Statistical Phrase-Based Translation. Proceedings of the 2003 Human Language Technology Conference of the North American Chapter of the Association for Computational Linguistics, 127–133. https://aclanthology.org/N03-1017/
Tiedemann, J. (2012). Parallel Data, Tools and Interfaces in OPUS. Proceedings of the Eighth International Conference on Language Resources and Evaluation (LREC'12), Istanbul, 2214–2218. https://aclanthology.org/L12-1246/
Ziemski, M., Junczys-Dowmunt, M., & Pouliquen, B. (2016). The United Nations Parallel Corpus v1.0. Proceedings of the Tenth International Conference on Language Resources and Evaluation (LREC'16), Portorož, 3530–3534. https://aclanthology.org/L16-1561/
Neural translation and large language modelsLa traduction neuronale et les grands modèles de langue
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
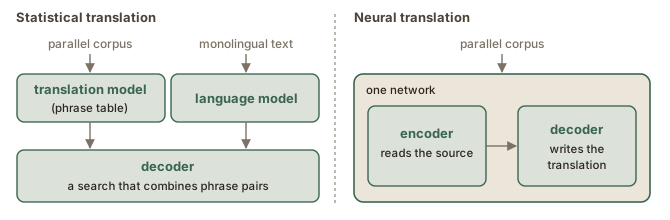
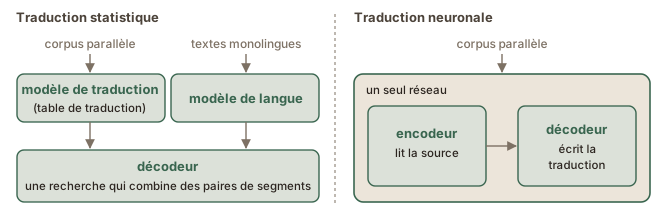
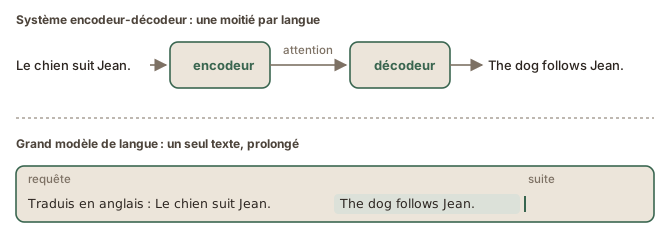
Figure 1. The three separate components of a statistical system and the single network of a neural one.
A decoder remains, but the word now names a different thing. In a statistical
system the decoder was the search that combined phrase pairs; in a neural
system it is the half of the network that writes the translation. The other
half, the encoder, reads the source sentence, and the design takes its name
from these two halves:
An encoder-decoder model turns one sequence of words into another. Models that
do this form a wider family, with a name of its own:
Translation is the typical case: the output is in another language, and often
differs from the source in length and word order.
Figure 2figure 2 follows one such sentence through a
transformer encoder-decoder, the design of today’s translation
systems (see also the Encoders and decoders page, in the Language as numbers module) (voir aussi la page Encodeurs et décodeurs, dans le module Le langage en nombres).
The source has six words and the translation five, a suivi becomes the
single word followed, and noir comes after chien where black comes
before dog.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 2. A transformer encoder-decoder translating one sentence, from the start signal to the fourth word.
In Figure 4figure 4, greedy decoding is stuck with the
literal have, while beam search also keeps am and finds I am hungry.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 4. Greedy decoding against beam search on one short sentence. The probabilities are illustrative.
Translation systems typically keep 5 to 10 candidate sentences open at once
(the beam width) and extend them in parallel (Jurafsky & Martin, 2026), so the
token that looked best at the first step can still lose to a candidate that
began with a less probable one. Beam search does not guarantee the best
sentence either: a candidate dropped early cannot come back.
Bahdanau, D., Cho, K., & Bengio, Y. (2015). Neural Machine Translation by Jointly Learning to Align and Translate. Third International Conference on Learning Representations (ICLR 2015), oral presentation; arXiv:1409.0473. https://arxiv.org/abs/1409.0473
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Figure 1. Les trois composantes séparées d'un système statistique et le réseau unique d'un système neuronal.
Un décodeur demeure, mais le mot désigne maintenant autre chose. Dans un
système statistique, le décodeur était la recherche qui combinait les paires
de segments ; dans un système neuronal, c’est la moitié du réseau qui écrit la
traduction. L’autre moitié, l’encodeur, lit la phrase source, et
l’architecture tire son nom de ces deux moitiés :
Un modèle encodeur-décodeur transforme une séquence de mots en une autre. Les
modèles qui font cela forment une famille plus large, qui a son propre nom :
La traduction en est le cas typique : le résultat est dans une autre langue,
et diffère souvent de la source par sa longueur et l’ordre des mots.
La Figure 2figure 2 suit une telle phrase à travers un
encodeur-décodeur à transformeur, l’architecture des systèmes de traduction
actuels (see also the Encoders and decoders page, in the Language as numbers module) (voir aussi la page Encodeurs et décodeurs, dans le module Le langage en nombres).
La source compte six mots et la traduction cinq, a suivi devient le seul mot
followed, et noir vient après chien alors que black vient avant dog.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 2. Un encodeur-décodeur à transformeur qui traduit une phrase, du signal de début au quatrième mot.
Dans la Figure 4figure 4, le décodage glouton reste prisonnier du
littéral have, alors que la recherche en faisceau garde aussi am et trouve
I am hungry.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 4. Le décodage glouton et la recherche en faisceau sur une courte phrase. Les probabilités sont fictives.
Les systèmes de traduction gardent généralement de 5 à 10 phrases candidates
ouvertes à la fois (la largeur du faisceau) et les prolongent en parallèle
(Jurafsky & Martin, 2026), si bien que le jeton qui semblait le meilleur à la
première étape peut perdre face à une candidate qui a commencé par un jeton
moins probable. La recherche en faisceau ne garantit pas non plus la
meilleure phrase : une candidate écartée tôt ne peut plus revenir.
Bahdanau, D., Cho, K., & Bengio, Y. (2015). Neural Machine Translation by Jointly Learning to Align and Translate. Third International Conference on Learning Representations (ICLR 2015), oral presentation; arXiv:1409.0473. https://arxiv.org/abs/1409.0473
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Fluent errors. A wrong word no longer announces itself, so an error is found mainly by comparing with the source. Läubli et al. (2018) found, on the neural systems of 2017, that evaluators preferred human translations more clearly when judging whole documents than isolated sentences.
Strengths and limits of neural translation compared with statistical translation.
Training data and domain
A neural system learns from the data it was trained on, so the same system
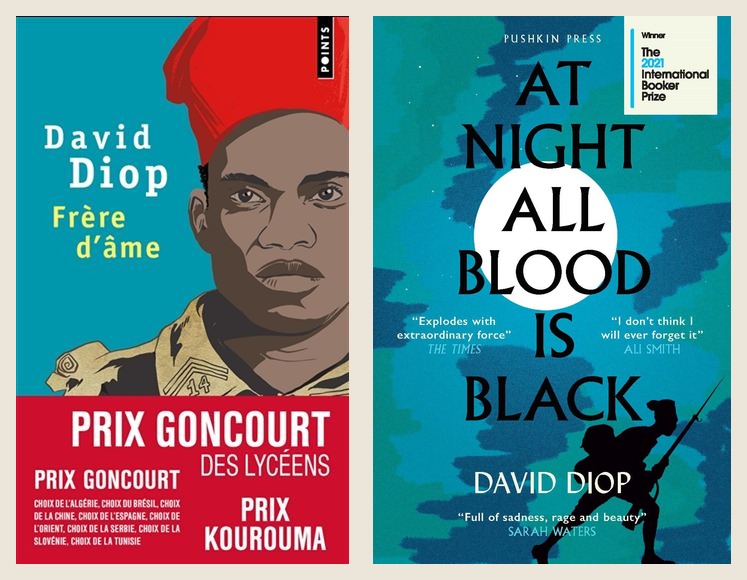
trained on different data gives different translations. The table below shows
a passage of a novel, David Diop’s Frère d’âme
(Figure 5figure 5),
in the published translation by Anna Moschovakis and as translated by two
general translation services and three versions of the European Commission’s
eTranslation service: the general one and two trained for a domain.
… je sais, j’ai compris, je n’aurais pas dû. Moi, Alfa Ndiaye, fils du très vieil homme, j’ai compris, je n’aurais pas dû.
Published translation (Moschovakis)
… I know, I understand, I shouldn’t have done it. I, Alfa Ndiaye, son of the old, old man, I understand, I shouldn’t have.
Google Translate
… I know, I understood, I shouldn’t have. I, Alfa Ndiaye, son of the very old man, I understood, I shouldn’t have.
DeepL
… I know, I get it, I shouldn’t have. I, Alfa Ndiaye, son of the very old man, I get it, I shouldn’t have.
eTranslation, general
… I know, I understood, I shouldn’t have. I, Alfa Ndiaye, son of the very old man, understood, I should not have.
eTranslation, Court of Justice case law
… I understand that I should not have done so. I, Alfa Ndiaye, son of the youngest man, have understood, I should not have done so.
eTranslation, finance
… I know, I understood, I would not have had to. I, Alfa Ndiaye, a son of a man’s life, I understood, I shouldn’t have had to do so.
One passage through two general translation services and three versions of eTranslation, all translated on 13 October 2026 with the free versions, eTranslation without its AI enhancement option.
The passage is not hard to translate: whatever its literary qualities, it
contains no rare word and no difficult structure. The three general systems
all translate it well. You may prefer the published translation, which is
a little less literal: the present tense (I understand), I shouldn’t have
done it, and the old, old man, which repeats old where the others say
very old. That is a matter of taste, though: the general systems’ versions
are perfectly adequate and contain no real error. The two
specialized versions of eTranslation make strange mistakes on the same
phrase, fils du très vieil homme, which becomes the youngest man in one and
a man’s life in the other: the prose of a novel is unlike the legal or
financial text they are presumably trained on. So for a well-resourced
language pair such as French and English, general systems translate
ordinary text well, but the training data still has to resemble the text to
translate (see also the Remaining failures page, in the Machine translation module) (voir aussi la page Les échecs qui subsistent, dans le module Traduction automatique).
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Läubli, S., Sennrich, R., & Volk, M. (2018). Has machine translation achieved human parity? A case for document-level evaluation. Proceedings of EMNLP 2018, 4791–4796. https://aclanthology.org/D18-1512/
Maruf, S., Saleh, F., & Haffari, G. (2021). A survey on document-level neural machine translation: Methods and evaluation. ACM Computing Surveys, 54(2), article 45. https://doi.org/10.1145/3441691
Voita, E., Sennrich, R., & Titov, I. (2019). When a good translation is wrong in context: Context-aware machine translation improves on deixis, ellipsis, and lexical cohesion. Proceedings of the 57th Annual Meeting of the ACL, 1198–1212. https://aclanthology.org/P19-1116/
Des erreurs fluides. Un mot erroné ne se signale plus de lui-même, et une erreur se repère surtout en comparant avec la source. Läubli et al. (2018) ont constaté, sur les systèmes neuronaux de 2017, que les évaluateurs préféraient plus nettement les traductions humaines quand ils jugeaient des documents entiers que des phrases isolées.
Forces et limites de la traduction neuronale par rapport à la traduction statistique.
Données d’entraînement et domaine
Un système neuronal apprend des données sur lesquelles il a été entraîné, si
bien que le même système, entraîné sur d’autres données, donne d’autres
traductions. Le tableau ci-dessous montre un passage d’un roman,
Frère d’âme de David Diop
(Figure 5figure 5),
dans la traduction publiée d’Anna Moschovakis et tel que l’ont traduit deux
services de traduction généraux et trois versions du service eTranslation de la
Commission européenne : la version générale et deux versions entraînées pour
un domaine.
… je sais, j’ai compris, je n’aurais pas dû. Moi, Alfa Ndiaye, fils du très vieil homme, j’ai compris, je n’aurais pas dû.
Traduction publiée (Moschovakis)
… I know, I understand, I shouldn’t have done it. I, Alfa Ndiaye, son of the old, old man, I understand, I shouldn’t have.
Google Traduction
… I know, I understood, I shouldn’t have. I, Alfa Ndiaye, son of the very old man, I understood, I shouldn’t have.
DeepL
… I know, I get it, I shouldn’t have. I, Alfa Ndiaye, son of the very old man, I get it, I shouldn’t have.
eTranslation, général
… I know, I understood, I shouldn’t have. I, Alfa Ndiaye, son of the very old man, understood, I should not have.
eTranslation, jurisprudence de la Cour de justice
… I understand that I should not have done so. I, Alfa Ndiaye, son of the youngest man, have understood, I should not have done so.
eTranslation, finance
… I know, I understood, I would not have had to. I, Alfa Ndiaye, a son of a man’s life, I understood, I shouldn’t have had to do so.
Un passage traduit par deux services de traduction généraux et par trois versions d'eTranslation, le 13 octobre 2026, avec les versions gratuites, et sans l'option d'amélioration par IA d'eTranslation.
Le passage n’est pas difficile à traduire : quelles que soient ses
qualités littéraires, il ne contient aucun mot rare ni aucune structure
difficile. Les trois systèmes généraux le traduisent tous bien. On peut préférer la
traduction publiée, un peu moins littérale : le présent (I understand),
I shouldn’t have done it, et the old, old man, qui répète old là où les
autres disent very old. C’est toutefois une affaire de goût : les
traductions des systèmes généraux sont tout à fait adéquates et ne contiennent
aucune véritable erreur. Les deux versions spécialisées d’eTranslation font des
erreurs étranges sur la même expression, fils du très vieil homme, qui
devient the youngest man (le plus jeune) dans l’une et a man’s life (une
vie d’homme) dans l’autre : la prose d’un roman ne ressemble pas aux textes
juridiques ou financiers sur lesquels elles ont vraisemblablement été
entraînées. Pour une paire de langues bien dotée comme le français et
l’anglais, les systèmes généraux traduisent donc bien un texte ordinaire,
mais les données d’entraînement doivent toujours ressembler au texte à
traduire (see also the Remaining failures page, in the Machine translation module) (voir aussi la page Les échecs qui subsistent, dans le module Traduction automatique).
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Läubli, S., Sennrich, R., & Volk, M. (2018). Has machine translation achieved human parity? A case for document-level evaluation. Proceedings of EMNLP 2018, 4791–4796. https://aclanthology.org/D18-1512/
Maruf, S., Saleh, F., & Haffari, G. (2021). A survey on document-level neural machine translation: Methods and evaluation. ACM Computing Surveys, 54(2), article 45. https://doi.org/10.1145/3441691
Voita, E., Sennrich, R., & Titov, I. (2019). When a good translation is wrong in context: Context-aware machine translation improves on deixis, ellipsis, and lexical cohesion. Proceedings of the 57th Annual Meeting of the ACL, 1198–1212. https://aclanthology.org/P19-1116/
Large language models as translatorsLes grands modèles de langue comme traducteurs
a network built for translation only, trained on parallel corpora
systems such as NLLB; the online services, evaluated anonymously, do not say which kind they are
General large language model
a model built for many tasks, prompted to translate
Gemini 2.5 Pro, GPT-4.1, Claude 4
Specialized large language model
a large language model fine-tuned on translation data, sometimes with retrieved examples, a dictionary or a choice among several candidate translations
Three kinds of translation system, with examples from WMT 2025.
Most teams that took part in 2025 fine-tuned a large language model rather
than building an encoder-decoder from scratch (Kocmi et al., 2025).
Some everyday services moved the same way: DeepL describes its model as a
large language model specialized for translation, and Google Translate has
used Gemini for some languages since December
2025.DeepL Help Center, “About DeepL’s language model”, read 8 October 2026. Google, “Google Translate gets new Gemini AI translation models”, 12 December 2025, read 8 October 2026. Microsoft’s translation service still uses standard neural machine translation by default (Microsoft Learn, read 8 October 2026).
A translation service and a chatbot can now differ mainly in specialization:
one system built and tuned for translation alone, against a general model
that you prompt.
When I present machine translation systems, I want to show where they still
fail now that they have become good, and they often fail on specialized
terms. So I wrote a short message of my own, full of dressage vocabulary,
and I translate it again each time I update my examples. Over the years this
has become a timeline of one text through several generations of systems.
The first message is in Dutch, from when I worked mostly with Dutch-speaking
audiences; I added an English message, to translate into French, when I
started at a French-speaking university. I translated both myself as the
reference.
The timeline is anecdotal: one message in each direction, a few runs of each
system, judged by me. It still shows how the systems changed, and how
differently each one handles text of this kind. In 2023 all three services
were neural translation systems (see also the Neural translation page, in the Machine translation module) (voir aussi la page La traduction neuronale, dans le module Traduction automatique). DeepL and Google Translate have since added large
language models, as described above, so their later outputs, made with the
free versions, may or may not come from one.DeepL, “DeepL’s next-gen LLM”, last updated 16 July 2024, read 13 October 2026: Pro users “can switch between the next-gen LLM and ‘classic’ model”. Google, “Google Translate gets new Gemini AI translation models”, 12 December 2025, read 8 October 2026. eTranslation, the
European Commission’s service, was used without its AI enhancement option.
It is a good system, but it is trained on the translations of the EU
institutions, where dressage rarely comes up, so a message like this one is
far from the text it learned from (see also the Strengths and limits of neural translation page, in the Machine translation module) (voir aussi la page Forces et limites de la traduction neuronale, dans le module Traduction automatique).European Commission, “eTranslation”: “a neural machine translation tool trained on EU professional translation data”, read 13 October 2026.
Each term in the outputs is marked correct (correctcorrect),
acceptable or partly right (acceptable or partly rightacceptable ou en partie juste) or
wrong (wrongfaux).
Dutch into English
The Dutch message is Ik zal haar eerst aan de longe nemen om te leren
lichtrijden op het buitenbeen. Zorg dat ze een tok heeft en ik doe alvast
getten om. Heb jij nog een sjabrak? It contains aan de longe nemen (to
lunge; here, to give a riding lesson on a horse on the lunge), lichtrijden op het buitenbeen
(to post the trot on the correct diagonal), tok (a riding hat), getten
(protective boots for the horse’s legs) and sjabrak (a saddle pad).
System
Date
longe
lichtrijden
op het buitenbeen
tok
getten
sjabrak
Reference
lunge
post (the trot)
on the correct diagonal
riding hat
boots
saddle pad
Google Translate
2023
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
ride light (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
getten (wrongfaux)
shabrack (acceptable or partly rightacceptable ou en partie juste)
2025
lunging (correctcorrect)
ride lightly (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
riding helmet (correctcorrect)
saddle pads (wrongfaux)
saddle pad (correctcorrect)
2026‑10
lunge (correctcorrect)
rise (correctcorrect)
to the outside leg (acceptable or partly rightacceptable ou en partie juste)
helmet (correctcorrect)
brushing boots (correctcorrect)
saddle pad (correctcorrect)
DeepL
2023
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
ride lightly (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
getten (wrongfaux)
shawl (wrongfaux)
2025
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
ride lightly (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
bridle (wrongfaux)
stirrups (wrongfaux)
saddlecloth (correctcorrect)
2026‑10
lunging (correctcorrect)
move lightly (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
halter (wrongfaux)
girth (wrongfaux)
saddle pad (correctcorrect)
eTranslation
2023
take her to (wrongfaux) the lung (wrongfaux)
ride light (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
I’m going to get it (wrongfaux)
shabrak (acceptable or partly rightacceptable ou en partie juste)
2025
take her to (wrongfaux) the lungs (wrongfaux)
ride lightly (wrongfaux)
on the outer leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
I’ll get the hell out of here (wrongfaux)
shabrak (acceptable or partly rightacceptable ou en partie juste)
2026‑10
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
light riding (wrongfaux)
on the outer leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
I’ll get bitten on (wrongfaux)
shabrak (acceptable or partly rightacceptable ou en partie juste)
ChatGPT
2023‑02
take her on (acceptable or partly rightacceptable ou en partie juste) a lunge line (correctcorrect)
ride light (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
martingale (wrongfaux)
getting ready (wrongfaux)
saddle pad (correctcorrect)
2023‑03
lunge (correctcorrect)
ride with (wrongfaux)
the correct diagonal (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste)
helmet (correctcorrect)
leg wraps (correctcorrect)
saddle pad (correctcorrect)
2023‑03 (GPT-4)
lunge (correctcorrect)
post (correctcorrect)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
cup (wrongfaux)
gaiters (wrongfaux)
saddle pad (correctcorrect)
2024‑03
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
post (correctcorrect)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
jockstrap (wrongfaux)
gaiters (wrongfaux)
saddle pad (correctcorrect)
2024‑05
lunge (correctcorrect)
post (correctcorrect)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
helmet (correctcorrect)
protective boots (correctcorrect)
saddle pad (correctcorrect)
2025‑09
lunge (correctcorrect)
post (correctcorrect)
on the outside diagonal (correctcorrect)
helmet (correctcorrect)
boots (correctcorrect)
saddle pad (correctcorrect)
2026‑01
lunge (correctcorrect)
rising trot (correctcorrect)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
riding helmet (correctcorrect)
my gaiters (wrongfaux)
saddle pad (correctcorrect)
2026‑01, second run
lunge (correctcorrect)
rise (correctcorrect)
on the outside foreleg (acceptable or partly rightacceptable ou en partie juste)
riding hat (correctcorrect)
my half chaps (wrongfaux)
saddle pad (correctcorrect)
2026‑10
lunge line (correctcorrect)
post (correctcorrect)
on the outside diagonal (correctcorrect)
riding helmet (correctcorrect)
brushing boots (correctcorrect)
saddle pad (correctcorrect)
The terms of the Dutch message in each output.
The complete outputs
System
Date
Output
Source
Ik zal haar eerst aan de longe nemen om te leren lichtrijden op het buitenbeen. Zorg dat ze een tok heeft en ik doe alvast getten om. Heb jij nog een sjabrak?
Reference
I will start by teaching her on the lunge how to post (the trot) on the correct diagonal. Make sure she has a riding hat, and I will already put the boots on. Do you have another saddle pad?
Google Translate
2023
I will first take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) to learn how to ride light (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a tok (wrongfaux) and I’ll put on getten (wrongfaux). Do you still have a shabrack (acceptable or partly rightacceptable ou en partie juste)?
2025
I’ll start by lunging (correctcorrect) her to learn how to ride lightly (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a riding helmet (correctcorrect), and I’ll put on the saddle pads (wrongfaux). Do you still have a saddle pad (correctcorrect)?
2026‑10
I’ll put her on the lunge (correctcorrect) first so she can learn to rise (correctcorrect)to the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a helmet (correctcorrect), and I’ll put on her brushing boots (correctcorrect). Do you have a saddle pad (correctcorrect)?
DeepL
2023
I will take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) first to learn to ride lightly (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a tok (wrongfaux) and I’ll put on getten (wrongfaux) in advance. Do you still have a shawl (wrongfaux)?
2025
I will first take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) to teach her to ride lightly (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a bridle (wrongfaux) and I will put on the stirrups (wrongfaux). Do you have a saddlecloth (correctcorrect)?
2026‑10
I’ll start by lunging (correctcorrect) her to teach her to move lightly (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a halter (wrongfaux) on, and I’ll go ahead and put the girth (wrongfaux) on. Do you have a saddle pad (correctcorrect)?
eTranslation
2023
I’ll take her to (wrongfaux) the lung (wrongfaux) first to learn how to ride light (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she’s got a tok (wrongfaux), and I’m going to get it (wrongfaux). Do you have another shabrak (acceptable or partly rightacceptable ou en partie juste)?
2025
I’ll take her to (wrongfaux) the lungs (wrongfaux) first to learn how to ride lightly (wrongfaux)on the outer leg (acceptable or partly rightacceptable ou en partie juste). Make sure she’s got a tok (wrongfaux), and I’ll get the hell out of here (wrongfaux). Do you have another shabrak (acceptable or partly rightacceptable ou en partie juste)?
2026‑10
I’ll take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) first to learn light riding (wrongfaux)on the outer leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a tok (wrongfaux) and I’ll get bitten on (wrongfaux). Do you have another shabrak (acceptable or partly rightacceptable ou en partie juste)?
ChatGPT
2023‑02
I will first take her on (acceptable or partly rightacceptable ou en partie juste) a lunge line (correctcorrect) to teach her to ride light (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a martingale (wrongfaux) and I’ll start getting ready (wrongfaux). Do you have a saddle pad (correctcorrect)?
2023‑03
I will first lunge (correctcorrect) her to teach her how to ride with (wrongfaux)the correct diagonal (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a helmet (correctcorrect) and I will put on leg wraps (correctcorrect). Do you have a saddle pad (correctcorrect)?
2023‑03 (GPT-4)
I will first lunge (correctcorrect) her to teach her to post (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a cup (wrongfaux), and I will put on the gaiters (wrongfaux) already. Do you have an extra saddle pad (correctcorrect)?
2024‑03
I will first take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) to learn to post (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a jockstrap (wrongfaux), and I will already put on gaiters (wrongfaux). Do you have another saddle pad (correctcorrect)?
2024‑05
I will lunge (correctcorrect) her first to teach her to post (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a helmet (correctcorrect), and I will put on the protective boots (correctcorrect). Do you still have a saddle pad (correctcorrect)?
2025‑09
I’ll lunge (correctcorrect) her first to teach her to post on the outside diagonal (correctcorrect). Make sure she’s got a helmet (correctcorrect), and I’ll go ahead and put on the boots (correctcorrect). Do you have a saddle pad (correctcorrect)?
2026‑01
I’ll put her on the lunge (correctcorrect) first so she can learn to ride rising trot (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a riding helmet (correctcorrect) on, and I’ll put my gaiters (wrongfaux) on already. Do you still have a saddle pad (correctcorrect)?
2026‑01, second run
I’ll lunge (correctcorrect) her first so she can learn to rise (correctcorrect)on the outside foreleg (acceptable or partly rightacceptable ou en partie juste). Make sure she’s wearing her riding hat (correctcorrect), and I’ll put my half chaps (wrongfaux) on. Do you have a saddle pad (correctcorrect) as well?
2026‑10
I’ll put her on the lunge line (correctcorrect) first so she can learn to post on the outside diagonal (correctcorrect). Make sure she has a riding helmet (correctcorrect), and I’ll put the brushing boots (correctcorrect) on in the meantime. Do you have another saddle pad (correctcorrect)?
One Dutch message translated by three online translation services in 2023, 2025 and 2026-10, with their free versions, and by ChatGPT between 2023 and 2026, each time with the latest model offered by the basic paid subscription at the time and the prompt *translate into English:* followed by the message; the 2026-10 output with the medium effort setting, in a temporary chat.
Riding words that do not belong. Several outputs replaced a term with
riding vocabulary that has nothing to do with the message, as if any word
from the domain would do: a martingale (ChatGPT, 2023), a bridle and
stirrups (DeepL, 2025), a halter and a girth (DeepL, 2026).
Word for word, or not at all. In 2023 all three services left tok
and getten untranslated or turned them into something else
(eTranslation’s I’m going to get it). Every service output but Google
Translate’s of 2026 rendered lichtrijden as ride light, ride lightly,
move lightly or light riding.
The services moved apart. By 2026-10 Google Translate had almost
every term right, DeepL’s output had changed without improving, and
eTranslation had found only the lunge.
ChatGPT improved, but not steadily. In 2023-02 it produced a
martingale and getting ready; a month later it already had the helmet, the leg wraps
and the correct diagonal, while GPT-4, released that month, gave the rider a
cup. Most terms were right by 2024-05 and all of them by 2025-09. Neither
output of 2026-01 had the correct diagonal, and both turned getten into
something the speaker wears; in 2026-10 every term was right again. A
newer system can get a term wrong that an older one got right.
English into French
The English message is I’ll start her on the lunge line to learn to post
the trot on the correct diagonal. When you take her to him, make sure to
explain his cribbing and to clean his feathers and treat his frogs to avoid
thrush. How are your lead changes going? Are you doing flying changes yet?
It has a dressage term in every clause.
System
Date
lunge line
post the trot on the correct diagonal
cribbing
feathers
frogs
thrush
flying changes
Reference
à la longe
le trot enlevé sur le bon diagonal
fait un tic à l’appui
fanons
fourchettes
pourriture de la fourchette
changements de pied en l’air
Google Translate
2025
à la longe (correctcorrect)
placer le trot sur la bonne diagonale (wrongfaux)
s’accroupit (wrongfaux)
plumes (wrongfaux)
fourchettes (correctcorrect)
grives (wrongfaux)
changements de pied en vol (wrongfaux)
2026‑10
à la longe (correctcorrect)
trotter enlevé (correctcorrect)sur la bonne diagonale (wrongfaux)
tic d’appui (acceptable or partly rightacceptable ou en partie juste)
fanons (correctcorrect)
fourchettes (correctcorrect)
pourrissement (acceptable or partly rightacceptable ou en partie juste)
au galop (acceptable or partly rightacceptable ou en partie juste)
DeepL
2025
à la longe (correctcorrect)
prendre le trot dans la bonne diagonale (wrongfaux)
fait des crèches (wrongfaux)
plumes (wrongfaux)
grenouilles (wrongfaux)
muguet (wrongfaux)
changements en vol (wrongfaux)
2026‑10
à la longe (correctcorrect)
se lever au trot (acceptable or partly rightacceptable ou en partie juste)sur la bonne diagonale (wrongfaux)
problème de mordillage (wrongfaux)
crins (acceptable or partly rightacceptable ou en partie juste)
sabots (acceptable or partly rightacceptable ou en partie juste)
pourriture de la fourchette (correctcorrect)
changements au galop (acceptable or partly rightacceptable ou en partie juste)
eTranslation
2026‑10
ligne de fente (wrongfaux)
poser le trot sur la bonne diagonale (wrongfaux)
cribbing (wrongfaux)
plumes (wrongfaux)
grenouilles (wrongfaux)
muguet (wrongfaux)
changements de vol (wrongfaux)
ChatGPT
2025‑01 (GPT-4o)
sur la longe (acceptable or partly rightacceptable ou en partie juste)
trotter en levée (acceptable or partly rightacceptable ou en partie juste)sur la bonne diagonale (wrongfaux)
tic à l’appui (cribbing) (correctcorrect)
fanons (correctcorrect)
fourchettes (correctcorrect)
pourriture (correctcorrect)
changements de pied au vol (wrongfaux)
2026‑02 (GPT-5.2)
à la longe (correctcorrect)
trotter enlevé sur le bon diagonal (correctcorrect)
tic à l’appui (correctcorrect)
fanons (correctcorrect)
fourchettes (correctcorrect)
pourriture de fourchette (correctcorrect)
changements de pied (correctcorrect)au temps (wrongfaux) (en l’air (correctcorrect))
2026‑10
à la longe (correctcorrect)
trotter enlevé sur le bon diagonal (correctcorrect)
tique à l’appui (correctcorrect)
fanons (correctcorrect)
fourchettes (correctcorrect)
pourriture de la fourchette (correctcorrect)
changements de pied en l’air (correctcorrect)
The terms of the English message in each French output. *Lead changes* is left out: every output has *changements de pied*, except eTranslation's *changements de leads*.
The complete outputs
System
Date
Output
Source
I’ll start her on the lunge line to learn to post the trot on the correct diagonal. When you take her to him, make sure to explain his cribbing and to clean his feathers and treat his frogs to avoid thrush. How are your lead changes going? Are you doing flying changes yet?
Reference
Je vais commencer par la travailler à la longe pour qu’elle apprenne le trot enlevé sur le bon diagonal. Quand tu l’emmèneras vers lui, n’oublie pas de préciser qu’il fait un tic à l’appui et de bien nettoyer ses fanons, puis de traiter ses fourchettes afin d’éviter la pourriture de la fourchette. Comment avancent tes changements de pied ? Est-ce que tu fais déjà des changements de pied en l’air ?
Google Translate
2025
Je vais la démarrer à la longe (correctcorrect) pour lui apprendre à placer le trot sur la bonne diagonale (wrongfaux). Lorsque vous l’amènerez chez lui, assurez-vous de lui expliquer comment il s’accroupit (wrongfaux), de nettoyer ses plumes (wrongfaux) et de traiter ses fourchettes (correctcorrect) pour éviter les grives (wrongfaux). Comment se passent vos changements de pied (correctcorrect) ? Faites-vous déjà des changements de pied en vol (wrongfaux) ?
2026‑10
Je vais commencer à la travailler à la longe (correctcorrect) pour qu’elle apprenne à trotter enlevé (correctcorrect)sur la bonne diagonale (wrongfaux). Lorsque tu l’emmèneras vers lui, n’oublie pas d’expliquer son tic d’appui (acceptable or partly rightacceptable ou en partie juste), de nettoyer ses fanons (correctcorrect) et de soigner ses fourchettes (correctcorrect) pour éviter le pourrissement (acceptable or partly rightacceptable ou en partie juste). Comment se passent les changements de pied (correctcorrect) ? En faites-vous déjà au galop (acceptable or partly rightacceptable ou en partie juste) ?
DeepL
2025
Je la mettrai à la longe (correctcorrect) pour qu’elle apprenne à prendre le trot dans la bonne diagonale (wrongfaux). Lorsque vous l’emmènerez chez lui, n’oubliez pas de lui expliquer qu’il fait des crèches (wrongfaux), de nettoyer ses plumes (wrongfaux) et de traiter ses grenouilles (wrongfaux) pour éviter le muguet (wrongfaux). Comment se passent les changements de pied (correctcorrect) ? Faites-vous déjà des changements en vol (wrongfaux) ?
2026‑10
Je vais commencer par la travailler à la longe (correctcorrect) pour qu’elle apprenne à se lever au trot (acceptable or partly rightacceptable ou en partie juste)sur la bonne diagonale (wrongfaux). Quand tu l’emmèneras chez lui, n’oublie pas de lui expliquer son problème de mordillage (wrongfaux), de nettoyer ses crins (acceptable or partly rightacceptable ou en partie juste) et de soigner ses sabots (acceptable or partly rightacceptable ou en partie juste) pour éviter la pourriture de la fourchette (correctcorrect). Comment se passent tes changements de pied (correctcorrect) ? Tu fais déjà des changements au galop (acceptable or partly rightacceptable ou en partie juste) ?
eTranslation
2026‑10
Je la mettrai sur la ligne de fente (wrongfaux) pour apprendre à poser le trot sur la bonne diagonale (wrongfaux). Lorsque vous l’emmenez chez lui, assurez-vous d’expliquer son cribbing (wrongfaux) et de nettoyer ses plumes (wrongfaux) et de traiter ses grenouilles (wrongfaux) pour éviter le muguet (wrongfaux). Comment vont vos changements de leads (wrongfaux) ? Êtes-vous en train de faire des changements de vol (wrongfaux) encore ?
ChatGPT
2025‑01 (GPT-4o)
Je vais commencer par la mettre sur la longe (acceptable or partly rightacceptable ou en partie juste) pour qu’elle apprenne à trotter en levée (acceptable or partly rightacceptable ou en partie juste)sur la bonne diagonale (wrongfaux). Quand tu l’emmènes chez lui, assure-toi d’expliquer son tic à l’appui (cribbing) (correctcorrect) et de nettoyer ses fanons (correctcorrect) ainsi que de traiter ses fourchettes (correctcorrect) pour éviter la pourriture (correctcorrect). Comment se passent tes changements de pied (correctcorrect) ? Fais-tu déjà des changements de pied au vol (wrongfaux) ?
2026‑02 (GPT-5.2)
Je vais d’abord la mettre à la longe (correctcorrect) pour qu’elle apprenne à trotter enlevé sur le bon diagonal (correctcorrect). Quand tu l’emmèneras chez lui, assure-toi de lui expliquer qu’il tic à l’appui (correctcorrect) et de nettoyer ses fanons (correctcorrect), puis de soigner ses fourchettes (correctcorrect) pour éviter la pourriture de fourchette (correctcorrect). Comment vont tes changements de pied (correctcorrect) ? Tu fais déjà des changements de pied (correctcorrect)au temps (wrongfaux) (en l’air (correctcorrect)) ?
2026‑10
Je vais commencer par la faire travailler à la longe (correctcorrect) pour qu’elle apprenne à trotter enlevé sur le bon diagonal (correctcorrect). Quand tu l’emmèneras chez lui, assure-toi de bien lui expliquer qu’il tique à l’appui (correctcorrect), de nettoyer ses fanons (correctcorrect) et de traiter ses fourchettes (correctcorrect) pour éviter la pourriture de la fourchette (correctcorrect). Comment ça se passe, tes changements de pied (correctcorrect) ? Tu fais déjà des changements de pied en l’air (correctcorrect) ?
One English message translated into French by three online translation services in 2025 and 2026-10, with their free versions, and by ChatGPT in 2025 and 2026, with the prompt *translate into French:* followed by the message; the 2026-10 output with the medium effort setting, in a temporary chat.
In 2025 the services translated the words. Both rendered post the
trot word for word and flying changes as en vol. Google Translate
turned feathers into plumes and thrush into grives, the bird; DeepL
turned frogs into grenouilles, the animal, and thrush into muguet,
the yeast infection of the human mouth that English also calls thrush.
By 2026-10 the services had moved apart. Google Translate had most of
the riding terms, apart from la bonne diagonale, where riders say le bon
diagonal, and two forms close to the term without being it, tic d’appui
and pourrissement. DeepL found the lunge and the thrush, but turned
cribbing into mordillage, feathers into crins, horsehair in
general, and frogs into sabots, the whole hoof. eTranslation still
translated the words: a ligne de fente for the lunge line, plumes,
grenouilles and muguet, and cribbing left as it was.
ChatGPT had most of the riding terms without being told the domain.
In 2025-01, ChatGPT-4o already had tic à l’appui, fanons and
fourchettes, but not the trot or the flying changes. In 2026-02,
ChatGPT-5.2 had every term right except au temps, which names a different
flying change, and in 2026-10 every term was right (see also the Prompting an LLM for translation page, in the Machine translation module) (voir aussi la page Rédiger une requête de traduction pour un GML, dans le module Traduction automatique).
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
un réseau conçu uniquement pour la traduction, entraîné sur des corpus parallèles
des systèmes comme NLLB ; les services en ligne, évalués de façon anonyme, ne disent pas de quel type ils sont
Grand modèle de langue général
un modèle conçu pour de nombreuses tâches, à qui la requête demande de traduire
Gemini 2.5 Pro, GPT-4.1, Claude 4
Grand modèle de langue spécialisé
un grand modèle de langue affiné sur des données de traduction, parfois avec des exemples retrouvés, un dictionnaire ou un choix parmi plusieurs traductions candidates
Trois types de systèmes de traduction, avec des exemples tirés de WMT 2025.
La plupart des équipes participantes de 2025 ont affiné un grand modèle de
langue plutôt que de construire entièrement un système encodeur-décodeur
(Kocmi et al., 2025).
Certains services courants ont pris la même direction : DeepL décrit son
modèle comme un grand modèle de langue spécialisé en traduction, et Google
Traduction utilise Gemini pour certaines langues depuis décembre
2025.Centre d’aide de DeepL, « About DeepL’s language model », consulté le 8 octobre 2026. Google, « Google Translate gets new Gemini AI translation models », 12 décembre 2025, consulté le 8 octobre 2026. Le service de traduction de Microsoft utilise encore par défaut une traduction automatique neuronale classique (Microsoft Learn, consulté le 8 octobre 2026).
Un service de traduction et un agent conversationnel peuvent donc désormais
différer surtout par leur spécialisation : un système conçu et réglé pour
la seule traduction, face à un modèle général à qui l’on adresse une
requête.
Quand je présente les systèmes de traduction automatique, je veux montrer où
ils échouent encore maintenant qu’ils sont devenus bons, et ils échouent
souvent sur les termes spécialisés. J’ai donc écrit un court message, rempli de
vocabulaire du dressage, que je fais traduire de nouveau chaque fois que je
mets mes exemples à jour. Au fil des ans, cela donne une chronologie d’un même
texte à travers plusieurs générations de systèmes. Le premier message est en
néerlandais, de l’époque où je travaillais surtout avec un public
néerlandophone ; j’ai ajouté un message en anglais, à traduire en français,
quand j’ai commencé à enseigner dans une université francophone. J’ai traduit
les deux moi-même pour obtenir les références.
Cette chronologie est anecdotique : un message dans chaque sens, quelques
essais de chaque système, jugés par moi. Elle montre tout de même comment les
systèmes ont évolué, et à quel point chacun traite différemment un texte de ce
genre. En 2023, les trois services étaient des systèmes de traduction
neuronale (see also the Neural translation page, in the Machine translation module) (voir aussi la page La traduction neuronale, dans le module Traduction automatique). DeepL et Google Traduction ont depuis ajouté des
grands modèles de langue, comme on l’a vu plus haut, si bien que leurs
résultats plus récents, obtenus avec les versions gratuites, viennent
peut-être d’un tel modèle, peut-être pas.DeepL, « DeepL’s next-gen LLM », dernière mise à jour le 16 juillet 2024, consulté le 13 octobre 2026 : les utilisateurs de la version Pro « can switch between the next-gen LLM and ‘classic’ model » [ma traduction : « peuvent passer du grand modèle de langue de nouvelle génération au modèle “classique” »]. Google, « Google Translate gets new Gemini AI translation models », 12 décembre 2025, consulté le 8 octobre 2026. eTranslation, le service de la
Commission européenne, a été utilisé sans son option d’amélioration par IA.
C’est un bon système, mais il est entraîné sur les traductions des
institutions de l’UE, où il est rarement question de dressage, si bien qu’un
message comme celui-ci est loin des textes dont il a
appris (see also the Strengths and limits of neural translation page, in the Machine translation module) (voir aussi la page Forces et limites de la traduction neuronale, dans le module Traduction automatique).Commission européenne, « eTranslation » : « a neural machine translation tool trained on EU professional translation data » [ma traduction : « un outil de traduction automatique neuronale entraîné sur des données de traduction professionnelle de l’UE »], consulté le 13 octobre 2026.
Chaque terme des résultats est marqué comme correct (correctcorrect),
acceptable ou en partie juste (acceptable or partly rightacceptable ou en partie juste) ou
faux (wrongfaux).
Du néerlandais vers l’anglais
Le message néerlandais est Ik zal haar eerst aan de longe nemen om te
leren lichtrijden op het buitenbeen. Zorg dat ze een tok heeft en ik doe
alvast getten om. Heb jij nog een sjabrak? Il contient aan de longe nemen
(travailler à la longe ; ici, donner une leçon à une cavalière sur un
cheval tenu à la longe),
lichtrijden op het buitenbeen (trotter enlevé sur le bon diagonal), tok
(une bombe d’équitation), getten (des guêtres, qui protègent les membres du
cheval) et sjabrak (un tapis de selle).
Système
Date
longe
lichtrijden
op het buitenbeen
tok
getten
sjabrak
Référence
lunge
post (the trot)
on the correct diagonal
riding hat
boots
saddle pad
Google Traduction
2023
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
ride light (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
getten (wrongfaux)
shabrack (acceptable or partly rightacceptable ou en partie juste)
2025
lunging (correctcorrect)
ride lightly (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
riding helmet (correctcorrect)
saddle pads (wrongfaux)
saddle pad (correctcorrect)
2026‑10
lunge (correctcorrect)
rise (correctcorrect)
to the outside leg (acceptable or partly rightacceptable ou en partie juste)
helmet (correctcorrect)
brushing boots (correctcorrect)
saddle pad (correctcorrect)
DeepL
2023
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
ride lightly (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
getten (wrongfaux)
shawl (wrongfaux)
2025
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
ride lightly (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
bridle (wrongfaux)
stirrups (wrongfaux)
saddlecloth (correctcorrect)
2026‑10
lunging (correctcorrect)
move lightly (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
halter (wrongfaux)
girth (wrongfaux)
saddle pad (correctcorrect)
eTranslation
2023
take her to (wrongfaux) the lung (wrongfaux)
ride light (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
I’m going to get it (wrongfaux)
shabrak (acceptable or partly rightacceptable ou en partie juste)
2025
take her to (wrongfaux) the lungs (wrongfaux)
ride lightly (wrongfaux)
on the outer leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
I’ll get the hell out of here (wrongfaux)
shabrak (acceptable or partly rightacceptable ou en partie juste)
2026‑10
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
light riding (wrongfaux)
on the outer leg (acceptable or partly rightacceptable ou en partie juste)
tok (wrongfaux)
I’ll get bitten on (wrongfaux)
shabrak (acceptable or partly rightacceptable ou en partie juste)
ChatGPT
2023‑02
take her on (acceptable or partly rightacceptable ou en partie juste) a lunge line (correctcorrect)
ride light (wrongfaux)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
martingale (wrongfaux)
getting ready (wrongfaux)
saddle pad (correctcorrect)
2023‑03
lunge (correctcorrect)
ride with (wrongfaux)
the correct diagonal (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste)
helmet (correctcorrect)
leg wraps (correctcorrect)
saddle pad (correctcorrect)
2023‑03 (GPT-4)
lunge (correctcorrect)
post (correctcorrect)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
cup (wrongfaux)
gaiters (wrongfaux)
saddle pad (correctcorrect)
2024‑03
take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect)
post (correctcorrect)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
jockstrap (wrongfaux)
gaiters (wrongfaux)
saddle pad (correctcorrect)
2024‑05
lunge (correctcorrect)
post (correctcorrect)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
helmet (correctcorrect)
protective boots (correctcorrect)
saddle pad (correctcorrect)
2025‑09
lunge (correctcorrect)
post (correctcorrect)
on the outside diagonal (correctcorrect)
helmet (correctcorrect)
boots (correctcorrect)
saddle pad (correctcorrect)
2026‑01
lunge (correctcorrect)
rising trot (correctcorrect)
on the outside leg (acceptable or partly rightacceptable ou en partie juste)
riding helmet (correctcorrect)
my gaiters (wrongfaux)
saddle pad (correctcorrect)
2026‑01, deuxième essai
lunge (correctcorrect)
rise (correctcorrect)
on the outside foreleg (acceptable or partly rightacceptable ou en partie juste)
riding hat (correctcorrect)
my half chaps (wrongfaux)
saddle pad (correctcorrect)
2026‑10
lunge line (correctcorrect)
post (correctcorrect)
on the outside diagonal (correctcorrect)
riding helmet (correctcorrect)
brushing boots (correctcorrect)
saddle pad (correctcorrect)
Les termes du message néerlandais dans chaque résultat.
Les résultats complets
Système
Date
Résultat
Source
Ik zal haar eerst aan de longe nemen om te leren lichtrijden op het buitenbeen. Zorg dat ze een tok heeft en ik doe alvast getten om. Heb jij nog een sjabrak?
Référence
I will start by teaching her on the lunge how to post (the trot) on the correct diagonal. Make sure she has a riding hat, and I will already put the boots on. Do you have another saddle pad?
Google Traduction
2023
I will first take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) to learn how to ride light (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a tok (wrongfaux) and I’ll put on getten (wrongfaux). Do you still have a shabrack (acceptable or partly rightacceptable ou en partie juste)?
2025
I’ll start by lunging (correctcorrect) her to learn how to ride lightly (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a riding helmet (correctcorrect), and I’ll put on the saddle pads (wrongfaux). Do you still have a saddle pad (correctcorrect)?
2026‑10
I’ll put her on the lunge (correctcorrect) first so she can learn to rise (correctcorrect)to the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a helmet (correctcorrect), and I’ll put on her brushing boots (correctcorrect). Do you have a saddle pad (correctcorrect)?
DeepL
2023
I will take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) first to learn to ride lightly (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a tok (wrongfaux) and I’ll put on getten (wrongfaux) in advance. Do you still have a shawl (wrongfaux)?
2025
I will first take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) to teach her to ride lightly (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a bridle (wrongfaux) and I will put on the stirrups (wrongfaux). Do you have a saddlecloth (correctcorrect)?
2026‑10
I’ll start by lunging (correctcorrect) her to teach her to move lightly (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a halter (wrongfaux) on, and I’ll go ahead and put the girth (wrongfaux) on. Do you have a saddle pad (correctcorrect)?
eTranslation
2023
I’ll take her to (wrongfaux) the lung (wrongfaux) first to learn how to ride light (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she’s got a tok (wrongfaux), and I’m going to get it (wrongfaux). Do you have another shabrak (acceptable or partly rightacceptable ou en partie juste)?
2025
I’ll take her to (wrongfaux) the lungs (wrongfaux) first to learn how to ride lightly (wrongfaux)on the outer leg (acceptable or partly rightacceptable ou en partie juste). Make sure she’s got a tok (wrongfaux), and I’ll get the hell out of here (wrongfaux). Do you have another shabrak (acceptable or partly rightacceptable ou en partie juste)?
2026‑10
I’ll take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) first to learn light riding (wrongfaux)on the outer leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a tok (wrongfaux) and I’ll get bitten on (wrongfaux). Do you have another shabrak (acceptable or partly rightacceptable ou en partie juste)?
ChatGPT
2023‑02
I will first take her on (acceptable or partly rightacceptable ou en partie juste) a lunge line (correctcorrect) to teach her to ride light (wrongfaux)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a martingale (wrongfaux) and I’ll start getting ready (wrongfaux). Do you have a saddle pad (correctcorrect)?
2023‑03
I will first lunge (correctcorrect) her to teach her how to ride with (wrongfaux)the correct diagonal (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a helmet (correctcorrect) and I will put on leg wraps (correctcorrect). Do you have a saddle pad (correctcorrect)?
2023‑03 (GPT-4)
I will first lunge (correctcorrect) her to teach her to post (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a cup (wrongfaux), and I will put on the gaiters (wrongfaux) already. Do you have an extra saddle pad (correctcorrect)?
2024‑03
I will first take her on (acceptable or partly rightacceptable ou en partie juste) the lunge (correctcorrect) to learn to post (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a jockstrap (wrongfaux), and I will already put on gaiters (wrongfaux). Do you have another saddle pad (correctcorrect)?
2024‑05
I will lunge (correctcorrect) her first to teach her to post (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a helmet (correctcorrect), and I will put on the protective boots (correctcorrect). Do you still have a saddle pad (correctcorrect)?
2025‑09
I’ll lunge (correctcorrect) her first to teach her to post on the outside diagonal (correctcorrect). Make sure she’s got a helmet (correctcorrect), and I’ll go ahead and put on the boots (correctcorrect). Do you have a saddle pad (correctcorrect)?
2026‑01
I’ll put her on the lunge (correctcorrect) first so she can learn to ride rising trot (correctcorrect)on the outside leg (acceptable or partly rightacceptable ou en partie juste). Make sure she has a riding helmet (correctcorrect) on, and I’ll put my gaiters (wrongfaux) on already. Do you still have a saddle pad (correctcorrect)?
2026‑01, deuxième essai
I’ll lunge (correctcorrect) her first so she can learn to rise (correctcorrect)on the outside foreleg (acceptable or partly rightacceptable ou en partie juste). Make sure she’s wearing her riding hat (correctcorrect), and I’ll put my half chaps (wrongfaux) on. Do you have a saddle pad (correctcorrect) as well?
2026‑10
I’ll put her on the lunge line (correctcorrect) first so she can learn to post on the outside diagonal (correctcorrect). Make sure she has a riding helmet (correctcorrect), and I’ll put the brushing boots (correctcorrect) on in the meantime. Do you have another saddle pad (correctcorrect)?
Un message néerlandais traduit par trois services de traduction en ligne en 2023, en 2025 et en 2026-10, avec leurs versions gratuites, et par ChatGPT entre 2023 et 2026, chaque fois avec le modèle le plus récent qu'offrait l'abonnement payant de base à ce moment-là et la requête *translate into English:* suivie du message ; le résultat de 2026-10 avec le réglage d'effort moyen, dans une conversation temporaire.
Des mots d’équitation hors de propos. Plusieurs résultats ont remplacé
un terme par du vocabulaire d’équitation sans rapport avec le message, comme
si n’importe quel mot du domaine faisait l’affaire : une martingale
(ChatGPT, 2023), une bride et des étriers (DeepL, 2025), un licol et une
sangle (DeepL, 2026).
Mot à mot, ou pas du tout. En 2023, les trois services ont laissé tok
et getten non traduits ou en ont fait autre chose (le I’m going to get
it d’eTranslation). Tous les résultats des services, sauf celui de Google
Traduction de 2026, ont rendu lichtrijden par ride light, ride
lightly, move lightly ou light riding.
Les services se sont éloignés les uns des autres. En 2026-10, Google
Traduction avait presque tous les termes justes, le résultat de DeepL avait
changé sans s’améliorer, et eTranslation n’avait trouvé que la longe.
ChatGPT a progressé, mais pas de façon régulière. En 2023-02, il a
produit une martingale et getting ready ; un mois plus tard, il avait déjà le
casque, les bandes et le bon diagonal, tandis que GPT-4, sorti le même
mois, équipait la cavalière d’une coquille (cup). La plupart des termes
étaient justes en 2024-05 et tous en 2025-09. Aucun des deux résultats de
2026-01 n’avait le bon diagonal, et tous deux faisaient de getten quelque
chose que porte la personne qui parle ; en 2026-10, tous les termes
étaient de nouveau justes. Un système plus récent peut se tromper sur un
terme qu’un système plus ancien traduisait correctement.
De l’anglais vers le français
Le message anglais est I’ll start her on the lunge line to learn to post
the trot on the correct diagonal. When you take her to him, make sure to
explain his cribbing and to clean his feathers and treat his frogs to avoid
thrush. How are your lead changes going? Are you doing flying changes yet?
Chaque proposition contient un terme d’équitation.
Système
Date
lunge line
post the trot on the correct diagonal
cribbing
feathers
frogs
thrush
flying changes
Référence
à la longe
le trot enlevé sur le bon diagonal
fait un tic à l’appui
fanons
fourchettes
pourriture de la fourchette
changements de pied en l’air
Google Traduction
2025
à la longe (correctcorrect)
placer le trot sur la bonne diagonale (wrongfaux)
s’accroupit (wrongfaux)
plumes (wrongfaux)
fourchettes (correctcorrect)
grives (wrongfaux)
changements de pied en vol (wrongfaux)
2026‑10
à la longe (correctcorrect)
trotter enlevé (correctcorrect)sur la bonne diagonale (wrongfaux)
tic d’appui (acceptable or partly rightacceptable ou en partie juste)
fanons (correctcorrect)
fourchettes (correctcorrect)
pourrissement (acceptable or partly rightacceptable ou en partie juste)
au galop (acceptable or partly rightacceptable ou en partie juste)
DeepL
2025
à la longe (correctcorrect)
prendre le trot dans la bonne diagonale (wrongfaux)
fait des crèches (wrongfaux)
plumes (wrongfaux)
grenouilles (wrongfaux)
muguet (wrongfaux)
changements en vol (wrongfaux)
2026‑10
à la longe (correctcorrect)
se lever au trot (acceptable or partly rightacceptable ou en partie juste)sur la bonne diagonale (wrongfaux)
problème de mordillage (wrongfaux)
crins (acceptable or partly rightacceptable ou en partie juste)
sabots (acceptable or partly rightacceptable ou en partie juste)
pourriture de la fourchette (correctcorrect)
changements au galop (acceptable or partly rightacceptable ou en partie juste)
eTranslation
2026‑10
ligne de fente (wrongfaux)
poser le trot sur la bonne diagonale (wrongfaux)
cribbing (wrongfaux)
plumes (wrongfaux)
grenouilles (wrongfaux)
muguet (wrongfaux)
changements de vol (wrongfaux)
ChatGPT
2025‑01 (GPT-4o)
sur la longe (acceptable or partly rightacceptable ou en partie juste)
trotter en levée (acceptable or partly rightacceptable ou en partie juste)sur la bonne diagonale (wrongfaux)
tic à l’appui (cribbing) (correctcorrect)
fanons (correctcorrect)
fourchettes (correctcorrect)
pourriture (correctcorrect)
changements de pied au vol (wrongfaux)
2026‑02 (GPT-5.2)
à la longe (correctcorrect)
trotter enlevé sur le bon diagonal (correctcorrect)
tic à l’appui (correctcorrect)
fanons (correctcorrect)
fourchettes (correctcorrect)
pourriture de fourchette (correctcorrect)
changements de pied (correctcorrect)au temps (wrongfaux) (en l’air (correctcorrect))
2026‑10
à la longe (correctcorrect)
trotter enlevé sur le bon diagonal (correctcorrect)
tique à l’appui (correctcorrect)
fanons (correctcorrect)
fourchettes (correctcorrect)
pourriture de la fourchette (correctcorrect)
changements de pied en l’air (correctcorrect)
Les termes du message anglais dans chaque résultat. *Lead changes* n'y figure pas : tous les résultats ont *changements de pied*, sauf les *changements de leads* d'eTranslation.
Les résultats complets
Système
Date
Résultat
Source
I’ll start her on the lunge line to learn to post the trot on the correct diagonal. When you take her to him, make sure to explain his cribbing and to clean his feathers and treat his frogs to avoid thrush. How are your lead changes going? Are you doing flying changes yet?
Référence
Je vais commencer par la travailler à la longe pour qu’elle apprenne le trot enlevé sur le bon diagonal. Quand tu l’emmèneras vers lui, n’oublie pas de préciser qu’il fait un tic à l’appui et de bien nettoyer ses fanons, puis de traiter ses fourchettes afin d’éviter la pourriture de la fourchette. Comment avancent tes changements de pied ? Est-ce que tu fais déjà des changements de pied en l’air ?
Google Traduction
2025
Je vais la démarrer à la longe (correctcorrect) pour lui apprendre à placer le trot sur la bonne diagonale (wrongfaux). Lorsque vous l’amènerez chez lui, assurez-vous de lui expliquer comment il s’accroupit (wrongfaux), de nettoyer ses plumes (wrongfaux) et de traiter ses fourchettes (correctcorrect) pour éviter les grives (wrongfaux). Comment se passent vos changements de pied (correctcorrect) ? Faites-vous déjà des changements de pied en vol (wrongfaux) ?
2026‑10
Je vais commencer à la travailler à la longe (correctcorrect) pour qu’elle apprenne à trotter enlevé (correctcorrect)sur la bonne diagonale (wrongfaux). Lorsque tu l’emmèneras vers lui, n’oublie pas d’expliquer son tic d’appui (acceptable or partly rightacceptable ou en partie juste), de nettoyer ses fanons (correctcorrect) et de soigner ses fourchettes (correctcorrect) pour éviter le pourrissement (acceptable or partly rightacceptable ou en partie juste). Comment se passent les changements de pied (correctcorrect) ? En faites-vous déjà au galop (acceptable or partly rightacceptable ou en partie juste) ?
DeepL
2025
Je la mettrai à la longe (correctcorrect) pour qu’elle apprenne à prendre le trot dans la bonne diagonale (wrongfaux). Lorsque vous l’emmènerez chez lui, n’oubliez pas de lui expliquer qu’il fait des crèches (wrongfaux), de nettoyer ses plumes (wrongfaux) et de traiter ses grenouilles (wrongfaux) pour éviter le muguet (wrongfaux). Comment se passent les changements de pied (correctcorrect) ? Faites-vous déjà des changements en vol (wrongfaux) ?
2026‑10
Je vais commencer par la travailler à la longe (correctcorrect) pour qu’elle apprenne à se lever au trot (acceptable or partly rightacceptable ou en partie juste)sur la bonne diagonale (wrongfaux). Quand tu l’emmèneras chez lui, n’oublie pas de lui expliquer son problème de mordillage (wrongfaux), de nettoyer ses crins (acceptable or partly rightacceptable ou en partie juste) et de soigner ses sabots (acceptable or partly rightacceptable ou en partie juste) pour éviter la pourriture de la fourchette (correctcorrect). Comment se passent tes changements de pied (correctcorrect) ? Tu fais déjà des changements au galop (acceptable or partly rightacceptable ou en partie juste) ?
eTranslation
2026‑10
Je la mettrai sur la ligne de fente (wrongfaux) pour apprendre à poser le trot sur la bonne diagonale (wrongfaux). Lorsque vous l’emmenez chez lui, assurez-vous d’expliquer son cribbing (wrongfaux) et de nettoyer ses plumes (wrongfaux) et de traiter ses grenouilles (wrongfaux) pour éviter le muguet (wrongfaux). Comment vont vos changements de leads (wrongfaux) ? Êtes-vous en train de faire des changements de vol (wrongfaux) encore ?
ChatGPT
2025‑01 (GPT-4o)
Je vais commencer par la mettre sur la longe (acceptable or partly rightacceptable ou en partie juste) pour qu’elle apprenne à trotter en levée (acceptable or partly rightacceptable ou en partie juste)sur la bonne diagonale (wrongfaux). Quand tu l’emmènes chez lui, assure-toi d’expliquer son tic à l’appui (cribbing) (correctcorrect) et de nettoyer ses fanons (correctcorrect) ainsi que de traiter ses fourchettes (correctcorrect) pour éviter la pourriture (correctcorrect). Comment se passent tes changements de pied (correctcorrect) ? Fais-tu déjà des changements de pied au vol (wrongfaux) ?
2026‑02 (GPT-5.2)
Je vais d’abord la mettre à la longe (correctcorrect) pour qu’elle apprenne à trotter enlevé sur le bon diagonal (correctcorrect). Quand tu l’emmèneras chez lui, assure-toi de lui expliquer qu’il tic à l’appui (correctcorrect) et de nettoyer ses fanons (correctcorrect), puis de soigner ses fourchettes (correctcorrect) pour éviter la pourriture de fourchette (correctcorrect). Comment vont tes changements de pied (correctcorrect) ? Tu fais déjà des changements de pied (correctcorrect)au temps (wrongfaux) (en l’air (correctcorrect)) ?
2026‑10
Je vais commencer par la faire travailler à la longe (correctcorrect) pour qu’elle apprenne à trotter enlevé sur le bon diagonal (correctcorrect). Quand tu l’emmèneras chez lui, assure-toi de bien lui expliquer qu’il tique à l’appui (correctcorrect), de nettoyer ses fanons (correctcorrect) et de traiter ses fourchettes (correctcorrect) pour éviter la pourriture de la fourchette (correctcorrect). Comment ça se passe, tes changements de pied (correctcorrect) ? Tu fais déjà des changements de pied en l’air (correctcorrect) ?
Un message anglais traduit en français par trois services de traduction en ligne en 2025 et en 2026-10, avec leurs versions gratuites, et par ChatGPT en 2025 et en 2026, avec la requête *translate into French:* suivie du message ; le résultat de 2026-10 avec le réglage d'effort moyen, dans une conversation temporaire.
En 2025, les services ont traduit les mots. Tous deux ont rendu post
the trot mot à mot et flying changes par en vol. Google Traduction a
rendu feathers par plumes et thrush par grives, l’oiseau ; DeepL a
rendu frogs par grenouilles, l’animal, et thrush par muguet, la
candidose de la bouche que l’anglais appelle aussi thrush.
En 2026-10, les services s’étaient éloignés les uns des autres. Google
Traduction avait la plupart des termes d’équitation, sauf la bonne
diagonale, là où les cavaliers disent le bon diagonal, et deux formes
proches du terme sans être le terme, tic d’appui et pourrissement. DeepL
trouvait la longe et la pourriture de la fourchette, mais rendait cribbing
par mordillage, feathers par crins, les poils du cheval en général, et
frogs par sabots, le pied entier. eTranslation traduisait toujours les
mots : une ligne de fente pour la longe, des plumes, des grenouilles
et le muguet, et cribbing laissé tel quel.
ChatGPT avait la plupart des termes d’équitation sans qu’on lui indique
le domaine. En 2025-01, ChatGPT-4o avait déjà tic à l’appui, fanons et
fourchettes, mais ni le trot ni les changements de pied en l’air. En
2026-02, ChatGPT-5.2 avait tous les termes justes sauf au temps, qui
désigne un autre changement de pied, et en 2026-10, tous les termes
étaient justes (see also the Prompting an LLM for translation page, in the Machine translation module) (voir aussi la page Rédiger une requête de traduction pour un GML, dans le module Traduction automatique).
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Prompting an LLM for translationRédiger une requête de traduction pour un GML
a user manual for the technicians who install industrial pumps
for the 2023 models tested, stating the task and the domain improved the translations, most on specialized and less-resourced pairs (Peng et al., 2023); with GPT-5.2, on four newspaper editorials, human evaluators preferred the translations from a prompt giving a translation brief (audience, publication context, register) to those from a bare request (Lai & Li, 2026)
earlier translations of similar sentences, from a translation memory
steered the output of the 2023 models tested toward the required terminology and style, without any change to the model (Moslem et al., 2023); for Gemini 1.5 Pro, retrieved example translations of similar sentences improved domain translation (Li et al., 2025c)
Terms
the client’s term list
for Gemini 1.5 Pro, a term list barely improved domain translation, where example translations did (Li et al., 2025c). With a glossary in the prompt, the four open models tested by Dahan et al. (2026) used the glossary’s terms much more often, but also varied their terms less than human translators do, for instance alternating a term with a shorter form or a synonym, as French scientific writing tends to
What a translation prompt has to state.
The tool you translate in decides who writes the prompt. In a chat
app, you write it, so this context is yours to give. Some CAT tools now offer
translation with a large language model, and there the tool writes the
prompt: depending on the tool and its settings, it may add matches from the
translation memory and entries from the termbase, but the audience and the
purpose reach the model only if the tool lets you add them, and tools differ
in what they send.memoQ’s documentation for version 12.5 says its AGT feature sends translation memory matches above a match rate the user sets, and that “Term base matches are always sent” (Translate with AGT, read 13 October 2026). Trados describes its AI Assistant as putting “an LLM to work alongside your terminology and translation memories” (What is AI Assistant in Trados Studio?, read 13 October 2026).
Beyond that context, research on how to write a translation prompt has
produced few findings that apply from one model to the next. Each study tests
one or a few models, and several results have changed with newer ones:
Stating the domain improved the translations of ChatGPT in 2023 (Peng
et al., 2023). For a reasoning model of 2025, DeepSeek-R1, one study found
that it changed the scores very little, in either direction; that study
has remained a preprint (Ye et al., 2025).
The wording and the format of the prompt made a large difference for
older and smaller models: GPT-3.5’s results varied widely with the format,
GPT-4’s much less, and larger models are generally less sensitive to how a
prompt is worded (He et al., 2024; Zhuo et al.,
2024) (see also the Structure the prompt page, in the Using LLMs module) (voir aussi la page Structurer la requête, dans le module Utiliser les GML). For
translation, imperfect English in the prompt mostly lowered how well the
instructions were followed, but the translation quality itself was barely
affected (Schmidtová et al., 2026).
The language of the prompt made a difference in one study and not in
another. With GPT-5.1 translating between Spanish
and Italian, experts preferred the translations from prompts written in the
target language to those from English prompts (Bove et al., 2026); with
GPT-5.2 translating Spanish newspaper editorials into Chinese, the prompt’s
language made no difference (Lai & Li, 2026). Both studies are small, with
one language pair each (see also the language of the prompt page, in the Using LLMs module) (voir aussi la page La langue de la requête, dans le module Utiliser les GML).
Working through a translator’s steps (research, draft, revision) did
not improve the translation of sentences: asking a model simply to
translate again and refine its own draft worked as well or better (Wu et
al., 2025b). For long texts, a four-step workflow did beat a single prompt
with Gemini 1.5 Pro (Briakou et al., 2024) (see also the Split the task page, in the Using LLMs module) (voir aussi la page Découper la tâche, dans le module Utiliser les GML).
Reasoning before translating gained little. When a model’s reasoning
was switched on or given more time, its translations of sentences changed
little, levelled off quickly or got slightly worse (Zebaze et al., 2025; Li
et al., 2026; Rajaee et al., 2026). Reasoning models still translate very
well: the best system at WMT 2025, Gemini 2.5 Pro, ran with its reasoning
on (Kocmi et al., 2025). Extra reasoning helped more when the model reviewed
and corrected a translation than when it produced one (Li et al.,
2026) (see also the Reasoning step by step page, in the LLM lifecycle module) (voir aussi la page Raisonner étape par étape, dans le module Cycle de vie des GML).
Bove, A., Di Cataldo, P., & Maestroni, D. (2026). Evaluating the Effect of Prompt Language on LLM-based Translation: Evidence from Spanish<>Italian Translation. Proceedings of the 26th Annual Conference of the European Association for Machine Translation (Volume 1), 800–812. https://aclanthology.org/2026.eamt-1.51/
Briakou, E., Luo, J., Cherry, C., & Freitag, M. (2024). Translating Step-by-Step: Decomposing the Translation Process for Improved Translation Quality of Long-Form Texts. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1301–1317. https://doi.org/10.18653/v1/2024.wmt-1.123
Dahan, N., Peng, Z., Yvon, F., & Bawden, R. (2026). Improving Term Evaluation in Machine Translation: Variation Matters. Proceedings of the 17th Conference of the Association for Machine Translation in the Americas (Research Track). https://aclanthology.org/2026.amta-research.7/
He, J., Rungta, M., Koleczek, D., Sekhon, A., Wang, F. X., & Hasan, S. (2024). Does Prompt Formatting Have Any Impact on LLM Performance?. Preprint, arXiv:2411.10541. https://arxiv.org/abs/2411.10541
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Lai, H., & Li, W. (2026). The Role of Prompt Language and Translation-Theory-Driven Prompts in Large Language Models: A Case Study on Spanish–Chinese Journalistic Translation. Proceedings of the 26th Annual Conference of the European Association for Machine Translation (Volume 1), 883–901. https://aclanthology.org/2026.eamt-1.57/
Li, B., Luo, J., Briakou, E., & Cherry, C. (2025c). Leveraging Domain Knowledge at Inference Time for LLM Translation: Retrieval versus Generation. Proceedings of the 4th International Workshop on Knowledge-Augmented Methods for Natural Language Processing (KnowledgeNLP 2025), 91–106. https://doi.org/10.18653/v1/2025.knowledgenlp-1.7
Li, Z., Ji, S., & Tiedemann, J. (2026). Test-Time Scaling of Reasoning Models for Machine Translation. Proceedings of the 19th Conference of the European Chapter of the Association for Computational Linguistics (Volume 1: Long Papers), 2902–2917. https://doi.org/10.18653/v1/2026.eacl-long.133
Moslem, Y., Haque, R., Kelleher, J. D., & Way, A. (2023). Adaptive Machine Translation with Large Language Models. Proceedings of the 24th Annual Conference of the European Association for Machine Translation (EAMT 2023), 227–237. https://aclanthology.org/2023.eamt-1.22/
Peng, K., Ding, L., Zhong, Q., Shen, L., Liu, X., Zhang, M., et al. (2023). Towards Making the Most of ChatGPT for Machine Translation. Findings of the Association for Computational Linguistics: EMNLP 2023, 5622–5633. https://doi.org/10.18653/v1/2023.findings-emnlp.373
Rajaee, S., Vincent, S., Berard, A., Fadaee, M., Marchisio, K., & Kocmi, T. (2026). Unlocking Reasoning Capability on Machine Translation in Large Language Models. Preprint, arXiv:2602.14763. https://arxiv.org/abs/2602.14763
Schmidtová, P., Bafna, N., Aycock, S., Vico, G., Kamzela, W., Hämmerl, K., & Zouhar, V. (2026). How Important is 'Perfect' English for Machine Translation Prompts?. Findings of the Association for Computational Linguistics: EACL 2026, 760–777. https://doi.org/10.18653/v1/2026.findings-eacl.38
Wu, D., Aycock, S., & Monz, C. (2025b). Please Translate Again: Two Simple Experiments on Whether Human-Like Reasoning Helps Translation. Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing (EMNLP 2025), 20424–20440. https://doi.org/10.18653/v1/2025.emnlp-main.1031
Ye, Y., Fu, B., Huang, C., Chen, Y., & Shi, X. (2025). How Well Do Large Reasoning Models Translate? A Comprehensive Evaluation for Multi-Domain Machine Translation. Preprint, arXiv:2505.19987. https://arxiv.org/abs/2505.19987
Zebaze, A., Bawden, R., & Sagot, B. (2025). LLM Reasoning for Machine Translation: Synthetic Data Generation over Thinking Tokens. Preprint, arXiv:2510.11919. https://arxiv.org/abs/2510.11919
Zhuo, J., Zhang, S., Fang, X., Duan, H., Lin, D., & Chen, K. (2024). ProSA: Assessing and Understanding the Prompt Sensitivity of LLMs. Findings of the Association for Computational Linguistics: EMNLP 2024, 1950–1976. https://doi.org/10.18653/v1/2024.findings-emnlp.108
un manuel d’utilisation destiné aux techniciens qui installent des pompes industrielles
pour les modèles de 2023 testés, préciser la tâche et le domaine a amélioré les traductions, surtout pour les paires spécialisées et moins dotées (Peng et al., 2023) ; avec GPT-5.2, sur quatre éditoriaux de presse, des évaluateurs humains ont préféré les traductions obtenues avec une requête donnant un cahier des charges de traduction (public, contexte de publication, registre) à celles obtenues avec une simple demande (Lai & Li, 2026)
des traductions antérieures de phrases semblables, tirées d’une mémoire de traduction
a orienté le résultat des modèles de 2023 testés vers la terminologie et le style voulus, sans aucune modification du modèle (Moslem et al., 2023) ; pour Gemini 1.5 Pro, des traductions de phrases semblables retrouvées et données en exemple ont amélioré la traduction spécialisée (Li et al., 2025c)
Des termes
la liste de termes du client
pour Gemini 1.5 Pro, une liste de termes n’a presque rien changé à la traduction spécialisée, là où des traductions données en exemple l’ont améliorée (Li et al., 2025c). Avec un glossaire dans la requête, les quatre modèles ouverts testés par Dahan et al. (2026) employaient bien plus souvent les termes du glossaire, mais variaient aussi moins leurs termes que les traducteurs humains, qui alternent par exemple un terme avec une forme abrégée ou un synonyme, comme le fait volontiers l’écriture scientifique en français
Ce qu'une requête de traduction doit préciser.
L’outil dans lequel on traduit détermine qui rédige la requête.
Dans une application conversationnelle, c’est vous, si bien que ce contexte
est à vous de le donner. Certains outils de TAO proposent désormais la
traduction par un grand modèle de langue, et c’est alors l’outil qui rédige la
requête : selon l’outil et ses réglages, il peut y ajouter des
correspondances de la mémoire de traduction et des entrées de la base
terminologique, mais le public et le but ne parviennent au modèle que si
l’outil permet de les ajouter, et les outils diffèrent dans ce qu’ils
envoient.La documentation de memoQ pour la version 12.5 indique que sa fonction AGT envoie les correspondances de la mémoire de traduction au-delà d’un taux de correspondance fixé par l’utilisateur, et que « Term base matches are always sent » [ma traduction : « les correspondances de la base terminologique sont toujours envoyées »] (Translate with AGT, consulté le 13 octobre 2026). Trados décrit son AI Assistant comme un outil qui « puts an LLM to work alongside your terminology and translation memories » [ma traduction : « fait travailler un grand modèle de langue avec votre terminologie et vos mémoires de traduction »] (What is AI Assistant in Trados Studio?, consulté le 13 octobre 2026).
Traduire un fichier entier est une autre question : beaucoup d’applications
conversationnelles peuvent désormais rendre un fichier traduit, mais il faut
vérifier si sa mise en forme et ses balises ont été
conservées (see also the Working with long documents page, in the Using LLMs module) (voir aussi la page Travailler avec de longs documents, dans le module Utiliser les GML).
Ce qui n’est pas établi
Au-delà de ce contexte, la recherche sur la rédaction des requêtes de
traduction a produit peu de résultats qui valent d’un modèle à l’autre.
Chaque étude teste un modèle ou quelques-uns, et plusieurs résultats ont changé
avec les modèles plus récents :
Préciser le domaine a amélioré les traductions de ChatGPT en 2023 (Peng
et al., 2023). Pour un modèle de raisonnement de 2025, DeepSeek-R1, une
étude a constaté que cela changeait très peu les scores, dans un sens comme
dans l’autre ; cette étude est restée une prépublication (Ye et al., 2025).
La formulation et le format de la requête comptaient beaucoup pour les
modèles plus anciens et plus petits : les résultats de GPT-3.5 variaient
fortement selon le format, ceux de GPT-4 beaucoup moins, et les modèles plus
grands sont en général moins sensibles à la formulation d’une requête (He et
al., 2024 ; Zhuo et al., 2024) (see also the Structure the prompt page, in the Using LLMs module) (voir aussi la page Structurer la requête, dans le module Utiliser les GML).
Pour la traduction, un anglais imparfait dans la requête a surtout diminué
la façon dont le modèle suivait les consignes, mais la qualité de la
traduction elle-même n’en a presque pas souffert (Schmidtová et al., 2026).
La langue de la requête a compté dans une étude et pas dans
l’autre. Avec GPT-5.1 traduisant entre l’espagnol et
l’italien, des experts ont préféré les traductions obtenues avec des
requêtes rédigées dans la langue cible à celles obtenues avec des requêtes
en anglais (Bove et al., 2026) ; avec GPT-5.2 traduisant des éditoriaux de
presse espagnols en chinois, la langue de la requête n’a rien changé (Lai &
Li, 2026). Les deux études sont petites et ne portent chacune que sur une
paire de langues (see also the language of the prompt page, in the Using LLMs module) (voir aussi la page La langue de la requête, dans le module Utiliser les GML).
Faire passer le modèle par les étapes d’un traducteur (recherche,
ébauche, révision) n’a pas amélioré la traduction de phrases : demander
simplement au modèle de traduire à nouveau et d’affiner sa propre ébauche a
donné d’aussi bons résultats, voire meilleurs (Wu et al., 2025b). Pour des
textes longs, un flux de travail en quatre étapes a battu une requête unique
avec Gemini 1.5 Pro (Briakou et al., 2024) (see also the Split the task page, in the Using LLMs module) (voir aussi la page Découper la tâche, dans le module Utiliser les GML).
Raisonner avant de traduire a peu apporté. Quand le raisonnement d’un
modèle était activé ou disposait de plus de temps, ses traductions de
phrases changeaient peu, plafonnaient vite ou se dégradaient légèrement
(Zebaze et al., 2025 ; Li et al., 2026 ; Rajaee et al., 2026). Les modèles
de raisonnement traduisent pourtant très bien : le meilleur système de
WMT 2025, Gemini 2.5 Pro, fonctionnait avec son raisonnement activé (Kocmi
et al., 2025). Un raisonnement plus long a davantage aidé quand le modèle
révisait et corrigeait une traduction que quand il la produisait (Li et
al., 2026) (see also the Reasoning step by step page, in the LLM lifecycle module) (voir aussi la page Raisonner étape par étape, dans le module Cycle de vie des GML).
Bove, A., Di Cataldo, P., & Maestroni, D. (2026). Evaluating the Effect of Prompt Language on LLM-based Translation: Evidence from Spanish<>Italian Translation. Proceedings of the 26th Annual Conference of the European Association for Machine Translation (Volume 1), 800–812. https://aclanthology.org/2026.eamt-1.51/
Briakou, E., Luo, J., Cherry, C., & Freitag, M. (2024). Translating Step-by-Step: Decomposing the Translation Process for Improved Translation Quality of Long-Form Texts. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1301–1317. https://doi.org/10.18653/v1/2024.wmt-1.123
Dahan, N., Peng, Z., Yvon, F., & Bawden, R. (2026). Improving Term Evaluation in Machine Translation: Variation Matters. Proceedings of the 17th Conference of the Association for Machine Translation in the Americas (Research Track). https://aclanthology.org/2026.amta-research.7/
He, J., Rungta, M., Koleczek, D., Sekhon, A., Wang, F. X., & Hasan, S. (2024). Does Prompt Formatting Have Any Impact on LLM Performance?. Preprint, arXiv:2411.10541. https://arxiv.org/abs/2411.10541
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Lai, H., & Li, W. (2026). The Role of Prompt Language and Translation-Theory-Driven Prompts in Large Language Models: A Case Study on Spanish–Chinese Journalistic Translation. Proceedings of the 26th Annual Conference of the European Association for Machine Translation (Volume 1), 883–901. https://aclanthology.org/2026.eamt-1.57/
Li, B., Luo, J., Briakou, E., & Cherry, C. (2025c). Leveraging Domain Knowledge at Inference Time for LLM Translation: Retrieval versus Generation. Proceedings of the 4th International Workshop on Knowledge-Augmented Methods for Natural Language Processing (KnowledgeNLP 2025), 91–106. https://doi.org/10.18653/v1/2025.knowledgenlp-1.7
Li, Z., Ji, S., & Tiedemann, J. (2026). Test-Time Scaling of Reasoning Models for Machine Translation. Proceedings of the 19th Conference of the European Chapter of the Association for Computational Linguistics (Volume 1: Long Papers), 2902–2917. https://doi.org/10.18653/v1/2026.eacl-long.133
Moslem, Y., Haque, R., Kelleher, J. D., & Way, A. (2023). Adaptive Machine Translation with Large Language Models. Proceedings of the 24th Annual Conference of the European Association for Machine Translation (EAMT 2023), 227–237. https://aclanthology.org/2023.eamt-1.22/
Peng, K., Ding, L., Zhong, Q., Shen, L., Liu, X., Zhang, M., et al. (2023). Towards Making the Most of ChatGPT for Machine Translation. Findings of the Association for Computational Linguistics: EMNLP 2023, 5622–5633. https://doi.org/10.18653/v1/2023.findings-emnlp.373
Rajaee, S., Vincent, S., Berard, A., Fadaee, M., Marchisio, K., & Kocmi, T. (2026). Unlocking Reasoning Capability on Machine Translation in Large Language Models. Preprint, arXiv:2602.14763. https://arxiv.org/abs/2602.14763
Schmidtová, P., Bafna, N., Aycock, S., Vico, G., Kamzela, W., Hämmerl, K., & Zouhar, V. (2026). How Important is 'Perfect' English for Machine Translation Prompts?. Findings of the Association for Computational Linguistics: EACL 2026, 760–777. https://doi.org/10.18653/v1/2026.findings-eacl.38
Wu, D., Aycock, S., & Monz, C. (2025b). Please Translate Again: Two Simple Experiments on Whether Human-Like Reasoning Helps Translation. Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing (EMNLP 2025), 20424–20440. https://doi.org/10.18653/v1/2025.emnlp-main.1031
Ye, Y., Fu, B., Huang, C., Chen, Y., & Shi, X. (2025). How Well Do Large Reasoning Models Translate? A Comprehensive Evaluation for Multi-Domain Machine Translation. Preprint, arXiv:2505.19987. https://arxiv.org/abs/2505.19987
Zebaze, A., Bawden, R., & Sagot, B. (2025). LLM Reasoning for Machine Translation: Synthetic Data Generation over Thinking Tokens. Preprint, arXiv:2510.11919. https://arxiv.org/abs/2510.11919
Zhuo, J., Zhang, S., Fang, X., Duan, H., Lin, D., & Chen, K. (2024). ProSA: Assessing and Understanding the Prompt Sensitivity of LLMs. Findings of the Association for Computational Linguistics: EMNLP 2024, 1950–1976. https://doi.org/10.18653/v1/2024.findings-emnlp.108
Figure 7. One example of the Last Translation Benchmark: three leading systems fail the verification rule on an easy-looking sentence (Zouhar et al., 2026, example 1).
The contributors. 260 contributors from 177 institutions, each submitting
sentences, images, audio or video that they knew to be hard, with a correct
translation of their own; every submission is reviewed by another
contributor. The first version, LTBv1, contains 3 456 examples in 109
languages (Zouhar et al., 2026).
The admission test. An example is accepted only if most of
the systems shown to the contributor fail it and the human translation
passes: the benchmark contains hard cases by construction, and says nothing
about the quality of a typical translation.
The scoring. Each example comes with one or more verification
rules describing the failure to look for (“the word for nurse must not be
feminine”). A model checks each translation against each rule, and a
translation passes only if it satisfies them all. The score of a system is
the share of examples it passes.
System
Examples passed
Human translations (the contributors’)
99.8 %
Gemini 3.1 Pro
41.9 %
GPT-5.6 Sol
31.8 %
GPT-5.6 Luna
19.3 %
Claude Sonnet 4.5
6.0 %
NLLB 3.3B, an encoder-decoder system
2.0 %
Google Translate
1.6 %
Share of examples passed on the Last Translation Benchmark, LTBv1-eval, with Gemma 4 as the verifier (Zouhar et al., 2026, main table 2, selected rows).
Ordinary metrics did not flag the failures. On the same translations,
ordinary metrics and a large language model used as judge gave scores in
the range the authors label “good”, while the share of examples passed
stayed low. A judge given the rule detected the error; a judge asked only to
rate the translation usually did not (Zouhar et al., 2026) (see also the A large language model as judge page, in the Evaluating language technology module) (voir aussi la page Un grand modèle de langue comme juge, dans le module L'évaluation des technologies langagières).
Figure 8. Sources of translation difficulty, from the examples of the Last Translation Benchmark (Zouhar et al., 2026, table 6). Counts are examples; one example may have several labels.
Difficulty
Example
Result
Polysemy in a domain
English paper, meaning an article, into German
most models wrote Papier, the material, where Artikel or the loanword Paper was needed
Internet culture and slang
French mon pain for my crush, with a borrowed whippin
several models kept bread
A false friend
Hausa marka, heavy rain, which looks like English mark
one service wrote this monsoon is marked
Meta-reasoning
Italian Come si dice formaggio in inglese?
most models translated formaggio too, producing a question that answers itself
Four of the benchmark's examples, as the authors describe them (Zouhar et al., 2026).
Remedies. Two remedies are backtranslation, where a system trained for
the opposite direction turns monolingual target text into synthetic
parallel data, and multilingual models, which draw on a related language
that has more data (Jurafsky & Martin, 2026).
Data quality. In a manual audit of large parallel corpora, many
had fewer than half of their sentences of acceptable quality, for instance
repeated web text or wrong translations. This suggests that speakers of the
languages concerned were not involved enough in building them (Jurafsky &
Martin, 2026).
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Zouhar, V., Bafna, N., Choudhary, M., Züfle, M., Rajaee, S., Chen, P., et al. (2026). Last Translation Benchmark. Preprint, arXiv:2609.04173. http://arxiv.org/abs/2609.04173
Les faiblesses relevées à WMT
WMT, la comparaison annuelle des systèmes de traduction automatique tenue
lors de la conférence sur la traduction automatique (Conference on Machine
Translation), relève des faiblesses précises même chez les meilleurs systèmes
(Kocmi et al., 2024b, 2025) (see also the trend across editions page, in the Machine translation module) (voir aussi la page La tendance d'une édition à l'autre, dans le module Traduction automatique) :
l’entrée orale, le domaine le plus difficile deux années de suite, très
probablement parce que les systèmes traduisent une transcription
automatique et en héritent les erreurs ;
les langues peu dotées, où l’évaluation humaine de 2025 a montré des
faiblesses dans tous les modèles testés, en arabe égyptien et en maasaï ;
des phénomènes précis examinés par des séries de tests ciblées : les
entrées non standard, la syntaxe complexe, la terminologie d’un domaine, le
choix et l’accord du genre.
Par contraste, dans les domaines testés en 2024, les traductions de l’anglais
vers l’espagnol des meilleurs systèmes étaient proches des références
humaines.
Figure 7. Un exemple du Last Translation Benchmark : trois systèmes de pointe échouent à la règle de vérification sur une phrase d'apparence facile (Zouhar et al., 2026, exemple 1).
Les contributeurs. 260 contributeurs de 177 établissements ont chacun
soumis des phrases, des images, des fichiers audio ou des vidéos qu’ils
savaient difficiles, avec leur propre traduction correcte ; chaque
soumission est révisée par un autre contributeur. La première version,
LTBv1, contient 3 456 exemples dans 109 langues (Zouhar et al., 2026).
Le critère d’admission. Un exemple n’est accepté que si la plupart des
systèmes montrés au contributeur échouent et que la traduction humaine
réussit : le test ne contient que des cas difficiles par construction, et ne
dit rien de la qualité d’une traduction ordinaire.
La notation. Chaque exemple est accompagné d’une ou de plusieurs règles
de vérification qui décrivent l’échec à rechercher (« le mot pour nurse ne
doit pas être au féminin »). Un modèle vérifie chaque traduction au regard
de chaque règle, et une traduction ne réussit que si elle les respecte
toutes. Le score d’un système est la proportion d’exemples qu’il réussit.
Système
Exemples réussis
Traductions humaines (celles des contributeurs)
99,8 %
Gemini 3.1 Pro
41,9 %
GPT-5.6 Sol
31,8 %
GPT-5.6 Luna
19,3 %
Claude Sonnet 4.5
6,0 %
NLLB 3.3B, un système encodeur-décodeur
2,0 %
Google Traduction
1,6 %
Proportion d'exemples réussis au Last Translation Benchmark, LTBv1-eval, avec Gemma 4 comme vérificateur (Zouhar et al., 2026, tableau principal 2, lignes choisies).
Les mesures habituelles n’ont pas signalé les échecs. Sur les mêmes
traductions, les mesures habituelles et un grand modèle de langue employé
comme juge ont donné des scores dans la plage que les auteurs qualifient de
« bonne », alors que la proportion d’exemples réussis restait faible. Un
juge à qui l’on donnait la règle détectait l’erreur ; un juge à qui l’on
demandait seulement d’évaluer la traduction ne la détectait généralement
pas (Zouhar et al., 2026) (see also the A large language model as judge page, in the Evaluating language technology module) (voir aussi la page Un grand modèle de langue comme juge, dans le module L'évaluation des technologies langagières).
Figure 8. Les sources de difficulté de la traduction, d'après les exemples du Last Translation Benchmark (Zouhar et al., 2026, tableau 6). Les nombres comptent des exemples ; un exemple peut avoir plusieurs étiquettes.
Difficulté
Exemple
Résultat
Polysémie dans un domaine
l’anglais paper, au sens d’article, vers l’allemand
la plupart des modèles ont écrit Papier, la matière, là où il fallait Artikel ou l’emprunt Paper
Culture Internet et argot
le français mon pain au sens de my crush, avec l’emprunt whippin
plusieurs modèles ont gardé bread
Un faux ami
le haoussa marka, forte pluie, qui ressemble à l’anglais mark
un service a écrit this monsoon is marked
Métaraisonnement
l’italien Come si dice formaggio in inglese?
la plupart des modèles ont aussi traduit formaggio, ce qui donne une question qui contient sa réponse
Quatre exemples du test de performances, tels que les auteurs les décrivent (Zouhar et al., 2026).
Les solutions. Deux solutions sont la rétrotraduction, où un système
entraîné pour la direction inverse transforme des textes monolingues de la
langue cible en données parallèles synthétiques, et les modèles
multilingues, qui s’appuient sur une langue apparentée disposant de plus de
données (Jurafsky & Martin, 2026).
La qualité des données. Dans un audit manuel de grands corpus
parallèles, beaucoup comptaient moins de la moitié de phrases de qualité
acceptable, par exemple du texte Web répété ou des traductions erronées. Cela
laisse penser que les locuteurs des langues concernées n’ont pas été assez
associés à leur constitution (Jurafsky & Martin, 2026).
Les tests de performances. Les tests de performances eux-mêmes penchent
vers les langues bien dotées : 73 % des exemples du Last Translation
Benchmark se traduisent vers l’anglais (Zouhar et
al., 2026) (see also the Linguistic hegemony page, in the Critical issues with LLMs module) (voir aussi la page L'hégémonie linguistique, dans le module Enjeux critiques des GML).
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Zouhar, V., Bafna, N., Choudhary, M., Züfle, M., Rajaee, S., Chen, P., et al. (2026). Last Translation Benchmark. Preprint, arXiv:2609.04173. http://arxiv.org/abs/2609.04173
Evaluating machine translationÉvaluation de la traduction automatique
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
Many correct translationsDe nombreuses traductions correctes
Translation shares this difficulty in a more complex form, and adds a second
one, because translation means generating new text rather than selecting
text or labels from a limited set:
The correct answers cannot be listed. The terms of a text are
sequences of words in that text, so a gold standard can list
them (see also the Matching rules page, in the Evaluating language technology module) (voir aussi la page Les règles de correspondance, dans le module L'évaluation des technologies langagières). A
sentence has too many correct translations to list, and a correct output
rarely matches a translation made by a person word for word.
An answer can be partly right. Even a borderline term is either on a
list or not. A translated sentence contains many decisions and can be
wrong in one part, slightly or seriously: awkward phrasing is not as
serious as reversing the meaning.
Figure 1figure 1 shows both on one French idiom: four English translations are correct and
differ from each other in wording, two are partly wrong because they lose
part of the meaning or are awkwardly phrased, and two are wrong.
Figure 1. One sentence to translate, four correct translations, two partly wrong ones and two wrong ones. The first correct translation serves as the reference.
Adequacy and fluency
Two dimensions are standard in judging a translation (Jurafsky & Martin, 2026):
adequacy, also called fidelity: how well the translation conveys the
meaning of the source;
fluency: whether the translation is grammatical, clear and natural in
the target language.
The two come apart, as Figure 2figure 2 shows on four translations of one sentence.
Figure 2. Four translations of one sentence, placed by adequacy and by fluency.
In machine translation, the gold standard is a reference translation: a
translation of the test sentence by a professional translator, taken as one
correct answer among many.
A metric that compares an output with a reference therefore measures
resemblance to one translation, and a perfect match is rare, even for a
very good translation. Some evaluations give each sentence several
references to soften that (Papineni et al., 2002).
A reference-based evaluation can penalize a correct translation, and a
system that is better than the reference, for differing from it (Freitag
et al., 2021).
Sources
Basile, V., Fell, M., Fornaciari, T., Hovy, D., Paun, S., Plank, B., et al. (2021). We Need to Consider Disagreement in Evaluation. Proceedings of the 1st Workshop on Benchmarking: Past, Present and Future. https://doi.org/10.18653/v1/2021.bppf-1.3
Freitag, M., Foster, G., Grangier, D., Ratnakar, V., Tan, Q., & Macherey, W. (2021). Experts, Errors, and Context: A Large-Scale Study of Human Evaluation for Machine Translation. Transactions of the Association for Computational Linguistics, 9, 1460–1474. https://doi.org/10.1162/tacl_a_00437
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
La traduction partage cette difficulté sous une forme plus complexe, et en
ajoute une seconde, parce que traduire consiste à produire un texte nouveau
plutôt qu’à choisir des passages ou des étiquettes dans un ensemble
limité :
Les bonnes réponses ne peuvent pas être énumérées. Les termes d’un
texte sont des suites de mots de ce texte, si bien qu’un étalon de
référence peut en dresser la
liste (see also the Matching rules page, in the Evaluating language technology module) (voir aussi la page Les règles de correspondance, dans le module L'évaluation des technologies langagières). Une
phrase a trop de traductions correctes pour qu’on les énumère, et une
sortie correcte correspond rarement mot pour mot à une traduction faite
par une personne.
Une réponse peut être en partie juste. Même un terme limite figure sur
une liste ou n’y figure pas. Une phrase traduite contient de nombreuses
décisions et peut être fausse sur un point, légèrement ou gravement : une
tournure maladroite est moins grave qu’un sens inversé.
La Figure 1figure 1 montre les deux sur une expression figée française : quatre traductions
anglaises sont correctes et diffèrent entre elles par leur formulation, deux
sont en partie fausses parce qu’elles perdent une partie du sens ou sont
maladroites, et deux sont fausses.
Figure 1. Une phrase à traduire, quatre traductions correctes, deux en partie fausses et deux fausses. La première traduction correcte sert de référence.
L’adéquation et la fluidité
Deux dimensions servent habituellement à juger une traduction (Jurafsky &
Martin, 2026) :
l’adéquation, aussi appelée fidélité : la mesure dans laquelle la
traduction rend le sens de la source ;
la fluidité : la traduction est-elle grammaticale, claire et naturelle
dans la langue cible ?
Les deux peuvent diverger, comme le montre la Figure 2figure 2 sur quatre traductions d’une même phrase.
Figure 2. Quatre traductions d'une même phrase, placées selon leur adéquation et leur fluidité.
Dans le travail professionnel, le style et la terminologie sont aussi
jugés ; MQM en fait des catégories d’erreurs distinctes (Freitag et al.,
2021) (see also the Human evaluation: DA, MQM and ESA page, in the Evaluating language technology module) (voir aussi la page L'évaluation humaine : DA, MQM et ESA, dans le module L'évaluation des technologies langagières). Les évaluateurs
sans formation en traduction ont du mal à séparer
l’adéquation de la fluidité, si bien que les évaluations humaines forment
leurs évaluateurs à l’aide d’exemples (Jurafsky & Martin, 2026).
La traduction de référence
En traduction automatique, l’étalon de référence est une traduction de
référence : une traduction de la phrase de test faite par une traductrice ou
un traducteur professionnel, retenue comme une bonne réponse parmi
d’autres.
Une métrique qui compare une sortie avec une référence mesure donc la
ressemblance avec une seule traduction, et une correspondance parfaite est
rare, même pour une très bonne traduction. Certaines évaluations donnent
plusieurs références à chaque phrase pour atténuer ce problème (Papineni et
al., 2002).
Une évaluation fondée sur une référence peut pénaliser une traduction
correcte, et un système meilleur que la référence, parce qu’ils s’en
écartent (Freitag et al., 2021).
Sources
Basile, V., Fell, M., Fornaciari, T., Hovy, D., Paun, S., Plank, B., et al. (2021). We Need to Consider Disagreement in Evaluation. Proceedings of the 1st Workshop on Benchmarking: Past, Present and Future. https://doi.org/10.18653/v1/2021.bppf-1.3
Freitag, M., Foster, G., Grangier, D., Ratnakar, V., Tan, Q., & Macherey, W. (2021). Experts, Errors, and Context: A Large-Scale Study of Human Evaluation for Machine Translation. Transactions of the Association for Computational Linguistics, 9, 1460–1474. https://doi.org/10.1162/tacl_a_00437
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Ways of evaluating a translationLes façons d'évaluer une traduction
Figure 3. The ways of evaluating machine translation, by who or what judges, coloured by the use of a reference translation. The named metrics and protocols are examples, not complete lists. The dashed combinations exist but are less common in current machine translation evaluation, where people annotate errors and automatic methods give scores (Kocmi et al., 2025); this chapter does not cover them.
The rows of the figure are the three families of methods:
Automatic metrics: a program computes the score, and the same input
always gets the same score.
Automatic metrics differ in what they compare. There are three main kinds:
surface metrics count the words or characters that the output shares
with the reference, for instance BLEU (Papineni et al., 2002) and chrF
(Popović, 2015);
learned metrics are trained on human judgements to predict the score
a person would give, for instance COMET (Rei et al., 2020); some work
without a reference, which is called quality estimation.
In 2021, on the largest collection of human judgements then available,
learned metrics ranked pairs of systems more like people than surface
metrics did (Kocmi et al., 2021).
In 2025, large language models used as judges were the best at ranking
whole systems. On single sentences, simple metrics that compare the output
with a reference, surface ones such as chrF and embedding-based ones such
as BERTScore, were among the best, ahead of most learned metrics and model
judges; only one model judge and one learned metric equalled or exceeded
them. The organizers call this result surprising (Lavie et al., 2025).
Large language models as judges
A large language model used as a judge receives the source, the output,
the reference if there is one, and an instruction saying what to judge and
in what form to answer (Kocmi & Federmann, 2023a). It can give a score, a
list of errors with their category and severity, or both.
Model judges rank whole systems well, but most score single sentences less
reliably, as the 2025 results above show.
Raters disagree, since a source can be ambiguous and raters know
different things and use scales differently; evaluations remove outlier
raters and normalize their scores (Jurafsky & Martin, 2026).
The table below compares the three families on eight criteria, with the
automatic metrics split in two. A reference translation for every test
sentence is expensive, and for some language pairs and domains there is
none, so the need for a reference often decides which methods can be used
at all.
Surface metrics
Semantic and learned metrics
Large language model as judge
People
Reference needed
yes
yes for most; quality estimation works without
optional
no for error annotation; optional for scores and comparisons
Which method fits depends partly on what the evaluation is for. Machine
translation is evaluated for several purposes:
to compare systems, as WMT does every year, and as a company does
before choosing a system;
to guide development, where a fast automatic score shows whether a
change helped;
to find errors, which needs more than a score: where the errors are,
of what kind, and how serious;
to decide what the output can be used for: good enough to understand a
web page is not always good enough to publish, and the question is answered
mainly by reading the output.
Sources
Freitag, M., Foster, G., Grangier, D., Ratnakar, V., Tan, Q., & Macherey, W. (2021). Experts, Errors, and Context: A Large-Scale Study of Human Evaluation for Machine Translation. Transactions of the Association for Computational Linguistics, 9, 1460–1474. https://doi.org/10.1162/tacl_a_00437
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., & Federmann, C. (2023a). GEMBA-MQM: Detecting Translation Quality Error Spans with GPT-4. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), 768–775. https://doi.org/10.18653/v1/2023.wmt-1.64
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Kocmi, T., Zouhar, V., Avramidis, E., Grundkiewicz, R., Karpinska, M., Popović, M., et al. (2024a). Error Span Annotation: A Balanced Approach for Human Evaluation of Machine Translation. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1440–1453. https://doi.org/10.18653/v1/2024.wmt-1.131
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Popović, M. (2015). chrF: character n-gram F-score for automatic MT evaluation. Proceedings of the Tenth Workshop on Statistical Machine Translation (WMT 2015), Lisbon, 392–395. https://doi.org/10.18653/v1/W15-3049
Rei, R., Stewart, C., Farinha, A. C., & Lavie, A. (2020). COMET: A Neural Framework for MT Evaluation. Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP 2020), 2685–2702. https://doi.org/10.18653/v1/2020.emnlp-main.213
Zhang, T., Kishore, V., Wu, F., Weinberger, K. Q., & Artzi, Y. (2020). BERTScore: Evaluating Text Generation with BERT. Eighth International Conference on Learning Representations (ICLR 2020). http://arxiv.org/abs/1904.09675
réunit donc les deux. Ses couleurs montrent que de nombreuses méthodes
peuvent fonctionner avec ou sans référence.
Figure 3. Les façons d'évaluer la traduction automatique, selon qui ou quoi juge, colorées selon l'emploi d'une traduction de référence. Les métriques et les protocoles nommés sont des exemples, non des listes complètes. Les combinaisons en pointillé existent, mais sont moins courantes dans l'évaluation actuelle de la traduction automatique, où les personnes annotent les erreurs et les méthodes automatiques donnent des scores (Kocmi et al., 2025) ; ce chapitre ne les traite pas.
Les lignes de la figure correspondent aux trois familles de méthodes :
Les métriques automatiques : un programme calcule le score, et une
même entrée reçoit toujours le même score.
Des personnes : des évaluateurs jugent eux-mêmes la traduction.
Les métriques automatiques
Les métriques automatiques diffèrent par ce qu’elles comparent. On en
distingue trois grands types :
les métriques de surface comptent les mots ou les caractères que la
sortie partage avec la référence, par exemple BLEU (Papineni et al., 2002)
et chrF (Popović, 2015) ;
les métriques apprises sont entraînées sur des jugements humains pour
prédire le score qu’une personne donnerait, par exemple COMET (Rei et al.,
2020) ; certaines fonctionnent sans référence, ce qu’on appelle
l’estimation de la qualité.
En 2021, sur la plus grande collection de jugements humains alors
disponible, les métriques apprises classaient des paires de systèmes plus
comme les personnes que les métriques de surface (Kocmi et al., 2021).
En 2025, les grands modèles de langue employés comme juges étaient les
meilleurs pour classer des systèmes entiers. Sur des phrases isolées, des
métriques simples qui comparent la sortie avec une référence, de surface
comme chrF ou fondées sur des plongements comme BERTScore, comptaient parmi
les meilleures, devant la plupart des métriques apprises et des modèles
juges ; seuls un modèle juge et une métrique apprise les égalaient ou les
dépassaient. Les organisateurs qualifient ce résultat de surprenant (Lavie
et al., 2025).
Les grands modèles de langue comme juges
Un grand modèle de langue employé comme juge reçoit la source, la sortie,
la référence s’il y en a une, et une consigne qui dit quoi juger et sous
quelle forme répondre (Kocmi & Federmann, 2023a). Il peut donner un score,
une liste d’erreurs avec leur catégorie et leur gravité, ou les deux.
Les modèles juges classent bien des systèmes entiers, mais la plupart
notent les phrases isolées de façon moins fiable, comme le montrent les
résultats de 2025 ci-dessus.
Les évaluateurs ne sont pas toujours d’accord, parce qu’une source peut
être ambiguë et que les évaluateurs n’ont pas les mêmes connaissances ni la
même façon d’utiliser une échelle ; les évaluations écartent les
évaluateurs aberrants et normalisent leurs scores (Jurafsky & Martin,
2026).
Le tableau ci-dessous compare les trois familles selon huit critères, en
séparant les métriques automatiques en deux. Une traduction de référence pour
chaque phrase de test coûte cher, et pour certaines paires de langues et
certains domaines il n’en existe pas : la nécessité d’une référence décide
donc souvent des méthodes qui peuvent être employées.
Métriques de surface
Métriques sémantiques et apprises
Grand modèle de langue comme juge
Personnes
Référence nécessaire
oui
oui pour la plupart ; l’estimation de la qualité s’en passe
facultative
non pour l’annotation des erreurs ; facultative pour les scores et les comparaisons
un score ; certaines métriques marquent aussi des passages erronés
un score, une liste d’erreurs, ou les deux
des erreurs avec type et gravité, ou un score
Accord avec les personnes
inférieur aux métriques apprises en 2021 (Kocmi et al., 2021) ; parmi les meilleurs sur des phrases isolées en 2025 (Lavie et al., 2025)
supérieur aux métriques de surface en 2021 ; sur des phrases isolées en 2025, BERTScore parmi les meilleures, la plupart des métriques apprises derrière
le meilleur pour classer des systèmes en 2025, moins fiable par phrase
la norme à laquelle les autres sont mesurées, avec des désaccords entre personnes
Explicabilité
oui : le comptage peut être refait à la main
non : c’est la sortie d’un modèle
en partie : le modèle donne des raisons, mais elles sont générées elles aussi
oui
Réemploi sur une nouvelle sortie
oui, sans frais, une fois la référence disponible
oui, au prix de l’exécution du modèle
oui, mais un autre modèle ou une autre requête donne d’autres scores
non : chaque nouvelle sortie demande de nouveaux jugements
Coût
négligeable
un modèle à exécuter
un modèle à interroger, phrase par phrase
élevé : du temps et de l’expertise
Robustesse selon les langues, les domaines et les paraphrases
La méthode qui convient dépend en partie de ce à quoi sert l’évaluation. La
traduction automatique est évaluée à plusieurs fins :
pour comparer des systèmes, comme le fait WMT chaque année, et comme le
fait une entreprise avant de choisir un système ;
pour guider le développement, où un score automatique rapide montre si
une modification a aidé ;
pour trouver les erreurs, ce qui demande plus qu’un score : où sont les
erreurs, de quel type, et quelle est leur gravité ;
pour décider de l’usage possible de la sortie : assez bonne pour
comprendre une page Web ne veut pas toujours dire assez bonne pour être
publiée, et la question se tranche surtout en lisant la sortie.
Sources
Freitag, M., Foster, G., Grangier, D., Ratnakar, V., Tan, Q., & Macherey, W. (2021). Experts, Errors, and Context: A Large-Scale Study of Human Evaluation for Machine Translation. Transactions of the Association for Computational Linguistics, 9, 1460–1474. https://doi.org/10.1162/tacl_a_00437
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., & Federmann, C. (2023a). GEMBA-MQM: Detecting Translation Quality Error Spans with GPT-4. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), 768–775. https://doi.org/10.18653/v1/2023.wmt-1.64
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Kocmi, T., Zouhar, V., Avramidis, E., Grundkiewicz, R., Karpinska, M., Popović, M., et al. (2024a). Error Span Annotation: A Balanced Approach for Human Evaluation of Machine Translation. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1440–1453. https://doi.org/10.18653/v1/2024.wmt-1.131
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Popović, M. (2015). chrF: character n-gram F-score for automatic MT evaluation. Proceedings of the Tenth Workshop on Statistical Machine Translation (WMT 2015), Lisbon, 392–395. https://doi.org/10.18653/v1/W15-3049
Rei, R., Stewart, C., Farinha, A. C., & Lavie, A. (2020). COMET: A Neural Framework for MT Evaluation. Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP 2020), 2685–2702. https://doi.org/10.18653/v1/2020.emnlp-main.213
Zhang, T., Kishore, V., Wu, F., Weinberger, K. Q., & Artzi, Y. (2020). BERTScore: Evaluating Text Generation with BERT. Eighth International Conference on Learning Representations (ICLR 2020). http://arxiv.org/abs/1904.09675
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 4. BLEU computed by hand for one output against one reference.
The method has two further details (Papineni et al., 2002).
The counts are clipped. A word of the output counts only as many times
as it occurs in the reference, which is why Papineni et al. (2002) speak of
a modified n-gram precision. Without this, the output the the the the the
the the would have a perfect single-word precision against The cat is on
the mat; with it, the precision is 2/7, since the occurs twice in the
reference.
The three give the same result when the numbers are equal. When they are not,
the geometric and the harmonic mean are pulled towards the smallest numbers,
and both are zero as soon as one number is zero. The table below applies the
three to the four precisions of Figure 4figure 4.
Mean
Computed as
Result
arithmetic
(5/6 + 3/5 + 2/4 + 1/3) / 4
0.57
geometric
⁴√(5/6 × 3/5 × 2/4 × 1/3)
0.54
harmonic
4 / (6/5 + 5/3 + 4/2 + 3/1)
0.51
Three means of the same four precisions.
Papineni et al. (2002) chose the geometric mean because the precisions fall
steeply from single words to quadruples, and in their tests it agreed
slightly better with human judgements than the arithmetic mean. They also
note its cost: one precision of zero makes the whole score zero.
An output shorter than the reference
In Figure 5figure 5,
the output differs from the reference in two places, un for le and the
missing du salon, and it is shorter, so the brevity penalty applies.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 5. BLEU computed by hand for an output shorter than its reference.
The missing du salon lowers none of the four precisions, since a precision
only looks at what the output contains. The brevity penalty is the only part
of BLEU that registers what the output leaves out.
To avoid this, tools that give a BLEU score per sentence apply a correction,
called smoothing: a precision of zero gets a small value instead, so that a
sentence with no shared quadruple no longer scores zero. Several such
corrections exist, and they give different scores for the same sentence
(Chen & Cherry, 2014), so a BLEU score for one sentence is only a rough
indication.
Weaknesses of BLEU
BLEU compares the exact words of the output with those of the reference
(Jurafsky & Martin, 2026), which has five consequences:
Synonyms and paraphrases.Félin for chat loses 46 points in the
figure. A translation that says the same thing in other words is scored
lower.
Errors of meaning.Le chien est sur le tapis names the wrong animal
and scores 54, exactly like Le félin est sur le tapis: BLEU counts how
many words differ from the reference, not what the difference does to the
meaning.
Word order.Sur le tapis est le chat contains every word of the
reference and scores 0 at sentence level: the order is only rewarded
through the longer n-grams, which the new order has broken.
Inflection.Les chats sont sur le tapis shares three words of six
with the reference and scores 0 for the same reason; BLEU works less well
for languages with complex morphology (Jurafsky & Martin, 2026).
A BLEU score runs from 0 to 1 and is usually reported from 0 to 100. The
higher the score, the more of its n-grams the output shares with the
reference, so higher is better. The score is not a percentage of correct
words, though, and there is no fixed scale on which a given value means good
or bad:
A good translation scores far below 100. A translation by a person
rarely matches a reference word for word, so it scores low as well: in the
paper that introduced BLEU, one human translation of Chinese news into
English scored 35 when compared with four reference translations, and 26
when compared with two (Papineni et al., 2002).
The number of references changes the score, as those two figures show:
with more references, an n-gram of the output has more chances to occur in
one of them.
Scores from different languages are not comparable. In a language
with rich morphology, more of the words differ from the reference by their
form alone.
Chen, B., & Cherry, C. (2014). A Systematic Comparison of Smoothing Techniques for Sentence-Level BLEU. Proceedings of the Ninth Workshop on Statistical Machine Translation, 362–367. https://doi.org/10.3115/v1/W14-3346
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Post, M. (2018). A Call for Clarity in Reporting BLEU Scores. Proceedings of the Third Conference on Machine Translation: Research Papers (WMT 2018), 186–191. https://doi.org/10.18653/v1/W18-6319
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 4. BLEU calculé à la main pour une sortie par rapport à une référence.
La méthode comporte deux autres détails (Papineni et al., 2002).
Les comptes sont plafonnés. Un mot de la sortie ne compte qu’autant de
fois qu’il apparaît dans la référence, d’où le nom de précision modifiée
des n-grammes que lui donnent Papineni et al. (2002). Sans ce plafond, la
sortie the the the the the the the aurait une précision parfaite pour
les mots isolés par rapport à The cat is on the mat ; avec lui, la
précision est de 2/7, puisque the apparaît deux fois dans la référence.
Les trois donnent le même résultat quand les nombres sont égaux. Sinon, la
moyenne géométrique et la moyenne harmonique sont tirées vers les plus petits
nombres, et toutes deux valent zéro dès qu’un des nombres vaut zéro. Le
tableau ci-dessous applique les trois aux quatre précisions de la
Figure 4figure 4.
Moyenne
Calcul
Résultat
arithmétique
(5/6 + 3/5 + 2/4 + 1/3) / 4
0,57
géométrique
⁴√(5/6 × 3/5 × 2/4 × 1/3)
0,54
harmonique
4 / (6/5 + 5/3 + 4/2 + 3/1)
0,51
Trois moyennes des mêmes quatre précisions.
Papineni et al. (2002) ont choisi la moyenne géométrique parce que les
précisions chutent fortement des mots isolés aux quadruplets, et que, dans
leurs essais, elle s’accordait un peu mieux avec les jugements humains que la
moyenne arithmétique. Ils en notent aussi le prix : une seule précision nulle
rend tout le score nul.
Une sortie plus courte que la référence
Dans la Figure 5figure 5,
la sortie diffère de la référence en deux endroits, un pour le et
l’absence de du salon, et elle est plus courte : la pénalité de brièveté
s’applique.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 5. BLEU calculé à la main pour une sortie plus courte que sa référence.
L’absence de du salon ne fait baisser aucune des quatre précisions,
puisqu’une précision ne regarde que ce que contient la sortie. La pénalité
de brièveté est la seule partie de BLEU qui enregistre ce que la sortie
laisse de côté.
Pour l’éviter, les outils qui donnent un score BLEU par phrase appliquent
une correction, appelée lissage : une précision nulle reçoit à la place une
petite valeur, si bien qu’une phrase sans quadruplet partagé n’obtient plus
zéro. Il existe plusieurs corrections de ce type, et elles donnent des
scores différents pour la même phrase (Chen & Cherry, 2014) : un score BLEU
pour une seule phrase n’est donc qu’une indication approximative.
Les faiblesses de BLEU
BLEU compare les mots exacts de la sortie avec ceux de la référence
(Jurafsky & Martin, 2026), ce qui a cinq conséquences :
Les synonymes et les paraphrases.Félin pour chat fait perdre
46 points dans la figure. Une traduction qui dit la même chose en d’autres
mots obtient un score plus bas.
Les erreurs de sens.Le chien est sur le tapis nomme le mauvais
animal et obtient 54, exactement comme Le félin est sur le tapis : BLEU
compte combien de mots diffèrent de la référence, et non ce que la
différence fait au sens.
L’ordre des mots.Sur le tapis est le chat contient tous les mots de
la référence et obtient 0 au niveau de la phrase : l’ordre n’est récompensé
que par les n-grammes plus longs, que le nouvel ordre a brisés.
La flexion.Les chats sont sur le tapis partage trois mots sur six
avec la référence et obtient 0 pour la même raison ; BLEU fonctionne moins
bien pour les langues à morphologie complexe (Jurafsky & Martin, 2026).
Un score BLEU va de 0 à 1 et est habituellement présenté de 0 à 100. Plus le
score est élevé, plus la sortie partage de n-grammes avec la référence : un
score plus élevé est donc meilleur. Le score n’est cependant pas un
pourcentage de mots corrects, et aucune échelle fixe ne dit qu’une valeur
donnée est bonne ou mauvaise :
Une bonne traduction obtient bien moins de 100. Une traduction faite
par une personne correspond rarement mot pour mot à une référence, si bien
qu’elle obtient elle aussi un score bas : dans l’article qui a présenté
BLEU, une traduction humaine d’actualités chinoises vers l’anglais
obtenait 35 par rapport à quatre traductions de référence, et 26 par
rapport à deux (Papineni et al., 2002).
Le nombre de références change le score, comme le montrent ces deux
chiffres : avec plus de références, un n-gramme de la sortie a plus de
chances de figurer dans l’une d’elles.
Les scores de langues différentes ne sont pas comparables. Dans une
langue à morphologie riche, davantage de mots diffèrent de la référence par
leur seule forme.
Chen, B., & Cherry, C. (2014). A Systematic Comparison of Smoothing Techniques for Sentence-Level BLEU. Proceedings of the Ninth Workshop on Statistical Machine Translation, 362–367. https://doi.org/10.3115/v1/W14-3346
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Post, M. (2018). A Call for Clarity in Reporting BLEU Scores. Proceedings of the Third Conference on Machine Translation: Research Papers (WMT 2018), 186–191. https://doi.org/10.18653/v1/W18-6319
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 6. chrF computed by hand for the same output and reference as on the BLEU page.
The usual setting, written chrF2, uses character n-grams up to length 6 and
the weight of 2 on recall. Of the lengths Popović (2015) tested (4, 6 and
10), 6 agreed best with human rankings; of the two weights she compared, 1
and 3, the weight of 3 agreed better, and she chose it as a preliminary
value. Jurafsky and Martin (2026) give 2 as the common choice. A variant, chrF++, adds word unigrams and bigrams to the count (Popović, 2017).
The effect of counting characters
On the pair in the figure, chrF gives 65 where BLEU gave 54: a synonym still
costs points, since félin and chat share no characters, but the rest of
the sentence still matches. In the table below, the difference between the
two metrics is largest when the words differ only slightly, or only in their
order.
Output
Difference
BLEU
chrF
Le félin est sur le tapis
one synonym
54
65
Les chats sont sur le tapis
plural
0
63
Sur le tapis est le chat
word order
0
71
Le félin se trouve sur le tapis
synonym and a paraphrase
0
48
Sentence-level BLEU and chrF for outputs against the reference Le chat est sur le tapis. Computed by hand on lowercased text; sentence BLEU without smoothing.
In other respects chrF has the limits of BLEU. It is a surface metric: it compares
sequences of characters, not meanings, so a correct translation in other
words still scores low, and “a large phrase that is moved around might
barely change the chrF score” (Jurafsky & Martin, 2026), even when the move
changes the meaning. It also needs a reference, with the limits that a single
reference brings (see also the Many correct translations page, in the Evaluating language technology module) (voir aussi la page De nombreuses traductions correctes, dans le module L'évaluation des technologies langagières).
chrF in current use
Among the metrics that count words or characters, chrF agreed best with human judgements
in the comparison of Kocmi et al. (2021), who recommend it where a trained
metric cannot be used. The WMT organizers still rely on it in exactly that
case: for the two lowest-resource languages of the 2025 task, Bhojpuri and
Maasai, where the reliability of the main metrics had not been established,
the automatic ranking used chrF++ alone (Kocmi et al., 2025). It
is also easy to compute and to check by hand. At the 2025 metrics task, it
was in the top three rank clusters for scoring single sentences, with other
simple metrics that compare the output with a reference, ahead of most
trained metrics (Lavie et al., 2025).
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24
Popović, M. (2015). chrF: character n-gram F-score for automatic MT evaluation. Proceedings of the Tenth Workshop on Statistical Machine Translation (WMT 2015), Lisbon, 392–395. https://doi.org/10.18653/v1/W15-3049
Popović, M. (2017). chrF++: words helping character n-grams. Proceedings of the Second Conference on Machine Translation (WMT 2017), Copenhagen, 612–618. https://doi.org/10.18653/v1/W17-4770
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 6. chrF calculé à la main pour la même sortie et la même référence que sur la page sur BLEU.
Le réglage habituel, noté chrF2, emploie des n-grammes de caractères allant
jusqu’à 6 et un poids de 2 pour le rappel. Des longueurs que Popović (2015) a
testées (4, 6 et 10), 6 s’accordait le mieux avec les classements humains ;
des deux poids qu’elle a comparés, 1 et 3, le poids de 3 s’accordait mieux,
et elle l’a retenu comme valeur provisoire. Jurafsky et Martin (2026)
donnent 2 comme le choix courant. Une variante, chrF++, ajoute au comptage les mots
isolés et les paires de mots (Popović, 2017).
L’effet du comptage des caractères
Sur la paire de la figure, chrF donne 65 là où BLEU donnait 54 : un synonyme
coûte encore des points, puisque félin et chat n’ont aucun caractère en
commun, mais le reste de la phrase correspond toujours. Dans le tableau
ci-dessous, l’écart entre les deux métriques est le plus grand quand les
mots ne diffèrent que légèrement, ou seulement par leur ordre.
Sortie
Différence
BLEU
chrF
Le félin est sur le tapis
un synonyme
54
65
Les chats sont sur le tapis
le pluriel
0
63
Sur le tapis est le chat
l’ordre des mots
0
71
Le félin se trouve sur le tapis
un synonyme et une paraphrase
0
48
BLEU et chrF de phrase pour des sorties comparées avec la référence Le chat est sur le tapis. Calculés à la main sur le texte en minuscules ; BLEU de phrase sans lissage.
Pour le reste, chrF a les limites de BLEU. C’est une métrique de surface :
elle compare des suites de caractères, et non des sens, si bien qu’une
traduction correcte formulée autrement obtient toujours un score bas, et
« a large phrase that is moved around might barely change the chrF score »
[ma traduction : « un long segment déplacé peut à peine modifier le score
chrF »] (Jurafsky & Martin, 2026), même quand le déplacement change le sens.
Elle exige aussi une référence, avec les limites qu’apporte une référence
unique (see also the Many correct translations page, in the Evaluating language technology module) (voir aussi la page De nombreuses traductions correctes, dans le module L'évaluation des technologies langagières).
chrF dans l’usage actuel
Parmi les métriques qui comptent des mots ou des caractères, chrF
s’accordait le mieux avec les jugements humains dans la comparaison de
Kocmi et al. (2021), qui le recommandent quand une métrique entraînée ne
peut pas être employée. Les organisateurs de WMT y recourent encore
précisément dans ce cas : pour les deux langues les moins dotées de la
tâche de 2025, le bhojpuri et le massaï, pour lesquelles la fiabilité des
métriques principales n’avait pas été établie, le classement automatique a
employé chrF++ seul (Kocmi et al., 2025). chrF est aussi facile à calculer
et à vérifier à la main. À la tâche d’évaluation des métriques de 2025, il
figurait dans les trois premiers groupes de rangs pour noter des phrases
isolées, avec d’autres métriques simples qui comparent la sortie avec une
référence, devant la plupart des métriques entraînées (Lavie et al., 2025).
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24
Popović, M. (2015). chrF: character n-gram F-score for automatic MT evaluation. Proceedings of the Tenth Workshop on Statistical Machine Translation (WMT 2015), Lisbon, 392–395. https://doi.org/10.18653/v1/W15-3049
Popović, M. (2017). chrF++: words helping character n-grams. Proceedings of the Second Conference on Machine Translation (WMT 2017), Copenhagen, 612–618. https://doi.org/10.18653/v1/W17-4770
SourceSourceLe gouvernement a annoncé des mesures importantes concernant le télétravail, avec effet immédiat.
OutputSortie
ReferenceRéférence
aalso in the other textaussi dans l'autre texteanot in the other textabsent de l'autre texteHover over an n-gram to find it in the other text.Survolez un n-gramme pour le retrouver dans l'autre texte.
n
Precision (output)Précision (sortie)
Recall (reference)Rappel (référence)
Three comparisons are worth making:
Words against characters. Against reference A, Google Translate shares
no sequence of four words, so its sentence BLEU is 0, but it shares many
characters, so its chrF stays well above that.
Longer n-grams. Raising n in words shows how quickly the shared
sequences run out, and why a sentence that shares no sequence of four
words with the reference gets a BLEU of zero.
The other reference. A translation that matches reference A word for
word scores much lower against reference B on both metrics, although both
references are correct.
Sources
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Popović, M. (2015). chrF: character n-gram F-score for automatic MT evaluation. Proceedings of the Tenth Workshop on Statistical Machine Translation (WMT 2015), Lisbon, 392–395. https://doi.org/10.18653/v1/W15-3049
SourceSourceLe gouvernement a annoncé des mesures importantes concernant le télétravail, avec effet immédiat.
OutputSortie
ReferenceRéférence
aalso in the other textaussi dans l'autre texteanot in the other textabsent de l'autre texteHover over an n-gram to find it in the other text.Survolez un n-gramme pour le retrouver dans l'autre texte.
n
Precision (output)Précision (sortie)
Recall (reference)Rappel (référence)
Trois comparaisons valent la peine d’être faites :
Les mots ou les caractères. Par rapport à la référence A, Google
Translate ne partage aucune suite de quatre mots : son BLEU de phrase vaut
donc 0, mais il partage beaucoup de caractères, et son chrF reste nettement
au-dessus.
Les n-grammes plus longs. En augmentant n pour les mots, vous voyez à
quelle vitesse les suites partagées s’épuisent, et pourquoi une phrase qui
ne partage aucune suite de quatre mots avec la référence obtient un BLEU
de zéro.
L’autre référence. Une traduction qui correspond mot pour mot à la
référence A obtient un score bien plus bas par rapport à la référence B,
avec les deux métriques, bien que les deux références soient correctes.
Sources
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Popović, M. (2015). chrF: character n-gram F-score for automatic MT evaluation. Proceedings of the Tenth Workshop on Statistical Machine Translation (WMT 2015), Lisbon, 392–395. https://doi.org/10.18653/v1/W15-3049
ExerciseExercice 1 · word precisionla précision des motsnot startedà fairesolvedréussikeep tryingà retravailler
What is the precision of the single words (1-grams) of the output against the reference? Give a fraction or a number rounded to two decimals.
Quelle est la précision des mots isolés (1-grammes) de la sortie par rapport à la référence ? Donnez une fraction ou un nombre arrondi à deux décimales.
Show the explanationVoir l'explication
Six of the seven words of the output are in the reference; only begins is not. The 1-gram precision is therefore 6 / 7 = 0.86.
Six des sept mots de la sortie figurent dans la référence ; seul begins n'y est pas. La précision des 1-grammes est donc 6 / 7 = 0,86.
ExerciseExercice 2 · shared word pairsles paires de mots partagéesnot startedà fairesolvedréussikeep tryingà retravailler
How many pairs of consecutive words (2-grams) of the output also occur in the reference?
Combien de paires de mots consécutifs (2-grammes) de la sortie se retrouvent dans la référence ?
Show the explanationVoir l'explication
The output has six pairs: the meeting, meeting begins, begins at, at nine, nine tomorrow, tomorrow morning. The two that contain begins are not in the reference; the other four are, a 2-gram precision of 4 / 6. One changed word costs two pairs, three triples and three quadruples: that is how BLEU punishes a synonym.
La sortie compte six paires : the meeting, meeting begins, begins at, at nine, nine tomorrow, tomorrow morning. Les deux qui contiennent begins ne sont pas dans la référence ; les quatre autres y sont, soit une précision des 2-grammes de 4 / 6. Un seul mot changé coûte deux paires, trois triplets et trois quadruplets : c'est ainsi que BLEU punit un synonyme.
A third output, The meeting starts at nine, matches the reference word for word but stops after five words. What does BLEU do with it?
Une troisième sortie, The meeting starts at nine, reprend la référence mot pour mot mais s'arrête après cinq mots. Que fait BLEU de cette sortie ?
Show the solutionVoir la solution
All four precisions are 1, since every n-gram of the output is in the reference. But the output has 5 words against 7, and BLEU then multiplies the score by e(1 − 7/5) ≈ 0.67: the output scores 67, not 100. The brevity penalty stands in for recall, which BLEU does not compute.
Les quatre précisions valent 1, puisque chaque n-gramme de la sortie est dans la référence. Mais la sortie compte 5 mots contre 7, et BLEU multiplie alors le score par e(1 − 7/5) ≈ 0,67 : la sortie obtient 67, pas 100. La pénalité de brièveté remplace le rappel, que BLEU ne calcule pas.
The output The meeting begins at nine tomorrow morning scores 49 on BLEU and 78 on chrF. Which of the following outputs scores lower on BLEU and higher on chrF than it does?
La sortie The meeting begins at nine tomorrow morning obtient 49 en BLEU et 78 en chrF. Laquelle des sorties suivantes obtient un BLEU plus bas et un chrF plus haut qu'elle ?
Show the solutionVoir la solution
In The meetings start at nine tomorrow morning, two of the seven words differ from the reference (meetings, start), which costs BLEU more than a single synonym did: 43 against 49. For chrF only a few characters change (one s moves): 85 against 78. The three other outputs use only words of the reference, so their BLEU goes up (71, 67 and 85).
Dans The meetings start at nine tomorrow morning, deux mots sur sept diffèrent de la référence (meetings, start), ce qui coûte à BLEU plus qu'un seul synonyme : 43 contre 49. Pour chrF, seuls quelques caractères changent (un s déplacé) : 85 contre 78. Les trois autres propositions n'emploient que des mots de la référence, donc leur BLEU monte (71, 67 et 85).
Sources
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Popović, M. (2015). chrF: character n-gram F-score for automatic MT evaluation. Proceedings of the Tenth Workshop on Statistical Machine Translation (WMT 2015), Lisbon, 392–395. https://doi.org/10.18653/v1/W15-3049
Semantic and learned metricsLes métriques sémantiques et apprises
Figure 7. The matching behind BERTScore, for an output that differs from the reference by one synonym. The similarities are illustrative.
Against the reference people like foreign cars, BLEU prefers people like
visiting places abroad, which shares two words with it, to consumers prefer
imported cars, which shares none; BERTScore ranks them the other way round
(Zhang et al., 2020).
A high similarity shows that the output is about the same thing as the
reference; it does not show that the output says the same thing. BERTScore
is less sensitive to small errors when the output is close to the reference
in its words and style (Hanna & Bojar, 2021). Surface metrics share this
weakness, and in the same study BLEU did worse than BERTScore. A not added to an output, for instance, reverses its meaning
while leaving almost every word and character shared with the reference.
Metrics trained on human judgements
A learned metric is trained on translations that people rated, to predict
the rating a person would give. COMET (Rei et al., 2020) reads the source, the
output and the reference. Two variants are common:
without a reference, from the source and the output alone, which is
called quality estimation, for instance CometKiwi (Rei et al., 2022);
with error spans, marking the words rated as errors with a severity,
so that the score comes with a reason, for instance xCOMET (Guerreiro et
al., 2024).
Metrics multiply, and their details change from one version to the next.
Reading a score therefore starts with checking which kind of metric produced
it and how it was used: what it compares, whether it learned from human
ratings, and whether it needed a reference.
Figure 8figure 8 shows
what each kind of metric reads, and the table below sets out the main
metrics of this chapter by these differences.
Figure 8. What each kind of automatic metric reads, and what it does with it.
Metric
Kind
Compares
Reference needed
BLEU (Papineni et al., 2002)
surface
shared words
yes
chrF (Popović, 2015)
surface
shared characters
yes
BERTScore (Zhang et al., 2020)
semantic
contextual embeddings
yes
COMET (Rei et al., 2020)
learned
predicts a human rating from the source, the output and the reference
usually; versions without a reference exist
BLEURT (Sellam et al., 2020)
learned
predicts a human rating from the output and the reference
yes
xCOMET (Guerreiro et al., 2024)
learned
predicts a rating and marks error spans
optional
CometKiwi (Rei et al., 2022)
learned, quality estimation
predicts a rating from the source and the output
no
The main automatic metrics for translation, by what they compare and what they need.
A score you cannot check. A BLEU count can be redone by hand; the
output of a trained model cannot, unless the metric marks error spans.
Languages. A learned metric is only as good as the languages it was
trained on: WMT 2025 fell back on chrF++ for two languages for which the
reliability of its main metrics had not been
established (see also the chrF page, in the Evaluating language technology module) (voir aussi la page chrF, dans le module L'évaluation des technologies langagières).
Tuning to the metric. A system can generate several candidate
translations and keep the one the metric prefers
(Figure 9figure 9).
In 2024 the system that led the automatic ranking had chosen among its
candidates with COMET, the metric used for that ranking; people did not
rank it first in every language pair, a gap the organizers attribute,
probably, to metric bias (Kocmi et al., 2024b) (see also the Reading a leaderboard page, in the Using LLMs module) (voir aussi la page Lire un classement, dans le module Utiliser les GML).
Figure 9. Metric bias: a system comes first on the metric but not everywhere with people.
Sources
Guerreiro, N. M., Rei, R., van Stigt, D., Coheur, L., Colombo, P., & Martins, A. F. T. (2024). xCOMET: Transparent Machine Translation Evaluation through Fine-grained Error Detection. Transactions of the Association for Computational Linguistics, 12, 979–995. https://doi.org/10.1162/tacl_a_00683
Hanna, M., & Bojar, O. (2021). A Fine-Grained Analysis of BERTScore. Proceedings of the Sixth Conference on Machine Translation, 507–517. https://aclanthology.org/2021.wmt-1.59/
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Popović, M. (2015). chrF: character n-gram F-score for automatic MT evaluation. Proceedings of the Tenth Workshop on Statistical Machine Translation (WMT 2015), Lisbon, 392–395. https://doi.org/10.18653/v1/W15-3049
Rei, R., Stewart, C., Farinha, A. C., & Lavie, A. (2020). COMET: A Neural Framework for MT Evaluation. Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP 2020), 2685–2702. https://doi.org/10.18653/v1/2020.emnlp-main.213
Rei, R., Treviso, M., Guerreiro, N. M., Zerva, C., Farinha, A. C., Maroti, C., de Souza, J. G. C., Glushkova, T., Alves, D., Lavie, A., Coheur, L., & Martins, A. F. T. (2022). CometKiwi: IST-Unbabel 2022 Submission for the Quality Estimation Shared Task. Proceedings of the Seventh Conference on Machine Translation (WMT 2022), Abu Dhabi, 634–645. https://doi.org/10.18653/v1/2022.wmt-1.60
Sellam, T., Das, D., & Parikh, A. P. (2020). BLEURT: Learning Robust Metrics for Text Generation. Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics (ACL 2020), 7881–7892. https://doi.org/10.18653/v1/2020.acl-main.704
Zhang, T., Kishore, V., Wu, F., Weinberger, K. Q., & Artzi, Y. (2020). BERTScore: Evaluating Text Generation with BERT. Eighth International Conference on Learning Representations (ICLR 2020). http://arxiv.org/abs/1904.09675
Figure 7. L'appariement sur lequel repose BERTScore, pour une sortie qui diffère de la référence par un synonyme. Les similarités sont données à titre d'illustration.
Par rapport à la référence anglaise people like foreign cars, BLEU
préfère people like visiting places abroad, qui partage deux mots avec
elle, à consumers prefer imported cars, qui n’en partage aucun ; BERTScore
les classe dans l’ordre inverse (Zhang et al., 2020).
Une similarité élevée montre que la sortie parle de la même chose que la
référence ; elle ne montre pas que la sortie dit la même chose. BERTScore
est moins sensible aux petites erreurs quand la sortie est proche de la
référence par ses mots et son style (Hanna & Bojar, 2021). Les métriques de
surface ont la même faiblesse, et dans la même étude, BLEU faisait moins
bien que BERTScore. Une négation ajoutée à une sortie, par exemple, en
inverse le sens tout en laissant presque tous les mots et les caractères en commun avec
la référence.
Les métriques entraînées sur des jugements humains
Une métrique apprise est entraînée sur des traductions que des personnes ont
notées, pour prédire la note qu’une personne donnerait. COMET (Rei et al.,
2020) lit la source, la sortie et la référence. Deux variantes sont
courantes :
sans référence, à partir de la source et de la sortie seules, ce qu’on
appelle l’estimation de la qualité, par exemple CometKiwi (Rei et al., 2022) ;
avec des passages erronés, qui marquent les mots jugés erronés avec
une gravité, si bien que le score s’accompagne d’une raison, par exemple
xCOMET (Guerreiro et al., 2024).
Les métriques se multiplient, et leurs détails changent d’une version à
l’autre. Lire un score commence donc par vérifier quel type de métrique l’a
produit et comment elle a été employée : ce qu’elle compare, si elle a
appris à partir de notes humaines, et si elle avait besoin d’une référence.
La Figure 8figure 8
montre ce que lit chaque type de métrique, et le tableau ci-dessous présente
les principales métriques du chapitre selon ces différences.
Figure 8. Ce que lit chaque type de métrique automatique, et ce qu'elle en fait.
Métrique
Type
Compare
Référence nécessaire
BLEU (Papineni et al., 2002)
surface
les mots partagés
oui
chrF (Popović, 2015)
surface
les caractères partagés
oui
BERTScore (Zhang et al., 2020)
sémantique
des plongements contextuels
oui
COMET (Rei et al., 2020)
apprise
prédit une note humaine à partir de la source, de la sortie et de la référence
habituellement ; des versions sans référence existent
BLEURT (Sellam et al., 2020)
apprise
prédit une note humaine à partir de la sortie et de la référence
oui
xCOMET (Guerreiro et al., 2024)
apprise
prédit une note et marque les passages erronés
facultative
CometKiwi (Rei et al., 2022)
apprise, estimation de la qualité
prédit une note à partir de la source et de la sortie
non
Les principales métriques automatiques pour la traduction, selon ce qu'elles comparent et ce dont elles ont besoin.
Les forces et les faiblesses des métriques apprises
En 2021, les métriques apprises classaient les systèmes plus comme les
personnes que les métriques de surface, surtout entre de bons systèmes
(Kocmi et al., 2021 ; Rei et al., 2020). Cet avantage n’est pas acquis : à
la tâche d’évaluation des métriques de 2025, des métriques simples comme
chrF et BERTScore passaient devant la plupart d’entre elles sur des phrases
isolées (Lavie et al., 2025) (see also the Ways of evaluating a translation page, in the Evaluating language technology module) (voir aussi la page Les façons d'évaluer une traduction, dans le module L'évaluation des technologies langagières).
Leurs coûts :
Un score impossible à vérifier. Un comptage BLEU peut être refait à la
main ; la sortie d’un modèle entraîné ne le peut pas, sauf si la métrique
marque les passages erronés.
Les langues. Une métrique apprise ne vaut que pour les langues sur
lesquelles elle a été entraînée : WMT 2025 s’est rabattu sur chrF++ pour
deux langues pour lesquelles la fiabilité de ses métriques principales
n’avait pas été établie (see also the chrF page, in the Evaluating language technology module) (voir aussi la page chrF, dans le module L'évaluation des technologies langagières).
Le réglage sur la métrique. Un système peut produire plusieurs
traductions candidates et garder celle que préfère la métrique
(Figure 9figure 9).
En 2024, le système en tête du classement automatique avait choisi parmi
ses candidates avec COMET, la métrique employée pour ce classement ; les
personnes ne l’ont pas placé en tête pour toutes les paires de langues, un
écart que les organisateurs attribuent, probablement, à un biais de la
métrique (Kocmi et al., 2024b) (see also the Reading a leaderboard page, in the Using LLMs module) (voir aussi la page Lire un classement, dans le module Utiliser les GML).
Figure 9. Le biais de la métrique : un système arrive en tête selon la métrique, mais pas partout selon les personnes.
Sources
Guerreiro, N. M., Rei, R., van Stigt, D., Coheur, L., Colombo, P., & Martins, A. F. T. (2024). xCOMET: Transparent Machine Translation Evaluation through Fine-grained Error Detection. Transactions of the Association for Computational Linguistics, 12, 979–995. https://doi.org/10.1162/tacl_a_00683
Hanna, M., & Bojar, O. (2021). A Fine-Grained Analysis of BERTScore. Proceedings of the Sixth Conference on Machine Translation, 507–517. https://aclanthology.org/2021.wmt-1.59/
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2002). BLEU: a method for automatic evaluation of machine translation. Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL 2002), Philadelphia, 311–318. https://doi.org/10.3115/1073083.1073135
Popović, M. (2015). chrF: character n-gram F-score for automatic MT evaluation. Proceedings of the Tenth Workshop on Statistical Machine Translation (WMT 2015), Lisbon, 392–395. https://doi.org/10.18653/v1/W15-3049
Rei, R., Stewart, C., Farinha, A. C., & Lavie, A. (2020). COMET: A Neural Framework for MT Evaluation. Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP 2020), 2685–2702. https://doi.org/10.18653/v1/2020.emnlp-main.213
Rei, R., Treviso, M., Guerreiro, N. M., Zerva, C., Farinha, A. C., Maroti, C., de Souza, J. G. C., Glushkova, T., Alves, D., Lavie, A., Coheur, L., & Martins, A. F. T. (2022). CometKiwi: IST-Unbabel 2022 Submission for the Quality Estimation Shared Task. Proceedings of the Seventh Conference on Machine Translation (WMT 2022), Abu Dhabi, 634–645. https://doi.org/10.18653/v1/2022.wmt-1.60
Sellam, T., Das, D., & Parikh, A. P. (2020). BLEURT: Learning Robust Metrics for Text Generation. Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics (ACL 2020), 7881–7892. https://doi.org/10.18653/v1/2020.acl-main.704
Zhang, T., Kishore, V., Wu, F., Weinberger, K. Q., & Artzi, Y. (2020). BERTScore: Evaluating Text Generation with BERT. Eighth International Conference on Learning Representations (ICLR 2020). http://arxiv.org/abs/1904.09675
A large language model as judgeUn grand modèle de langue comme juge
the texts: the source, the output to judge and, if there is one, the
reference;
the criteria: what to rate, and on what scale;
the form of the answer: a single score, a list of errors with a
category and a severity as a human annotator would give, or both.
Judges in translation evaluation
The table below sets out three uses of a large language model as judge of
translations, two of them at WMT, the Conference on Machine Translation. The
first, GEMBA, appeared a few months before Zheng et al. (2023) named the
approach.
Method
What the model was asked
Result
GEMBA (Kocmi & Federmann, 2023b)
a score per segment, with or without a reference
the best system-level accuracy on the WMT 2022 data, with GPT-3.5 and larger models only
GEMBA-MQM (Kocmi & Federmann, 2023a)
error spans with category and severity, from a prompt with three examples, without a reference
state-of-the-art system ranking with GPT-4; the authors advise caution, the model being proprietary and changing
WMT 2025 (Kocmi et al., 2025)
GPT-4.1 and Command A: error spans as in ESA (Kocmi et al., 2024a), without a reference
Three uses of a large language model as judge of translations.
A prompt and its variant
The prompt below is one I wrote for an evaluation of English-to-French
translations of medical abstracts, with a reference translation; its variant
works without one. They ask for a score from 0 to 100 and for a short list of errors
with a category and a severity, which is the shape of the human
protocols (see also the Human evaluation: DA, MQM and ESA page, in the Evaluating language technology module) (voir aussi la page L'évaluation humaine : DA, MQM et ESA, dans le module L'évaluation des technologies langagières). The
placeholders in square brackets are replaced by the texts.
You are an impartial MQM rater for English>French (Canada) translations of medical abstracts.# Task- Read the English source (SOURCE_EN), the human reference (REF_FR), and the translation to evaluate (TGT_FR).- Judge quality only. Do not rewrite the translation.# How to rate (basics)- General score: 0–100 • 0 = broken/poor • 33 = flawed with significant issues • 66 = good with only minor issues • 100 = perfect in meaning and grammar- Error categories: Accuracy, Fluency, Terminology, Punctuation, Numbers/Units, Named entities, Style, Other.- Severity levels: minor, major, critical (critical if meaning changes in safety-relevant content like dosage, units, indications, contraindications).# What to output1) Overall judgment: score 0–100 + one short sentence of justification.2) Errors (keep concise; up to 5): for each, give [Category] – [Severity] – [ERROR] - very short note.# InputsSOURCE_EN:[ADD SOURCE]REF_FR:[ADD REFERENCE]TGT_FR:[ADD TRANSLATION]
The version without a reference drops the reference and tells the model what
to judge the output against instead:
- Read the English source (SOURCE_EN) and the translation to evaluate (TGT_FR). No reference is provided.- Judge adequacy against the source and fluency in the target language. Do not rewrite the translation.
No reference is needed. The judge reads the source, so a text with no
reference translation can be scored. The score then depends on the model’s
own processing of the source, with no reference to anchor it.
The verdict comes with reasons. The errors are named and located, in
plain language.
The criteria are set in the prompt. It can ask about terminology,
register, a client’s style guide, and any other criterion a scale or a
scheme can express.
The reasons are generated like the rest, so a named error can be no error
at all (see also the Hallucinations chapter, in the Critical issues with LLMs module) (voir aussi le chapitre Les fabulations de l'IA, dans le module Enjeux critiques des GML). A variant of
GEMBA-MQM marked Admission to the monument is 16.50 Euros, a correct
translation from Czech, as a currency error (Kocmi & Federmann, 2023a).
Zheng et al. (2023) found biases in the judgements of the models they
tested: they tended to rate the first answer higher, to rate longer answers
higher and, to some extent, to rate their own answers higher.Measured on the models of 2023 (GPT-4, Claude and others of that year); the biases of today’s models have to be measured again.
A judge used to train a system is no longer independent of it: at WMT
2025, some participants had used the judge of the automatic ranking as a
reward model (Kocmi et al., 2025).
A judge is asked for every error at once. A verification rule names
the failure to look for, so the model only has to check whether it occurs.
The Last Translation Benchmark evaluates this way
(Zouhar et al., 2026): every example comes with rules written by the person
who contributed it, and a model checks each translation against each rule
(Figure 10figure 10).
Figure 10. The same model as judge and as verifier of one translation. After Zouhar et al. (2026); the judge's score is illustrative.
A score that can be read directly. The score of a system is the share
of examples whose translation passes every rule, such as 42 of 100; a
judge’s 87 has no such reading.
Less dependent on the model. Rankings produced with the rules were
stable across the models used to check them, where the rankings of
generic judges and of trained metrics changed with the model chosen; and
the tendency of a model to rate its own output higher, measurable with a
generic judge, was much smaller with the rules (Zouhar et al., 2026).
Writing the rules takes expertise. A verification rule takes a person
who can see where the translation goes wrong. Rules written by models
were mostly too generic, and models that translated with rules they had
written themselves improved only slightly (Zouhar et al.,
2026) (see also the Remaining failures page, in the Machine translation module) (voir aussi la page Les échecs qui subsistent, dans le module Traduction automatique).
Sources
Chen, Y., Benton, J., Radhakrishnan, A., Uesato, J., Denison, C., Schulman, J., et al. (2025b). Reasoning Models Don't Always Say What They Think. arXiv preprint arXiv:2505.05410. https://doi.org/10.48550/arXiv.2505.05410
Fernandes, P., Deutsch, D., Finkelstein, M., Riley, P., Martins, A. F. T., Neubig, G., et al. (2023). The Devil Is in the Errors: Leveraging Large Language Models for Fine-grained Machine Translation Evaluation. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), 1066–1083. https://doi.org/10.18653/v1/2023.wmt-1.100
Kocmi, T., & Federmann, C. (2023a). GEMBA-MQM: Detecting Translation Quality Error Spans with GPT-4. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), 768–775. https://doi.org/10.18653/v1/2023.wmt-1.64
Kocmi, T., & Federmann, C. (2023b). Large Language Models Are State-of-the-Art Evaluators of Translation Quality. Proceedings of the 24th Annual Conference of the European Association for Machine Translation, 193–203. https://aclanthology.org/2023.eamt-1.19/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Kocmi, T., Zouhar, V., Avramidis, E., Grundkiewicz, R., Karpinska, M., Popović, M., et al. (2024a). Error Span Annotation: A Balanced Approach for Human Evaluation of Machine Translation. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1440–1453. https://doi.org/10.18653/v1/2024.wmt-1.131
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24
Turpin, M., Michael, J., Perez, E., & Bowman, S. R. (2023). Language Models Don't Always Say What They Think: Unfaithful Explanations in Chain-of-Thought Prompting. Advances in Neural Information Processing Systems 36 (NeurIPS 2023). https://openreview.net/forum?id=bzs4uPLXvi
les textes : la source, la sortie à juger et, s’il y en a une, la
référence ;
les critères : ce qu’il faut noter, et sur quelle échelle ;
la forme de la réponse : un seul score, une liste d’erreurs avec une
catégorie et une gravité comme les donnerait une annotatrice ou un
annotateur humain, ou les deux.
Les juges dans l’évaluation de la traduction
Le tableau ci-dessous présente trois usages d’un grand modèle de langue
comme juge de traductions, dont deux à WMT, la Conference on Machine
Translation. Le premier, GEMBA, est paru quelques mois avant que Zheng et
al. (2023) ne nomment l’approche.
Méthode
Ce qui était demandé au modèle
Résultat
GEMBA (Kocmi & Federmann, 2023b)
un score par segment, avec ou sans référence
la meilleure exactitude au niveau des systèmes sur les données de WMT 2022, avec GPT-3.5 et des modèles plus grands seulement
GEMBA-MQM (Kocmi & Federmann, 2023a)
des passages erronés avec catégorie et gravité, à partir d’une requête comportant trois exemples, sans référence
un classement des systèmes au niveau de l’état de l’art avec GPT-4 ; les auteurs appellent à la prudence, le modèle étant propriétaire et changeant
WMT 2025 (Kocmi et al., 2025)
GPT-4.1 et Command A : des passages erronés comme dans ESA (Kocmi et al., 2024a), sans référence
Trois usages d'un grand modèle de langue comme juge de traductions.
Une requête et sa variante
La requête ci-dessous est l’une de celles que j’ai rédigées pour une
évaluation de traductions de l’anglais vers le français de résumés
médicaux, avec une traduction de référence ; sa variante fonctionne sans
référence. Elles demandent un score de 0 à 100 et une courte liste
d’erreurs avec une catégorie et une gravité, ce qui est la forme des
protocoles humains (see also the Human evaluation: DA, MQM and ESA page, in the Evaluating language technology module) (voir aussi la page L'évaluation humaine : DA, MQM et ESA, dans le module L'évaluation des technologies langagières). Les
éléments entre crochets sont remplacés par les textes.
You are an impartial MQM rater for English>French (Canada) translations of medical abstracts.# Task- Read the English source (SOURCE_EN), the human reference (REF_FR), and the translation to evaluate (TGT_FR).- Judge quality only. Do not rewrite the translation.# How to rate (basics)- General score: 0–100 • 0 = broken/poor • 33 = flawed with significant issues • 66 = good with only minor issues • 100 = perfect in meaning and grammar- Error categories: Accuracy, Fluency, Terminology, Punctuation, Numbers/Units, Named entities, Style, Other.- Severity levels: minor, major, critical (critical if meaning changes in safety-relevant content like dosage, units, indications, contraindications).# What to output1) Overall judgment: score 0–100 + one short sentence of justification.2) Errors (keep concise; up to 5): for each, give [Category] – [Severity] – [ERROR] - very short note.# InputsSOURCE_EN:[ADD SOURCE]REF_FR:[ADD REFERENCE]TGT_FR:[ADD TRANSLATION]
La version sans référence retire la référence et indique au modèle par
rapport à quoi juger la sortie :
- Read the English source (SOURCE_EN) and the translation to evaluate (TGT_FR). No reference is provided.- Judge adequacy against the source and fluency in the target language. Do not rewrite the translation.
Aucune référence n’est nécessaire. Le juge lit la source, si bien
qu’un texte sans traduction de référence peut être noté. Le score dépend
alors du traitement que le modèle fait de la source, sans référence pour
l’ancrer.
Le verdict s’accompagne de raisons. Les erreurs sont nommées et
situées, en langage courant.
Les critères sont fixés dans la requête. Celle-ci peut porter sur la
terminologie, le registre, le guide de rédaction d’un client et tout autre
critère qu’une échelle ou un système de classement peut exprimer.
Les raisons sont générées comme le reste, si bien qu’une erreur nommée
peut ne pas en être une (see also the Hallucinations chapter, in the Critical issues with LLMs module) (voir aussi le chapitre Les fabulations de l'IA, dans le module Enjeux critiques des GML).
Une variante de GEMBA-MQM a marqué Admission to the monument is 16.50
Euros, une traduction correcte du tchèque, comme une erreur de devise
(Kocmi & Federmann, 2023a).
Zheng et al. (2023) ont relevé des biais dans les jugements des modèles
testés : ils avaient tendance à mieux noter la première réponse, à mieux
noter les réponses longues et, dans une certaine mesure, à mieux noter
leurs propres réponses.Mesuré sur les modèles de 2023 (GPT-4, Claude et d’autres de la même année) ; les biais des modèles actuels sont à mesurer de nouveau.
Un juge qui sert à entraîner un système n’en est plus indépendant : à WMT
2025, certains participants avaient employé le juge du classement
automatique comme modèle de récompense (Kocmi et al., 2025).
On demande à un juge toutes les erreurs à la fois. Une règle de
vérification nomme l’échec à rechercher, si bien que le modèle n’a qu’à
vérifier s’il se produit. Le Last Translation Benchmark évalue de cette
façon (Zouhar et al., 2026) : chaque exemple s’accompagne de règles
rédigées par la personne qui l’a fourni, et un modèle vérifie chaque
traduction par rapport à chaque règle
(Figure 10figure 10).
Figure 10. Le même modèle comme juge et comme vérificateur d'une même traduction. D'après Zouhar et al. (2026) ; le score du juge est donné à titre d'illustration.
Un score qui se lit directement. Le score d’un système est la
proportion d’exemples dont la traduction respecte toutes les règles, par
exemple 42 sur 100 ; le 87 d’un juge n’a pas de lecture de ce genre.
Moins dépendant du modèle. Les classements obtenus avec les règles
étaient stables quel que soit le modèle employé pour les vérifier, alors
que les classements des juges génériques et des métriques entraînées
changeaient avec le modèle choisi ; et la tendance d’un modèle à mieux
noter sa propre sortie, mesurable avec un juge générique, était bien plus
faible avec les règles (Zouhar et al., 2026).
Rédiger les règles demande de l’expertise. Une règle de vérification
demande une personne capable de voir où la traduction se trompe. Les
règles rédigées par des modèles étaient pour la plupart trop générales, et
les modèles qui traduisaient avec des règles rédigées par eux-mêmes ne
s’amélioraient que légèrement (Zouhar et al.,
2026) (see also the Remaining failures page, in the Machine translation module) (voir aussi la page Les échecs qui subsistent, dans le module Traduction automatique).
Sources
Chen, Y., Benton, J., Radhakrishnan, A., Uesato, J., Denison, C., Schulman, J., et al. (2025b). Reasoning Models Don't Always Say What They Think. arXiv preprint arXiv:2505.05410. https://doi.org/10.48550/arXiv.2505.05410
Fernandes, P., Deutsch, D., Finkelstein, M., Riley, P., Martins, A. F. T., Neubig, G., et al. (2023). The Devil Is in the Errors: Leveraging Large Language Models for Fine-grained Machine Translation Evaluation. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), 1066–1083. https://doi.org/10.18653/v1/2023.wmt-1.100
Kocmi, T., & Federmann, C. (2023a). GEMBA-MQM: Detecting Translation Quality Error Spans with GPT-4. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), 768–775. https://doi.org/10.18653/v1/2023.wmt-1.64
Kocmi, T., & Federmann, C. (2023b). Large Language Models Are State-of-the-Art Evaluators of Translation Quality. Proceedings of the 24th Annual Conference of the European Association for Machine Translation, 193–203. https://aclanthology.org/2023.eamt-1.19/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Kocmi, T., Zouhar, V., Avramidis, E., Grundkiewicz, R., Karpinska, M., Popović, M., et al. (2024a). Error Span Annotation: A Balanced Approach for Human Evaluation of Machine Translation. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1440–1453. https://doi.org/10.18653/v1/2024.wmt-1.131
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24
Turpin, M., Michael, J., Perez, E., & Bowman, S. R. (2023). Language Models Don't Always Say What They Think: Unfaithful Explanations in Chain-of-Thought Prompting. Advances in Neural Information Processing Systems 36 (NeurIPS 2023). https://openreview.net/forum?id=bzs4uPLXvi
Zouhar, V., Bafna, N., Choudhary, M., Züfle, M., Rajaee, S., Chen, P., et al. (2026). Last Translation Benchmark. Preprint, arXiv:2609.04173. http://arxiv.org/abs/2609.04173
Human evaluation: DA, MQM and ESAL'évaluation humaine : DA, MQM et ESA
Three levels of detail
The automatic methods of this chapter involve people only indirectly,
through a reference translation or the human judgements a metric was
trained on. Human evaluation is often out of reach because of its
cost, but it remains the best evaluation available, for machine translation
too: WMT keeps it as the final arbiter of its rankings (Kocmi et al., 2025).
People can judge a translation at three levels of detail:
a score per segment, with direct assessment (DA);
the errors located, each marked as minor or major, and a score for the
segment, with Error Span Annotation (ESA);
the errors located and classified, each with a category and a
severity, with Multidimensional Quality Metrics (MQM).
This page takes these three methods as examples; there are many others.
Figure 11figure 11 shows
one translation under the three.
Figure 11. One translation under three human protocols. The scores are illustrative.
In direct assessment, a rater reads a segment and gives it a score on a
scale, for instance from 0 to 100. A rater who knows both languages compares
the translation with the source; a rater who knows only the target language
compares it with a reference translation (Jurafsky & Martin, 2026). Direct
assessment was the human evaluation of WMT from 2016 until ESA replaced it in
2024 (Kocmi et al., 2024a).
Fast and cheap. One score per segment, and the raters need no training
in an error scheme.
Noisy. Raters use the scale differently, so their scores are usually
normalized per rater and outlier raters removed (Jurafsky & Martin, 2026).
The scores vary so much that each system needs many annotations, and the
system rankings were less reliable than with MQM or ESA (Kocmi et al.,
2024a).
No explanation. The score says how good a translation is, not what is
wrong with it.
The annotator reads each segment of the translation in the context of its
whole document, and records up to five errors per segment. For each error,
the annotator
(Figure 12figure 12):
highlights the span, that is, the stretch of text that contains the error;
chooses a category, from the table below;
assigns a severity: major for an actual error of translation or
grammar, minor for a smaller imperfection, neutral for a
subjective remark that does not count as an error (Freitag et al.,
2021).
Figure 12. One sentence annotated in the MQM scheme of Freitag et al. (2021): each error has a span, a category, a severity and a weight.
Category
Errors it covers
Example
Accuracy
an addition, an omission, a mistranslation, untranslated text
the format of addresses, currencies, dates, names, telephone numbers and times
10/13/2026 in a text for French readers
Non-translation
a segment too garbled, or too unrelated to the source, for separate errors to be identified
an output about something else entirely
The error categories of MQM in the version of Freitag et al. (2021), with an example of each.
The scheme also has a category for an error in the source, annotated
separately, and one for any other problem.
From errors to a score
Each error gets a weight according to its severity and its category, and
the weights of a segment are added up: the lower the total, the better the
translation. The segment in the figure has a penalty of 5.1.
Severity
Category
Weight
major
non-translation
25
major
any other
5
minor
punctuation
0.1
minor
any other
1
neutral
any
0
The weights of the MQM scheme of Freitag et al. (2021).
Minor punctuation errors weigh little because they are frequent and easy to
correct automatically (Freitag et al., 2021). Other versions of the
framework differ in two ways:
a critical severity, worse than major, which Freitag et al. (2021)
left out because the line between major and critical depends too much on
context;
a quality score expressed as a percentage, from which the penalties
are subtracted (Lommel et al., 2014); ISO 5060:2024 likewise turns penalty
points into an error score and a quality rating (International
Organization for Standardization, 2024).
Limits of MQM
It depends on the annotators. When professional translators annotated
the output of the systems of a WMT edition with this scheme, their ranking
of the systems differed substantially from the ranking that crowd workers
had produced by rating the same output (Freitag et al., 2021).
It is the most expensive of the three protocols on this page. It takes
time, and it takes experts, who are not available for every language
(Kocmi et al., 2024a).
Terminology checks can penalize valid variation. Automatic measures
of terminological consistency assume that every occurrence of a term
should get the same translation, and an annotator applying the
inconsistency subcategory of MQM can do the same, but translators
sometimes vary their terms on purpose. On English-French scientific texts, systems varied less than
people, and forcing a system to follow a glossary improved accuracy and
consistency but suppressed valid variation (Dahan et al., 2026).
ESA
Error Span Annotation, ESA, keeps most of what MQM gives at a lower cost
(Kocmi et al., 2024a). The annotator marks each error span as minor or major,
without a category, then scores the whole segment from 0 to 100, as in the
last panel of Figure 11figure 11.
Marking the errors first makes the score more consistent than a score given
directly, because the annotator has the errors in view (Kocmi et al., 2024a).
WMT adopted ESA in 2024; in 2025 its annotators, many of them professional
translators or linguists and not experts in this kind of annotation, marked
and scored whole paragraphs (Kocmi et al., 2025).
Choosing a protocol
Direct assessment (a score per segment)
MQM
ESA
The annotator’s task
reads the segment, gives a score
marks every error span, with a category and a severity
marks every error span as minor or major, then gives a score from 0 to 100
The result
a score
the errors, located and classified; a weighted score
the errors located; a score
Annotators
anyone fluent
trained annotators, ideally translators
translators, without MQM training
Cost
lowest
highest: a median of 38 seconds per paragraph against 29 for ESA, and experts paid twice the hourly wage
between the two
Use
a quick ranking, though a noisy one
diagnosis: what is wrong and how often
ranking many systems at a quality close to MQM; WMT’s main protocol since 2024
Three human protocols for translation, compared (Kocmi et al., 2024a).
All three depend on their annotators, so an evaluation reports who
annotated, with what instructions, and how well they agreed with each
other.
Sources
Dahan, N., Peng, Z., Yvon, F., & Bawden, R. (2026). Improving Term Evaluation in Machine Translation: Variation Matters. Proceedings of the 17th Conference of the Association for Machine Translation in the Americas (Research Track). https://aclanthology.org/2026.amta-research.7/
Freitag, M., Foster, G., Grangier, D., Ratnakar, V., Tan, Q., & Macherey, W. (2021). Experts, Errors, and Context: A Large-Scale Study of Human Evaluation for Machine Translation. Transactions of the Association for Computational Linguistics, 9, 1460–1474. https://doi.org/10.1162/tacl_a_00437
International Organization for Standardization (2024). ISO 5060:2024: Translation services — Evaluation of translation output — General guidance. International Organization for Standardization, Geneva. https://www.iso.org/standard/80701.html
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Zouhar, V., Avramidis, E., Grundkiewicz, R., Karpinska, M., Popović, M., et al. (2024a). Error Span Annotation: A Balanced Approach for Human Evaluation of Machine Translation. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1440–1453. https://doi.org/10.18653/v1/2024.wmt-1.131
Läubli, S., Sennrich, R., & Volk, M. (2018). Has machine translation achieved human parity? A case for document-level evaluation. Proceedings of EMNLP 2018, 4791–4796. https://aclanthology.org/D18-1512/
Lommel, A., Uszkoreit, H., & Burchardt, A. (2014). Multidimensional Quality Metrics (MQM): A Framework for Declaring and Describing Translation Quality Metrics. Tradumàtica: tecnologies de la traducció, 12, 455–463. https://doi.org/10.5565/rev/tradumatica.77
Trois niveaux de détail
Les méthodes automatiques de ce chapitre ne font intervenir des personnes
qu’indirectement, par une traduction de référence ou par les jugements
humains sur lesquels une métrique a été entraînée. L’évaluation humaine est
souvent hors de portée à cause de son coût, mais elle reste la meilleure
évaluation disponible, pour la traduction automatique aussi : WMT la garde
comme arbitre final de ses classements (Kocmi et al., 2025). Les personnes
peuvent juger une traduction à trois niveaux de détail :
un score par segment, avec l’évaluation directe (en anglais direct
assessment, DA) ;
les erreurs situées, chacune marquée comme mineure ou majeure, et un
score pour le segment, avec l’annotation des passages erronés (en anglais
Error Span Annotation, ESA) ;
les erreurs situées et classées, chacune avec une catégorie et une
gravité, avec MQM (Multidimensional Quality Metrics).
Cette page prend ces trois méthodes comme exemples ; il en existe beaucoup
d’autres. La Figure 11figure 11
montre une même traduction selon les trois.
Figure 11. Une même traduction selon trois protocoles humains. Les scores sont donnés à titre d'illustration.
Dans l’évaluation directe, un évaluateur lit un segment et lui donne un
score sur une échelle, par exemple de 0 à 100. Un évaluateur qui connaît les
deux langues compare la traduction avec la source ; un évaluateur qui ne
connaît que la langue cible la compare avec une traduction de référence
(Jurafsky & Martin, 2026). L’évaluation directe a été l’évaluation humaine
de WMT de 2016 jusqu’à ce qu’ESA la remplace en 2024 (Kocmi et al., 2024a).
Rapide et peu coûteuse. Un score par segment, et les évaluateurs n’ont
pas besoin d’être formés à un système d’erreurs.
Bruitée. Les évaluateurs n’utilisent pas l’échelle de la même façon :
leurs scores sont donc habituellement normalisés par évaluateur, et les
évaluateurs aberrants sont écartés (Jurafsky & Martin, 2026). Les scores
varient tant que chaque système demande de nombreuses annotations, et les
classements des systèmes étaient moins fiables qu’avec MQM ou ESA (Kocmi
et al., 2024a).
Aucune explication. Le score dit si une traduction est bonne, et non
ce qui ne va pas.
L’annotatrice ou l’annotateur lit chaque segment de la traduction dans le
contexte de tout son document, et note jusqu’à cinq erreurs par segment.
Pour chaque erreur, la personne
(Figure 12figure 12) :
surligne le passage, c’est-à-dire la portion de texte qui contient
l’erreur ;
choisit une catégorie, dans le tableau ci-dessous ;
attribue une gravité : majeure pour une véritable erreur de
traduction ou de grammaire, mineure pour une imperfection plus
légère, neutre pour une remarque subjective qui ne compte pas comme
une erreur (Freitag et al., 2021).
Figure 12. Une phrase annotée selon le système MQM de Freitag et al. (2021) : chaque erreur a un passage, une catégorie, une gravité et un poids.
Catégorie
Erreurs couvertes
Exemple
Exactitude
un ajout, une omission, une erreur de sens, un passage non traduit
contact pour contract
Fluidité
la ponctuation, l’orthographe, la grammaire, le registre, l’incohérence
un point final manquant ; Le client ont rappelé
Terminologie
un terme qui ne convient pas au contexte, ou employé de façon incohérente
le format des adresses, des devises, des dates, des noms, des numéros de téléphone et des heures
10/13/2026 dans un texte destiné à des lecteurs francophones
Non-traduction
un segment trop confus, ou trop éloigné de la source, pour qu’on puisse y relever des erreurs distinctes
une sortie qui parle de tout autre chose
Les catégories d'erreurs de MQM dans la version de Freitag et al. (2021), avec un exemple de chacune.
Le système prévoit aussi une catégorie pour une erreur dans la source,
annotée à part, et une autre pour tout autre problème.
Des erreurs au score
Chaque erreur reçoit un poids selon sa gravité et sa catégorie, et les poids
d’un segment sont additionnés : plus le total est bas, meilleure est la
traduction. Le segment de la figure a une pénalité de 5,1.
Gravité
Catégorie
Poids
majeure
non-traduction
25
majeure
toute autre
5
mineure
ponctuation
0,1
mineure
toute autre
1
neutre
toute catégorie
0
Les poids du système MQM de Freitag et al. (2021).
Les erreurs mineures de ponctuation pèsent peu parce qu’elles sont
fréquentes et faciles à corriger automatiquement (Freitag et al., 2021).
D’autres versions du cadre diffèrent sur deux points :
une gravité critique, plus grave que majeure, que Freitag et al.
(2021) ont écartée parce que la limite entre majeure et critique dépend
trop du contexte ;
un score de qualité exprimé en pourcentage, dont on soustrait les
pénalités (Lommel et al., 2014) ; la norme ISO 5060:2024 transforme elle
aussi les points de pénalité en un score d’erreurs et une note de qualité
(International Organization for Standardization, 2024).
Les limites de MQM
Le résultat dépend des annotateurs. Quand des traducteurs
professionnels ont annoté avec ce système la sortie des systèmes d’une
édition de WMT, leur classement des systèmes différait nettement de celui
que des travailleurs recrutés sur une plateforme de production
participative avaient établi en notant la même sortie (Freitag et al.,
2021).
C’est le plus coûteux des trois protocoles de cette page. Il demande
du temps, et il demande des experts, qui ne sont pas disponibles pour
toutes les langues (Kocmi et al., 2024a).
Les vérifications terminologiques peuvent pénaliser une variation
légitime. Les mesures automatiques de cohérence terminologique supposent
que chaque occurrence d’un terme doit recevoir la même traduction, et une
personne qui applique la sous-catégorie d’incohérence de MQM peut faire de
même, mais il arrive que les traducteurs varient leurs termes à dessein.
Sur des textes scientifiques anglais-français, les systèmes variaient moins
que les personnes, et imposer un glossaire à un système améliorait
l’exactitude et la cohérence, mais supprimait une variation légitime
(Dahan et al., 2026).
ESA
ESA, pour Error Span Annotation, conserve l’essentiel de ce que donne MQM
pour un coût moindre (Kocmi et al., 2024a). L’annotatrice ou l’annotateur
marque chaque passage erroné comme mineur ou majeur, sans catégorie, puis
note le segment entier de 0 à 100, comme dans le dernier panneau de la
Figure 11figure 11.
Marquer d’abord les erreurs rend le score plus cohérent qu’un score donné
directement, parce que la personne a les erreurs sous les yeux (Kocmi et
al., 2024a). WMT a adopté ESA en 2024 ; en 2025, ses annotateurs, dont
beaucoup de traducteurs professionnels ou de linguistes qui n’étaient pas
spécialistes de ce type d’annotation, ont marqué et noté des paragraphes
entiers (Kocmi et al., 2025).
Choisir un protocole
Évaluation directe (un score par segment)
MQM
ESA
La tâche de l’annotateur
lit le segment, donne un score
marque chaque passage erroné, avec une catégorie et une gravité
marque chaque passage erroné comme mineur ou majeur, puis donne un score de 0 à 100
Le résultat
un score
les erreurs, situées et classées ; un score pondéré
les erreurs situées ; un score
Les annotateurs
toute personne qui maîtrise la langue
des annotateurs formés, idéalement des traducteurs
des traducteurs, sans formation à MQM
Le coût
le plus bas
le plus élevé : une médiane de 38 secondes par paragraphe contre 29 pour ESA, et des experts payés deux fois le salaire horaire
entre les deux
L’usage
un classement rapide, mais bruité
le diagnostic : ce qui ne va pas, et à quelle fréquence
classer de nombreux systèmes avec une qualité proche de MQM ; principal protocole de WMT depuis 2024
Trois protocoles humains pour la traduction, comparés (Kocmi et al., 2024a).
Les trois dépendent de leurs annotateurs : une évaluation précise donc qui a
annoté, avec quelles consignes, et dans quelle mesure les annotateurs
s’accordaient entre eux.
Sources
Dahan, N., Peng, Z., Yvon, F., & Bawden, R. (2026). Improving Term Evaluation in Machine Translation: Variation Matters. Proceedings of the 17th Conference of the Association for Machine Translation in the Americas (Research Track). https://aclanthology.org/2026.amta-research.7/
Freitag, M., Foster, G., Grangier, D., Ratnakar, V., Tan, Q., & Macherey, W. (2021). Experts, Errors, and Context: A Large-Scale Study of Human Evaluation for Machine Translation. Transactions of the Association for Computational Linguistics, 9, 1460–1474. https://doi.org/10.1162/tacl_a_00437
International Organization for Standardization (2024). ISO 5060:2024: Translation services — Evaluation of translation output — General guidance. International Organization for Standardization, Geneva. https://www.iso.org/standard/80701.html
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Zouhar, V., Avramidis, E., Grundkiewicz, R., Karpinska, M., Popović, M., et al. (2024a). Error Span Annotation: A Balanced Approach for Human Evaluation of Machine Translation. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1440–1453. https://doi.org/10.18653/v1/2024.wmt-1.131
Läubli, S., Sennrich, R., & Volk, M. (2018). Has machine translation achieved human parity? A case for document-level evaluation. Proceedings of EMNLP 2018, 4791–4796. https://aclanthology.org/D18-1512/
Lommel, A., Uszkoreit, H., & Burchardt, A. (2014). Multidimensional Quality Metrics (MQM): A Framework for Declaring and Describing Translation Quality Metrics. Tradumàtica: tecnologies de la traducció, 12, 455–463. https://doi.org/10.5565/rev/tradumatica.77
Comparing machine and human translationComparer la traduction automatique et la traduction humaine
Human parity
In 2018, Microsoft reported that its system translated Chinese news into
English “at human parity when compared to professional human translations”
(Hassan et al., 2018). Toral et al. (2018) and Läubli et al. (2018, 2020)
re-examined the claim and found that the outcome changed with four factors.
judged as whole documents rather than isolated sentences, the human translations were preferred more clearly
The source texts
on the texts originally written in Chinese, rather than translated into Chinese, the difference was significant and parity was not reached
The human translation
the result depends on how the human translation used for comparison was produced
What changed the outcome when the 2018 claim was re-examined (Toral et al., 2018; Läubli et al., 2018, 2020).
With these taken into account, “the professional human translations
contained significantly fewer errors” (Läubli et al., 2020). The paper ends
with recommendations for any such comparison: professional translators as
raters, whole documents, fluency evaluated as well as adequacy, reference
translations not heavily edited for fluency, and original source texts;
Toral et al. (2018) add human translations made from scratch by experienced
professionals.Measured on the neural systems of 2017 and 2018, for Chinese to English news.
Results since
Meaning against fluency. In a blind evaluation with context, an
English-to-Czech neural system preserved meaning better than
professional-agency translations of news, while the human translations
were still rated more fluent, and most participants of a “Translation
Turing test” struggled to tell the two apart (Popel et al., 2020).Named after Alan Turing’s test, in which a judge tries to tell a machine from a person. Here each participant saw 100 separate sentences, each with its source and a single translation, and said whether a machine or a person had translated it; 15 participants (5 professional translators, 6 MT researchers and 4 others) judged the system’s translations mixed with human ones.
WMT 2024. The human translations were in the winning cluster for 7 of
11 language pairs (Kocmi et al., 2024b).
WMT 2025. Gemini 2.5 Pro was on par with or better than the human
translation in 10 of 16 language pairs, and of the 15 pairs in which a
human translation was ranked, it reached the top group in only 6 (Kocmi et
al., 2025).
The WMT organizers add two caveats to their own results: their human
translations, made by professionals, “are not necessarily free of errors or
undergo the same level of post-editing” as sworn or published translations,
and the ranking “could also reflect the stylistic or lexical preferences of
the annotators” (Kocmi et al., 2025).
Literary translation
Literary translation is a hard case for the comparison, and the results
divide according to who judges and how:
Judgements on fluency favour the machine. Raters who read only the
translations preferred a multi-agent LLM system to the human references
(Wu et al., 2025a), and in blind evaluations, LLM translations were
frequently preferred “particularly in terms of fluency” (Wang et al.,
2026b).
Metrics follow neither the experts nor the readers. Automatic metrics did not correlate
with the experts’ preferences (Thai et al., 2022), and automatic metrics and
LLM judges favoured the machine translations that readers liked less
(Ferstler et al., 2026).
Fluency and expertise
The position of machine translation against human translation has changed
with each generation of systems. A neural system of 2018 was judged less
fluent than human translators even where it preserved meaning better (Popel
et al., 2020), and raters who judged the fluency of the 2017 and 2018 systems
without the source preferred the human translations more clearly than
raters who saw it (Läubli et al., 2020). GPT-3.5 translated whole paragraphs with fewer
mistranslations, grammar errors and stylistic inconsistencies than sentence
by sentence, although critical errors such as omissions remained (Karpinska
& Iyyer, 2023).Tested on literary paragraphs, in 18 language pairs.
In the recent literary comparisons above, LLM translations were preferred
for their fluency. These studies differ in their languages, texts and
raters, so the contrast is a pattern across studies rather than a measured
change.
The better machine translation gets, the less its errors show on the
surface. In rule-based and statistical output, an omission usually came with
a fluency error around it; in neural output, “the fluency is no indicator
that all the source content is being transferred into the target” (Van
Brussel et al., 2018). With recent systems, a rater who reads only the
translation, or who lacks the expertise to weigh it, is therefore likely to
judge mainly on fluency.
With student evaluators and a detailed error scheme, nearly 60 % of the human literary
translations were “misjudged as indistinguishable or inferior to machine
translations”, but evaluations by professionals were more adequate than
those by students (Zhang et al., 2025a); professional translators also ranked
news systems differently from crowd workers, with a clearer preference for
the human translations (Freitag et al., 2021). I know of no study that has
tested directly whether the expertise needed grows as the systems improve. The same question arises
for generated text in general.
Reading a parity claim
A claim that a system translates as well as people, or better, says little
until it is clear:
which human translation it was compared with, by whom, and how
carefully it was checked;
who judged: professional translators or not, with the source or only
the target;
what they saw: isolated sentences or whole documents;
which texts: written in the source language or themselves translated;
what was measured: meaning, fluency, a preference or errors.
Sources
Ferstler, Y., Podoxin, A., Brassington, T., Laperrière, G., Grundkiewicz, R., Meurs, M.-J., et al. (2026). AI translation of literary texts is "fine", but readers still prefer human translations. arXiv preprint arXiv:2606.26040; accepted at Findings of EMNLP 2026. https://doi.org/10.48550/arXiv.2606.26040
Freitag, M., Foster, G., Grangier, D., Ratnakar, V., Tan, Q., & Macherey, W. (2021). Experts, Errors, and Context: A Large-Scale Study of Human Evaluation for Machine Translation. Transactions of the Association for Computational Linguistics, 9, 1460–1474. https://doi.org/10.1162/tacl_a_00437
Hassan, H., Aue, A., Chen, C., Chowdhary, V., Clark, J., Federmann, C., et al. (2018). Achieving Human Parity on Automatic Chinese to English News Translation. arXiv preprint arXiv:1803.05567. https://doi.org/10.48550/arXiv.1803.05567
Karpinska, M., & Iyyer, M. (2023). Large language models effectively leverage document-level context for literary translation, but critical errors persist. Proceedings of the Eighth Conference on Machine Translation (WMT 2023). https://aclanthology.org/2023.wmt-1.41/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Läubli, S., Castilho, S., Neubig, G., Sennrich, R., Shen, Q., & Toral, A. (2020). A Set of Recommendations for Assessing Human–Machine Parity in Language Translation. Journal of Artificial Intelligence Research, 67. https://doi.org/10.1613/jair.1.11371
Läubli, S., Sennrich, R., & Volk, M. (2018). Has machine translation achieved human parity? A case for document-level evaluation. Proceedings of EMNLP 2018, 4791–4796. https://aclanthology.org/D18-1512/
Popel, M., Tomkova, M., Tomek, J., Kaiser, Ł., Uszkoreit, J., Bojar, O., & Žabokrtský, Z. (2020). Transforming machine translation: a deep learning system reaches news translation quality comparable to human professionals. Nature Communications, 11, 4381. https://doi.org/10.1038/s41467-020-18073-9
Thai, K., Karpinska, M., Krishna, K., Ray, B., Inghilleri, M., Wieting, J., & Iyyer, M. (2022). Exploring Document-Level Literary Machine Translation with Parallel Paragraphs from World Literature. Proceedings of EMNLP 2022, 9882–9902. https://doi.org/10.18653/v1/2022.emnlp-main.672
Toral, A., Castilho, S., Hu, K., & Way, A. (2018). Attaining the Unattainable? Reassessing Claims of Human Parity in Neural Machine Translation. Proceedings of the Third Conference on Machine Translation: Research Papers, 113–123. https://doi.org/10.18653/v1/W18-6312
Van Brussel, L., Tezcan, A., & Macken, L. (2018). A fine-grained error analysis of NMT, SMT and RBMT output for English-to-Dutch. Proceedings of LREC 2018. https://aclanthology.org/L18-1600/
Wang, L., Sun, S., Wang, X., Gu, J., & Liu, K. (2026b). Workflow matters: Comparing human translators and multi-agent LLMs in literary translation. Target. International Journal of Translation Studies, 38(3), 422–453. https://doi.org/10.1075/target.25081.wan
Wu, M., Xu, J., Yuan, Y., Haffari, G., Wang, L., Luo, W., & Zhang, K. (2025a). (Perhaps) Beyond Human Translation: Harnessing Multi-Agent Collaboration for Translating Ultra-Long Literary Texts. Transactions of the Association for Computational Linguistics, 13, 901–922. https://doi.org/10.1162/TACL.a.25
Zhang, R., Zhao, W., & Eger, S. (2025a). How Good Are LLMs for Literary Translation, Really? Literary Translation Evaluation with Humans and LLMs. Proceedings of NAACL 2025 (Long Papers), 10961–10988. https://doi.org/10.18653/v1/2025.naacl-long.548
La parité avec l’humain
En 2018, Microsoft a annoncé que son système traduisait des actualités
chinoises vers l’anglais « at human parity when compared to professional
human translations » [ma traduction : « à parité avec l’humain par rapport
à des traductions humaines professionnelles »] (Hassan et al., 2018). Toral
et al. (2018) et Läubli et al. (2018, 2020) ont réexaminé cette affirmation
et constaté que le résultat changeait selon quatre facteurs.
jugées comme des documents entiers plutôt que comme des phrases isolées, les traductions humaines étaient préférées plus nettement
Les textes sources
sur les textes écrits à l’origine en chinois, plutôt que traduits vers le chinois, l’écart était significatif et la parité n’était pas atteinte
La traduction humaine
le résultat dépend de la façon dont la traduction humaine employée pour la comparaison a été produite
Ce qui a changé le résultat quand l'affirmation de 2018 a été réexaminée (Toral et al., 2018 ; Läubli et al., 2018, 2020).
Une fois ces facteurs pris en compte, « the professional human translations
contained significantly fewer errors » [ma traduction : « les traductions
humaines professionnelles contenaient significativement moins d’erreurs »]
(Läubli et al., 2020). L’article se termine par des recommandations pour
toute comparaison de ce genre : des traducteurs professionnels comme
évaluateurs, des documents entiers, une évaluation de la fluidité en plus de
l’adéquation, des traductions de référence qui n’ont pas été fortement
retouchées pour la fluidité, et des textes sources originaux ; Toral et al.
(2018) y ajoutent des traductions humaines faites de zéro par des
professionnels expérimentés.Mesuré sur les systèmes neuronaux de 2017 et 2018, pour des actualités traduites du chinois vers l’anglais.
Les résultats depuis
Le sens contre la fluidité. Dans une évaluation à l’aveugle avec
contexte, un système neuronal de l’anglais vers le tchèque rendait mieux le
sens que des traductions d’actualités faites par des agences
professionnelles, alors que les traductions humaines étaient encore jugées
plus fluides, et la plupart des participants d’un « test de Turing de la
traduction » avaient du mal à distinguer les deux (Popel et al.,
2020).D’après le test d’Alan Turing, où un juge tente de distinguer une machine d’une personne. Ici, chaque participant voyait 100 phrases séparées, chacune avec sa source et une seule traduction, et disait si une machine ou une personne l’avait traduite ; 15 participants (5 traducteurs professionnels, 6 chercheurs en traduction automatique et 4 autres personnes) ont jugé les traductions du système mêlées à des traductions humaines.
WMT 2024. Les traductions humaines figuraient dans le groupe gagnant
pour 7 paires de langues sur 11 (Kocmi et al., 2024b).
WMT 2025. Gemini 2.5 Pro égalait ou dépassait la traduction humaine
pour 10 paires de langues sur 16, et sur les 15 paires pour lesquelles une
traduction humaine a été classée, celle-ci n’a atteint le groupe de tête
que pour 6 (Kocmi et al., 2025).
Les organisateurs de WMT assortissent leurs propres résultats de deux
réserves : leurs traductions humaines, faites par des professionnels, « are
not necessarily free of errors or undergo the same level of post-editing »
[ma traduction : « ne sont pas forcément exemptes d’erreurs ni révisées au
même degré »] que des traductions assermentées ou publiées, et le
classement « could also reflect the stylistic or lexical preferences of the
annotators » [ma traduction : « pourrait aussi refléter les préférences
stylistiques ou lexicales des annotateurs »] (Kocmi et al., 2025).
La traduction littéraire
La traduction littéraire est un cas difficile pour la comparaison, et les
résultats divergent selon qui juge et comment :
Les jugements sur la fluidité avantagent la machine. Des évaluateurs
qui ne lisaient que les traductions préféraient un système de GML à
plusieurs agents aux traductions humaines de référence (Wu et al., 2025a),
et dans des évaluations à l’aveugle, les traductions des GML étaient
souvent préférées « particularly in terms of fluency » [ma traduction :
« en particulier pour la fluidité »] (Wang et al., 2026b).
Les métriques ne suivent ni les experts ni les lecteurs. Les
métriques automatiques n’étaient pas corrélées aux préférences des experts
(Thai et al., 2022), et les métriques automatiques et les GML employés
comme juges favorisaient les traductions automatiques que les lecteurs
aimaient moins (Ferstler et al., 2026).
La fluidité et l’expertise
La position de la traduction automatique par rapport à la traduction
humaine a changé à chaque génération de systèmes. Un système neuronal de
2018 était jugé moins fluide que des traducteurs humains, même là où il
rendait mieux le sens (Popel et al., 2020), et les évaluateurs qui jugeaient
la fluidité des systèmes de 2017 et 2018 sans la source préféraient les
traductions humaines plus nettement que ceux qui la voyaient (Läubli et al.,
2020). GPT-3.5 traduisait des paragraphes entiers avec moins d’erreurs de
sens, de fautes de grammaire et d’incohérences de style que phrase par
phrase, même si des erreurs critiques comme les omissions subsistaient
(Karpinska & Iyyer, 2023).Testé sur des paragraphes littéraires, dans 18 paires de langues.
Dans les comparaisons littéraires récentes présentées plus haut, les
traductions des GML étaient préférées pour leur fluidité. Ces études
diffèrent par leurs langues, leurs textes et leurs évaluateurs : le
contraste est donc une tendance d’une étude à l’autre plutôt qu’un
changement mesuré.
Plus la traduction automatique s’améliore, moins ses erreurs se voient en
surface. Dans la sortie des systèmes à base de règles et des systèmes
statistiques, une omission s’accompagnait d’ordinaire d’une erreur de
fluidité autour d’elle ; dans la sortie neuronale, « the fluency is no
indicator that all the source content is being transferred into the
target » [ma traduction : « la fluidité n’indique pas que tout le contenu
de la source a été transféré dans la cible »] (Van Brussel et al., 2018).
Avec les systèmes récents, un évaluateur qui ne lit que la traduction, ou
qui n’a pas l’expertise pour la juger, risque donc de juger surtout sur la
fluidité.
Avec des évaluateurs étudiants et un système d’erreurs détaillé, près de
60 % des traductions littéraires humaines ont été « misjudged as
indistinguishable or inferior to machine translations » [ma traduction :
« jugées à tort impossibles à distinguer des traductions automatiques, ou
inférieures à celles-ci »], mais les évaluations faites par des
professionnels étaient plus justes que celles des étudiants (Zhang et al.,
2025a) ; des traducteurs professionnels ont aussi classé des systèmes de
traduction d’actualités autrement que des travailleurs recrutés sur une
plateforme de production participative, avec une préférence plus nette pour
les traductions humaines (Freitag et al., 2021). Je ne connais aucune étude
qui ait vérifié directement si l’expertise nécessaire augmente à mesure que
les systèmes s’améliorent. La même question se pose pour les textes générés
en général.
Lire une affirmation de parité
Une affirmation selon laquelle un système traduit aussi bien que des
personnes, ou mieux, ne dit pas grand-chose tant qu’on ne sait pas
clairement :
à quelle traduction humaine il a été comparé, faite par qui, et
vérifiée avec quel soin ;
qui a jugé : des traducteurs professionnels ou non, avec la source ou
seulement le texte cible ;
ce que les évaluateurs ont vu : des phrases isolées ou des documents
entiers ;
quels textes : écrits dans la langue source ou eux-mêmes traduits ;
ce qui a été mesuré : le sens, la fluidité, une préférence ou des
erreurs.
Sources
Ferstler, Y., Podoxin, A., Brassington, T., Laperrière, G., Grundkiewicz, R., Meurs, M.-J., et al. (2026). AI translation of literary texts is "fine", but readers still prefer human translations. arXiv preprint arXiv:2606.26040; accepted at Findings of EMNLP 2026. https://doi.org/10.48550/arXiv.2606.26040
Freitag, M., Foster, G., Grangier, D., Ratnakar, V., Tan, Q., & Macherey, W. (2021). Experts, Errors, and Context: A Large-Scale Study of Human Evaluation for Machine Translation. Transactions of the Association for Computational Linguistics, 9, 1460–1474. https://doi.org/10.1162/tacl_a_00437
Hassan, H., Aue, A., Chen, C., Chowdhary, V., Clark, J., Federmann, C., et al. (2018). Achieving Human Parity on Automatic Chinese to English News Translation. arXiv preprint arXiv:1803.05567. https://doi.org/10.48550/arXiv.1803.05567
Karpinska, M., & Iyyer, M. (2023). Large language models effectively leverage document-level context for literary translation, but critical errors persist. Proceedings of the Eighth Conference on Machine Translation (WMT 2023). https://aclanthology.org/2023.wmt-1.41/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Läubli, S., Castilho, S., Neubig, G., Sennrich, R., Shen, Q., & Toral, A. (2020). A Set of Recommendations for Assessing Human–Machine Parity in Language Translation. Journal of Artificial Intelligence Research, 67. https://doi.org/10.1613/jair.1.11371
Läubli, S., Sennrich, R., & Volk, M. (2018). Has machine translation achieved human parity? A case for document-level evaluation. Proceedings of EMNLP 2018, 4791–4796. https://aclanthology.org/D18-1512/
Popel, M., Tomkova, M., Tomek, J., Kaiser, Ł., Uszkoreit, J., Bojar, O., & Žabokrtský, Z. (2020). Transforming machine translation: a deep learning system reaches news translation quality comparable to human professionals. Nature Communications, 11, 4381. https://doi.org/10.1038/s41467-020-18073-9
Thai, K., Karpinska, M., Krishna, K., Ray, B., Inghilleri, M., Wieting, J., & Iyyer, M. (2022). Exploring Document-Level Literary Machine Translation with Parallel Paragraphs from World Literature. Proceedings of EMNLP 2022, 9882–9902. https://doi.org/10.18653/v1/2022.emnlp-main.672
Toral, A., Castilho, S., Hu, K., & Way, A. (2018). Attaining the Unattainable? Reassessing Claims of Human Parity in Neural Machine Translation. Proceedings of the Third Conference on Machine Translation: Research Papers, 113–123. https://doi.org/10.18653/v1/W18-6312
Van Brussel, L., Tezcan, A., & Macken, L. (2018). A fine-grained error analysis of NMT, SMT and RBMT output for English-to-Dutch. Proceedings of LREC 2018. https://aclanthology.org/L18-1600/
Wang, L., Sun, S., Wang, X., Gu, J., & Liu, K. (2026b). Workflow matters: Comparing human translators and multi-agent LLMs in literary translation. Target. International Journal of Translation Studies, 38(3), 422–453. https://doi.org/10.1075/target.25081.wan
Wu, M., Xu, J., Yuan, Y., Haffari, G., Wang, L., Luo, W., & Zhang, K. (2025a). (Perhaps) Beyond Human Translation: Harnessing Multi-Agent Collaboration for Translating Ultra-Long Literary Texts. Transactions of the Association for Computational Linguistics, 13, 901–922. https://doi.org/10.1162/TACL.a.25
Zhang, R., Zhao, W., & Eger, S. (2025a). How Good Are LLMs for Literary Translation, Really? Literary Translation Evaluation with Humans and LLMs. Proceedings of NAACL 2025 (Long Papers), 10961–10988. https://doi.org/10.18653/v1/2025.naacl-long.548
Reading the scoresLire les scores
Comparing like with like
Scores from different metrics, test sets, references or tools cannot be
compared directly (Figure 13figure 13).
Figure 13. The same output scored by three metrics. The scores are illustrative.
A score depends on
Consequence
the metric
a BLEU of 32 and a chrF of 58 for the same output are not two measurements of one thing, and neither is a percentage of anything
the language pair
some trained metrics, such as COMET and BLEURT, have different ranges of values for different language pairs, so their scores cannot be assumed to share one scale (Kocmi et al., 2021)
two BLEU scores computed with different tools can differ by up to 1.8 points on the same output (Post, 2018)
The things a score depends on.
When all of these are the same, the difference between two scores can be
read, with caution. A small difference may be noise: a BLEU
difference of one or two points corresponded to a real difference in human
judgement only about half the time on the WMT 2019 data Mathur et al.
(2020) re-examined. Resampling the test set shows whether a difference is
significant (Kocmi et al., 2021; Jurafsky & Martin,
2026) (see also the Interpreting a score page, in the Evaluating language technology module) (voir aussi la page Interpréter un score, dans le module L'évaluation des technologies langagières).
Rank of each translation, by reference and metricRang de chaque traduction, par référence et par métrique
Rank 1 is the highest score; equal scores share a rank. Hover over a translation to follow it.Le rang 1 est le meilleur score ; des scores égaux partagent un rang. Survolez une traduction pour la suivre.
The demonstration uses only the simplest metrics, BLEU and chrF, because the
others need a trained model that is much harder to run on a web page. The
lesson is the same for them: a score depends on the reference, for every
metric that compares the output with one, and on the method, since different
metrics can rank the same translations
differently (see also the Ways of evaluating a translation page, in the Evaluating language technology module) (voir aussi la page Les façons d'évaluer une traduction, dans le module L'évaluation des technologies langagières).
No single metric is enough: in one company, relying on BLEU alone held back
improved models and led to bad deployment decisions (Kocmi et al., 2021).
At WMT, an automatic ranking decides which systems people evaluate, and
human evaluation is the final arbiter (Kocmi et al.,
2025) (see also the WMT general translation task page, in the Machine translation module) (voir aussi la page La tâche générale de traduction de WMT, dans le module Traduction automatique). The same division works on a smaller scale: an automatic score for every
system, then a human reading of the leading systems and of the sentences on
which the scores disagree.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Mathur, N., Baldwin, T., & Cohn, T. (2020). Tangled up in BLEU: Reevaluating the Evaluation of Automatic Machine Translation Evaluation Metrics. Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, 4984–4997. https://doi.org/10.18653/v1/2020.acl-main.448
Post, M. (2018). A Call for Clarity in Reporting BLEU Scores. Proceedings of the Third Conference on Machine Translation: Research Papers (WMT 2018), 186–191. https://doi.org/10.18653/v1/W18-6319
Comparer ce qui est comparable
Les scores de métriques, de jeux de test, de références ou d’outils
différents ne peuvent pas être comparés directement
(Figure 13figure 13).
Figure 13. La même sortie notée par trois métriques. Les scores sont donnés à titre d'illustration.
Un score dépend de
Conséquence
la métrique
un BLEU de 32 et un chrF de 58 pour la même sortie ne sont pas deux mesures d’une même chose, et aucun n’est un pourcentage de quoi que ce soit
la paire de langues
certaines métriques entraînées, comme COMET et BLEURT, ont des plages de valeurs différentes selon les paires de langues, si bien qu’on ne peut pas supposer que leurs scores partagent une même échelle (Kocmi et al., 2021)
un jeu de test plus difficile donne des scores plus bas pour un même système ; WMT a rendu ses jeux de test de 2025 plus difficiles à dessein (Kocmi et al., 2025)
deux scores BLEU calculés avec des outils différents peuvent présenter un écart allant jusqu’à 1,8 point sur la même sortie (Post, 2018)
Ce dont dépend un score.
Quand tous ces éléments sont identiques, la différence entre deux scores
peut être lue, avec prudence. Une petite différence peut n’être que du
bruit : une différence BLEU d’un ou deux points ne correspondait à une
différence réelle dans le jugement humain qu’environ une fois sur deux, sur
les données de WMT 2019 que Mathur et al. (2020) ont réexaminées. Un
rééchantillonnage du jeu de test montre si une différence est significative
(Kocmi et al., 2021 ; Jurafsky & Martin,
2026) (see also the Interpreting a score page, in the Evaluating language technology module) (voir aussi la page Interpréter un score, dans le module L'évaluation des technologies langagières).
Rank of each translation, by reference and metricRang de chaque traduction, par référence et par métrique
Rank 1 is the highest score; equal scores share a rank. Hover over a translation to follow it.Le rang 1 est le meilleur score ; des scores égaux partagent un rang. Survolez une traduction pour la suivre.
La démonstration n’emploie que les métriques les plus simples, BLEU et chrF,
parce que les autres demandent un modèle entraîné, beaucoup plus difficile à
faire tourner dans une page Web. La leçon vaut aussi pour elles : un score
dépend de la référence, pour toute métrique qui compare la sortie avec une
référence, et de la méthode, puisque des métriques différentes peuvent
classer les mêmes traductions
différemment (see also the Ways of evaluating a translation page, in the Evaluating language technology module) (voir aussi la page Les façons d'évaluer une traduction, dans le module L'évaluation des technologies langagières).
Aucune métrique ne suffit à elle seule : dans une entreprise, s’en remettre
à BLEU seul a freiné l’adoption de modèles améliorés et conduit à de
mauvaises décisions de déploiement (Kocmi et al., 2021). À WMT, un
classement automatique décide des systèmes que des personnes évaluent, et
l’évaluation humaine est l’arbitre final (Kocmi et al.,
2025) (see also the WMT general translation task page, in the Machine translation module) (voir aussi la page La tâche générale de traduction de WMT, dans le module Traduction automatique). La même
répartition fonctionne à plus petite échelle : un score automatique pour
chaque système, puis une lecture humaine des systèmes de tête et des
phrases sur lesquelles les scores ne concordent pas.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Federmann, C., Grundkiewicz, R., Junczys-Dowmunt, M., Matsushita, H., & Menezes, A. (2021). To Ship or Not to Ship: An Extensive Evaluation of Automatic Metrics for Machine Translation. Proceedings of the Sixth Conference on Machine Translation (WMT 2021), 478–494. https://aclanthology.org/2021.wmt-1.57/
Mathur, N., Baldwin, T., & Cohn, T. (2020). Tangled up in BLEU: Reevaluating the Evaluation of Automatic Machine Translation Evaluation Metrics. Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, 4984–4997. https://doi.org/10.18653/v1/2020.acl-main.448
Post, M. (2018). A Call for Clarity in Reporting BLEU Scores. Proceedings of the Third Conference on Machine Translation: Research Papers (WMT 2018), 186–191. https://doi.org/10.18653/v1/W18-6319
Computing scores with MATEOCalculer des scores avec MATEO
A tool that computes metrics
MATEO, for MAchine Translation Evaluation Online, is a web interface that
computes the main automatic metrics for machine translation without any
programming, built for students, translators and researchers in the
humanities as well as for experts (Vanroy et al., 2023).
Each score MATEO shows comes from one of the metrics you select, such as
chrF or COMET, with that metric’s own
scale (see also the Reading the scores page, in the Evaluating language technology module) (voir aussi la page Lire les scores, dans le module L'évaluation des technologies langagières). MATEO
does not store the files you upload: they are processed in memory and
removed once the processing is done.As stated on MATEO’s home page, read on 13 October 2026.
Preparing the files
MATEO compares the files line by line: line 1 of a translation is scored
against line 1 of the reference, and so on. Each file must be:
MATEO checks the files as they are uploaded. When a file is missing, or has
a different number of lines from the reference, a message under the upload
boxes says so, and the button that starts the evaluation does not appear
until the problem is solved
(Figure 14figure 14).
In that message, Reference file #1 is the first system file.
Figure 14. MATEO's message when a system file has a different number of lines from the reference.
Running an evaluation
On the Evaluate page of MATEO:
Choose the metrics under Metric selection
(Figure 15figure 15). BLEU, chrF and
COMET are ticked by default; BERTScore, BLEURT and TER are not. Each
metric has a panel of options; the default options are the usual
settings.
Upload the files under Input data
(Figure 16figure 16): the reference in
Reference file, the source in Source file, and each translation in a
System box. Set How many systems do you wish to compare? first, to get
one box per system; the first system is marked as the baseline. Each file
is dragged onto its box or chosen with Browse files; text cannot be
pasted.
Click Evaluate MT. The button appears once the files listed under
the boxes are in place: a reference, at least one system, and a source if
COMET is selected.
Figure 15. Choosing the metrics: chrF and COMET ticked, with their default options. Figure 16. Uploading the files: a reference, a source and two systems, the first of which serves as the baseline.
When the evaluation shown here was run on six sentences with chrF, BLEU and
COMET on 13 October 2026, the results appeared within a few seconds. The site is shared,
so a longer text, or many people using it at the same time, takes longer.
Reading the results
The whole text
Under Evaluation results (corpus), MATEO gives a bar plot and a radar plot
of the scores (Figure 17figure 17), which can
be downloaded with the camera icon that appears when the pointer is over
them, and a table with one row per system and one column per metric
(Figure 18figure 18). In the captures,
system-a is a translation worded differently from the reference, and
system-b a literal translation with several errors.
Figure 17. The bar plot of the scores for the whole text, one group of bars per metric.
In the table, each cell gives:
the score of the metric for the whole text, before the brackets. This
is the number to report.
in brackets, a mean and a 95 % confidence interval, computed by drawing
1,000 resampled versions of the text: a range in which the score would
probably fall with other sentences of the same kind. It can be left aside
for a first comparison.
for every system but the first, a p-value, with an asterisk when the
system differs significantly from the first one, which MATEO calls the
baseline and highlights. The order in which the systems are uploaded
therefore decides which system the others are tested against.
The best score of each metric is in bold. The table can be downloaded with or
without the confidence intervals and p-values, as an Excel file or a
tab-separated file. Under the table, the Signatures line records the
settings of each metric, the information another person needs to compute
the same scores.
Figure 18. The table for the whole text, with the download links, the signatures and a LaTeX version under it.
In these results, system-b, the literal translation with errors, has the
higher chrF, by a significant margin, because it keeps more of the
reference’s character sequences. The COMET difference between the two systems is small
and not significant.
COMET appears in MATEO on a scale up to 100, which makes it look like a
percentage. It is not one, and neither is any other score in the table.
Sentence by sentence
Under Evaluation results (sentences), MATEO gives a plot with one point per
sentence and per system (Figure 19figure 19),
and a table with the source and the reference of every sentence, followed by
each system’s translation and its score, in a column named after the system
(Figure 20figure 20). The table scrolls
sideways to show the systems, and it can be downloaded as an Excel file,
with one sheet per metric.
These scores exist only for metrics whose score for the whole text is the
mean of their scores per sentence, such as COMET. BLEU and chrF are computed
over the whole text at once, so MATEO gives them no score per sentence, as
its note About sentence-level scores explains.
Figure 19. The note on scores per sentence, and the COMET score of each sentence for the two systems. Figure 20. The start of the table per sentence: the source and the reference, with the systems' translations and scores further to the right.
Name the metric and the tool. For instance: “COMET 91.9 (model
Unbabel/wmt22-comet-da, COMET 2.2.6), computed with MATEO 1.8.4”, with the
Signatures line in a note. The same metric with other settings or another
version gives another score (see also the BLEU page, in the Evaluating language technology module) (voir aussi la page BLEU, dans le module L'évaluation des technologies langagières).
The metric is BERTScore, not BERT, which is one of the models BERTScore can
use.
Keep “significant” for the test. A difference is significant in the
statistical sense only when the test says so, and a small difference may
be noise.
Describe what the metric does. A metric counts shared words or characters,
compares vectors or predicts a human score; it does not understand the
translation.
Running MATEO once
Sources
Vanroy, B., Tezcan, A., & Macken, L. (2023). MATEO: MAchine Translation Evaluation Online. Proceedings of the 24th Annual Conference of the European Association for Machine Translation (EAMT 2023), Tampere, 499–500. https://aclanthology.org/2023.eamt-1.52/
Un outil qui calcule des métriques
MATEO, pour MAchine Translation Evaluation Online, est une interface Web
qui calcule les principales métriques automatiques de la traduction
automatique sans aucune programmation, conçue pour les étudiants, les
traducteurs et les chercheurs en sciences humaines autant que pour les
spécialistes (Vanroy et al., 2023).
Chaque score que montre MATEO vient de l’une des métriques que vous
sélectionnez, comme chrF ou COMET, avec l’échelle propre à cette
métrique (see also the Reading the scores page, in the Evaluating language technology module) (voir aussi la page Lire les scores, dans le module L'évaluation des technologies langagières). MATEO
ne conserve pas les fichiers que vous téléversez : ils sont traités en
mémoire et supprimés une fois le traitement terminé.Selon la page d’accueil de MATEO, consultée le 13 octobre 2026.
Préparer les fichiers
MATEO compare les fichiers ligne par ligne : la ligne 1 d’une traduction
est notée par rapport à la ligne 1 de la référence, et ainsi de suite.
Chaque fichier doit être :
MATEO vérifie les fichiers au moment du téléversement. Quand un fichier
manque, ou qu’il n’a pas le même nombre de lignes que la référence, un
message sous les zones de téléversement le signale, et le bouton qui lance
l’évaluation n’apparaît pas tant que le problème n’est pas réglé
(Figure 14figure 14).
Dans ce message, Reference file #1 désigne le premier fichier de système.
Figure 14. Le message de MATEO quand un fichier de système n'a pas le même nombre de lignes que la référence.
Lancer une évaluation
Sur la page Evaluate de MATEO :
Choisissez les métriques sous Metric selection
(Figure 15figure 15).
BLEU, chrF et COMET sont cochées par défaut ; BERTScore, BLEURT et TER
ne le sont pas. Chaque métrique a un panneau d’options ; les options par
défaut correspondent aux réglages habituels.
Téléversez les fichiers sous Input data
(Figure 16figure 16) :
la référence dans Reference file, la source dans Source file, et
chaque traduction dans une zone System. Réglez d’abord How many
systems do you wish to compare?, pour obtenir une zone par système ; le
premier système est marqué comme système de comparaison, que MATEO
appelle baseline. Chaque fichier est glissé sur sa zone ou choisi avec
Browse files ; il n’est pas possible de coller du texte.
Cliquez sur Evaluate MT. Le bouton apparaît une fois que les
fichiers indiqués sous les zones sont en place : une référence, au moins
un système, et une source si COMET est sélectionnée.
Figure 15. Le choix des métriques : chrF et COMET cochées, avec leurs options par défaut. Figure 16. Le téléversement des fichiers : une référence, une source et deux systèmes, dont le premier sert de système de comparaison.
Quand l’évaluation présentée ici a été lancée sur six phrases avec chrF,
BLEU et COMET le 13 octobre 2026, les résultats sont apparus en quelques
secondes. Le site est partagé : un texte plus long, ou de nombreuses
personnes qui l’emploient en même temps, demande plus de temps.
Lire les résultats
Le texte entier
Sous Evaluation results (corpus), MATEO donne un diagramme à barres et un
diagramme en radar des scores
(Figure 17figure 17),
qui peuvent être téléchargés avec l’icône d’appareil photo qui apparaît
quand le pointeur les survole, ainsi qu’un tableau avec une ligne par
système et une colonne par métrique
(Figure 18figure 18).
Dans les captures, system-a est une traduction formulée autrement que la
référence, et system-b une traduction littérale qui comporte plusieurs
erreurs.
Figure 17. Le diagramme à barres des scores pour tout le texte, un groupe de barres par métrique.
Dans le tableau, chaque case donne :
le score de la métrique pour tout le texte, avant les parenthèses.
C’est le nombre à présenter.
entre parenthèses, une moyenne et un intervalle de confiance à 95 %,
calculés en tirant 1 000 versions rééchantillonnées du texte : une plage
dans laquelle le score tomberait probablement avec d’autres phrases du
même genre. Il peut être laissé de côté pour une première comparaison.
pour chaque système sauf le premier, une valeur p, avec un astérisque
quand le système diffère significativement du premier, que MATEO appelle
baseline et met en évidence. L’ordre dans lequel les systèmes sont
téléversés décide donc du système auquel les autres sont comparés.
Le meilleur score de chaque métrique est en gras. Le tableau peut être
téléchargé avec ou sans les intervalles de confiance et les valeurs p, en
fichier Excel ou en fichier à valeurs séparées par des tabulations. Sous le
tableau, la ligne Signatures consigne les réglages de chaque métrique,
l’information dont une autre personne a besoin pour calculer les mêmes
scores.
Figure 18. Le tableau pour tout le texte, avec les liens de téléchargement, les signatures et une version LaTeX au-dessous.
Dans ces résultats, system-b, la traduction littérale qui comporte des
erreurs, a le chrF le plus élevé, avec un écart significatif, parce qu’elle
reprend davantage de suites de caractères de la référence. L’écart de COMET
entre les deux systèmes est faible et non significatif.
COMET apparaît dans MATEO sur une échelle allant jusqu’à 100, ce qui le fait
ressembler à un pourcentage. Ce n’en est pas un, pas plus qu’aucun autre
score du tableau.
Phrase par phrase
Sous Evaluation results (sentences), MATEO donne un graphique avec un
point par phrase et par système
(Figure 19figure 19),
et un tableau avec la source et la référence de chaque phrase, suivies de la
traduction de chaque système et de son score, dans une colonne qui porte le
nom du système
(Figure 20figure 20).
Le tableau défile horizontalement pour montrer les systèmes, et il peut être
téléchargé en fichier Excel, avec une feuille par métrique.
Ces scores n’existent que pour les métriques dont le score pour tout le
texte est la moyenne de leurs scores par phrase, comme COMET. BLEU et chrF
sont calculés sur tout le texte d’un coup : MATEO ne leur donne donc pas de
score par phrase, comme l’explique sa note About sentence-level scores.
Figure 19. La note sur les scores par phrase, et le score COMET de chaque phrase pour les deux systèmes. Figure 20. Le début du tableau par phrase : la source et la référence, avec les traductions et les scores des systèmes plus à droite.
Nommez la métrique et l’outil. Par exemple : « COMET 91,9 (modèle
Unbabel/wmt22-comet-da, COMET 2.2.6), calculé avec MATEO 1.8.4 », avec la
ligne Signatures en note. La même métrique avec d’autres réglages ou
une autre version donne un autre
score (see also the BLEU page, in the Evaluating language technology module) (voir aussi la page BLEU, dans le module L'évaluation des technologies langagières). La métrique est
BERTScore, et non BERT, qui n’est que l’un des modèles que BERTScore peut
employer.
Réservez « significatif » au test. Une différence n’est significative
au sens statistique que si le test le dit, et une petite différence peut
n’être que du bruit.
Décrivez ce que fait la métrique. Une métrique compte des mots ou des
caractères partagés, compare des vecteurs ou prédit un score humain ; elle
ne comprend pas la traduction.
Essayer MATEO une fois
Sources
Vanroy, B., Tezcan, A., & Macken, L. (2023). MATEO: MAchine Translation Evaluation Online. Proceedings of the 24th Annual Conference of the European Association for Machine Translation (EAMT 2023), Tampere, 499–500. https://aclanthology.org/2023.eamt-1.52/
The WMT shared taskLa tâche partagée WMT
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
The WMT general translation taskLa tâche générale de traduction de WMT
A shared task
Two systems tested by their own developers are hard to compare, since each
is tested on texts and with a measure the developer chose. A shared task
gives every system the same test.
For machine translation, the best-known shared task is WMT, the Conference
on Machine Translation, which has run a general translation task every year
since 2006, first as a workshop and since 2016 as a conference (Kocmi et al.,
2025). Each year follows the same cycle
(Figure 1figure 1):
the organizers prepare test texts that nobody has seen;
the participants translate them with their systems and submit the output
by a deadline;
the organizers have the output judged;
the results appear together in a findings paper, and the data are
released so that the evaluation can be checked and reused.
Figure 1. One year of the WMT general translation task.
A recent edition covers a few dozen language pairs, about half of them with
human evaluation. The test sets of the 2024 and 2025 editions were built
this way (Kocmi et al., 2024b, 2025):
Several domains. News, social media, speech and literary texts in both
editions, with educational texts added in 2025, chosen to cover different
styles while staying readable by annotators without specialist knowledge.
For the speech domain, participants receive the audio and an automatic
transcription; in 2025 they also received screenshots of the social media
posts.
Whole documents. Since 2024, each source text is an entire document,
such as a news article or a social media thread, divided into paragraphs.
Participants can translate it at once or piece by piece, and each
translation is judged in its context.
Difficult documents. New in 2025: an automatic estimator of
translation difficulty scores every paragraph from the source alone, the
scores are aggregated by document, and the hardest documents are kept.
the other systems, proprietary models and private data included, form a
track of their own: the unconstrained track in 2025, split in 2024 into
an open track (public data and models) and a closed one (Kocmi et al.,
2024b, 2025).
In 2025, a multilingual subtrack, evaluated automatically only, tested
one system translating from English into many languages at once.
Several dozen systems are too many to judge by hand, so since 2024 the
judging happens in two stages (Figure 2figure 2; Kocmi et al., 2024b, 2025).
Figure 2. The two stages of judging at WMT 2025: an automatic ranking of every system, then human evaluation of the leading ones.
Automatic ranking. Automatic methods score every system, and the
scores are combined into one ranking per language pair, which the
organizers call AutoRank and use to choose which systems go to human
evaluation. In 2024 AutoRank combined two metrics trained on human
judgements, one that compares the output with the reference and one that
works without it; in 2025 it combined two large language models prompted
to act as judges, two trained metrics that compare with the reference, and
one that works without it.
Human evaluation. Annotators who are native speakers of the target
language, many of them professional translators or linguists, judge the
output with the Error Span Annotation protocol: they mark every error in a
paragraph as minor or major, then give the paragraph a score from 0 to 100
(Kocmi et al., 2024a). In 2025, two language pairs were judged with the
finer MQM scheme
instead (see also the Human evaluation: DA, MQM and ESA page, in the Evaluating language technology module) (voir aussi la page L'évaluation humaine : DA, MQM et ESA, dans le module L'évaluation des technologies langagières). Systems
whose human scores cannot be told apart statistically are placed in one
cluster, and the systems of the first cluster are the winners of a
language pair.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Kocmi, T., Zouhar, V., Avramidis, E., Grundkiewicz, R., Karpinska, M., Popović, M., et al. (2024a). Error Span Annotation: A Balanced Approach for Human Evaluation of Machine Translation. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1440–1453. https://doi.org/10.18653/v1/2024.wmt-1.131
Une tâche partagée
Deux systèmes testés par leurs propres développeurs se comparent mal,
puisque chacun est testé sur des textes et avec une mesure que son
développeur a choisis. Une tâche partagée soumet tous les systèmes au même
test.
En traduction automatique, la tâche partagée la plus connue est celle de
WMT, la Conference on Machine Translation, qui organise chaque année depuis
2006 une tâche générale de traduction, d’abord sous forme d’atelier, puis,
depuis 2016, de conférence (Kocmi et al., 2025). Chaque année suit le même
cycle (Figure 1figure 1) :
les organisateurs préparent des textes de test que personne n’a vus ;
les participants les traduisent avec leurs systèmes et soumettent les
résultats avant une échéance ;
les organisateurs font juger les résultats ;
les résultats paraissent ensemble dans un article de synthèse, et les
données sont publiées pour que l’évaluation puisse être vérifiée et
réutilisée.
Figure 1. Une année de la tâche générale de traduction de WMT.
Une édition récente couvre quelques dizaines de paires de langues, dont
environ la moitié font l’objet d’une évaluation humaine. Les jeux de test des
éditions 2024 et 2025 ont été constitués ainsi (Kocmi et al., 2024b, 2025) :
Plusieurs domaines. Des textes journalistiques, des médias sociaux, de
la parole et des textes littéraires dans les deux éditions, auxquels
s’ajoutent des textes pédagogiques en 2025, choisis pour couvrir des styles
différents tout en restant lisibles par des annotateurs sans connaissances
spécialisées. Pour le domaine de la parole, les participants reçoivent
l’audio et une transcription automatique ; en 2025, ils ont aussi reçu des
captures d’écran des publications des médias sociaux.
Des documents entiers. Depuis 2024, chaque texte source est un
document entier, par exemple un article de presse ou un fil de discussion
sur un média social, découpé en paragraphes. Les participants peuvent le
traduire d’un seul tenant ou morceau par morceau, et chaque traduction est
jugée dans son contexte.
Des documents difficiles. Nouveauté de 2025 : un estimateur
automatique de la difficulté de traduction note chaque paragraphe à partir
de la source seule, les notes sont regroupées par document, et les
documents les plus difficiles sont retenus.
les autres systèmes, modèles propriétaires et données privées compris,
forment une catégorie à part : la catégorie non contrainte en 2025,
divisée en 2024 en une catégorie ouverte (données et modèles publics) et
une catégorie fermée (Kocmi et al., 2024b, 2025).
En 2025, une sous-catégorie multilingue, évaluée automatiquement
seulement, testait un système unique qui traduit de l’anglais vers de
nombreuses langues à la fois.
Plusieurs dizaines de systèmes, c’est trop pour un jugement manuel ; depuis
2024, le jugement se fait donc en deux étapes (Figure 2figure 2 ; Kocmi et al., 2024b, 2025).
Figure 2. Les deux étapes du jugement à WMT 2025 : un classement automatique de tous les systèmes, puis une évaluation humaine des systèmes en tête.
Classement automatique. Des méthodes automatiques notent chaque
système, et les notes sont combinées en un classement par paire de
langues, que les organisateurs appellent AutoRank et qui sert à choisir
les systèmes soumis à l’évaluation humaine. En 2024, AutoRank combinait
deux métriques entraînées sur des jugements humains, l’une qui compare le
résultat à la référence et l’autre qui s’en passe ; en 2025, il combinait
deux grands modèles de langue utilisés comme juges, deux métriques
entraînées qui comparent le résultat à la référence et une qui s’en passe.
Évaluation humaine. Des annotateurs dont la langue maternelle est la
langue cible, pour beaucoup des traducteurs professionnels ou des
linguistes, jugent les résultats selon le protocole Error Span
Annotation : ils classent chaque erreur d’un paragraphe comme mineure ou
majeure, puis attribuent au paragraphe une note de 0 à 100 (Kocmi et al.,
2024a). En 2025, deux paires de langues ont été jugées avec la grille MQM,
plus fine (see also the Human evaluation: DA, MQM and ESA page, in the Evaluating language technology module) (voir aussi la page L'évaluation humaine : DA, MQM et ESA, dans le module L'évaluation des technologies langagières). Les
systèmes dont les notes humaines ne se distinguent pas statistiquement
sont placés dans un même groupe, et les systèmes du premier groupe sont
les gagnants d’une paire de langues.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Kocmi, T., Zouhar, V., Avramidis, E., Grundkiewicz, R., Karpinska, M., Popović, M., et al. (2024a). Error Span Annotation: A Balanced Approach for Human Evaluation of Machine Translation. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1440–1453. https://doi.org/10.18653/v1/2024.wmt-1.131
The trend across editionsLa tendance d'une édition à l'autre
documents selected for difficulty; large language models used as judges in the automatic ranking
The last three editions of the general translation task, and the change each made (Kocmi et al., 2023, 2024b, 2025).
The subtitles alone show how quickly large language models changed the
task. In 2023 they were among the systems for the first time; by 2024 the
organizers spoke of an “LLM era”; and in 2025 the best systems did so well
on ordinary texts that the test sets had to be made harder to tell them
apart.
The 2026 edition takes place on 28 October 2026 and 29 October 2026.WMT 2026, www2.statmt.org/wmt26, read 10 October 2026: eleventh Conference on Machine Translation, Budapest, with EMNLP 2026.
Automatic scores and human judges disagree about the best system. In
both 2024 and 2025 the system that led the automatic ranking was not the
one people preferred, and in 2024 the organizers traced the gap to a system
that had chosen its output with the very metric used to rank it. Their
conclusion is that human evaluation remains the final
arbiter (see also the Reading the scores page, in the Evaluating language technology module) (voir aussi la page Lire les scores, dans le module L'évaluation des technologies langagières).
Human translations are not always preferred. From 2023 on, the output
of the best systems could often not be told apart from the human reference,
and in 2025 the references were in the winning group for fewer than half of
the language pairs. The papers themselves add cautions: the
references are produced by agencies under a brief and vary in quality, and
an evaluation that marks errors can give a high score to a translation that
is free of errors but does not capture the author’s voice.
Adelani, D. I., Agostinelli, V., Anastasopoulos, A., Bentivogli, L., Bojar, O., et al. (2026). Speech translation and metrics in 2026: Findings of the IWSLT campaign. Proceedings of the 23rd International Conference on Spoken Language Translation (IWSLT 2026), 336–422. https://aclanthology.org/2026.iwslt-1.39/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2023). Findings of the 2023 Conference on Machine Translation (WMT23): LLMs Are Here but Not Quite There Yet. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), Singapore, 1–42. https://doi.org/10.18653/v1/2023.wmt-1.1
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24
des documents choisis pour leur difficulté ; des grands modèles de langue utilisés comme juges dans le classement automatique
Les trois dernières éditions de la tâche générale de traduction, et le changement apporté par chacune (Kocmi et al., 2023, 2024b, 2025).
Les sous-titres suffisent à montrer à quelle vitesse les grands modèles de
langue ont transformé la tâche. En 2023, ils figuraient pour la première fois
parmi les systèmes ; en 2024, les organisateurs annonçaient l’ère des GML ;
et en 2025, les meilleurs systèmes réussissaient si bien sur des textes
ordinaires qu’il a fallu rendre les jeux de test plus difficiles pour les
départager.
L’édition 2026 se tient le 28 octobre 2026 et le 29 octobre 2026.WMT 2026, www2.statmt.org/wmt26, consulté le 10 octobre 2026 : onzième Conference on Machine Translation, à Budapest, avec EMNLP 2026.
Les notes automatiques et les juges humains divergent sur le meilleur
système. En 2024 comme en 2025, le système en tête du classement
automatique n’était pas celui que les personnes préféraient, et en 2024 les
organisateurs ont attribué l’écart à un système qui avait choisi ses
résultats à l’aide de la métrique même qui servait à le classer. Leur
conclusion est que l’évaluation humaine reste l’arbitre
final (see also the Reading the scores page, in the Evaluating language technology module) (voir aussi la page Lire les scores, dans le module L'évaluation des technologies langagières).
Les traductions humaines ne sont pas toujours préférées. À partir de
2023, les résultats des meilleurs systèmes ne pouvaient souvent pas être
distingués de la référence humaine, et en 2025 les références figuraient
dans le groupe gagnant pour moins de la moitié des paires de langues. Les
articles eux-mêmes apportent des mises en garde : les références sont
produites par des agences selon une consigne et sont de qualité variable,
et une évaluation qui relève les erreurs peut donner une note élevée à une
traduction exempte d’erreurs, mais qui ne rend pas la voix de l’auteur.
terminologie ; langues indiennes, langues créoles, paires arabe-langues asiatiques et chinois-langues d’Asie du Sud-Est ; sous-titres de vidéos ; compression de modèles
des systèmes sur un domaine, un groupe de langues ou une contrainte, là où la tâche générale en dit peu
L’évaluation
évaluation automatisée de la traduction automatique (les anciennes tâches des métriques et de l’estimation de la qualité, réunies en 2025) ; séries de tests ciblées
les évaluateurs eux-mêmes : à quel point une métrique ou un juge s’accorde avec les personnes, et ce que révèlent des jeux de test ciblés
Les données et les modèles
données ouvertes ; instructions multilingues ; modèles de langue à ressources limitées
les ressources et les modèles plus petits sur lesquels le domaine s’appuie
Les types de tâches partagées que WMT organise à côté de la tâche générale de traduction (éditions 2025 et 2026).
Adelani, D. I., Agostinelli, V., Anastasopoulos, A., Bentivogli, L., Bojar, O., et al. (2026). Speech translation and metrics in 2026: Findings of the IWSLT campaign. Proceedings of the 23rd International Conference on Spoken Language Translation (IWSLT 2026), 336–422. https://aclanthology.org/2026.iwslt-1.39/
Kocmi, T., Artemova, E., Avramidis, E., Bawden, R., Bojar, O., Dranch, K., et al. (2025). Findings of the WMT25 General Machine Translation Shared Task: Time to Stop Evaluating on Easy Test Sets. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 355–413. https://doi.org/10.18653/v1/2025.wmt-1.22
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2023). Findings of the 2023 Conference on Machine Translation (WMT23): LLMs Are Here but Not Quite There Yet. Proceedings of the Eighth Conference on Machine Translation (WMT 2023), Singapore, 1–42. https://doi.org/10.18653/v1/2023.wmt-1.1
Kocmi, T., Avramidis, E., Bawden, R., Bojar, O., Dvorkovich, A., Federmann, C., et al. (2024b). Findings of the WMT24 General Machine Translation Shared Task: The LLM Era Is Here but MT Is Not Solved Yet. Proceedings of the Ninth Conference on Machine Translation (WMT 2024), 1–46. https://doi.org/10.18653/v1/2024.wmt-1.1
Lavie, A., Hanneman, G., Agrawal, S., Kanojia, D., Lo, C., Zouhar, V., et al. (2025). Findings of the WMT25 Shared Task on Automated Translation Evaluation Systems: Linguistic Diversity is Challenging and References Still Help. Proceedings of the Tenth Conference on Machine Translation (WMT 2025), Volume 2: Shared Task Papers, 436–483. https://doi.org/10.18653/v1/2025.wmt-1.24