PrintedImprimé le·aylart.github.io/learn·
CC BY-NC 4.0
Why language is hardPourquoi le langage est difficile
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
What computers computeCe que les ordinateurs calculent
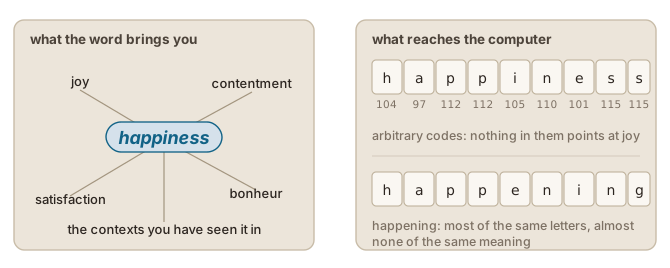
When you read the word happiness, you may think of many things. You may think
of related words, like joy or contentment. You may think about the
translation in another language, like bonheur or geluk. You may think about
a different form of the word: happy. Depending on your musical preferences,
you may think of a song by Taylor Swift, Pharrell Williams, or “if you’re happy
and you know it clap your hands”.
When a computer program “reads” the word happiness, it only gets a series of
bits: the numbers associated to the characters of that exact word. The only
easy connections to compute would be to other sequences of similar bits. For
instance, the word happening has many of the same letters and exactly the
same length.
Figure 1. What the word brings a reader, and what reaches the computer. The codes point at nothing, and they separate happiness from happening by two characters.
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
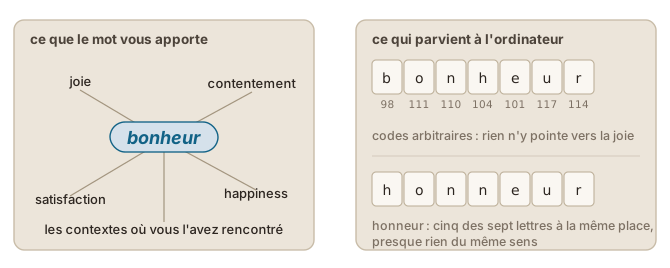
Quand vous lisez le mot bonheur, vous pouvez penser à bien des choses. Vous
pouvez penser à des mots apparentés, comme joie ou contentement. Vous
pouvez penser à sa traduction dans une autre langue, comme happiness ou
geluk. Vous pouvez penser à une autre forme du mot : heureux. Selon vos
goûts musicaux, vous pouvez penser à une chanson de Taylor Swift, de Pharrell
Williams ou à « si tu aimes le soleil, tape des mains ».
Quand un programme informatique « lit » le mot bonheur, il ne reçoit qu’une
suite de bits : les nombres associés aux caractères de ce mot précis. Les
seules mises en relation faciles à calculer seraient avec d’autres suites de
bits semblables. Le mot honneur, par exemple, a exactement la même longueur
et cinq de ses sept lettres à la même place.
Figure 1. Ce que le mot apporte à qui le lit, et ce qui parvient à l'ordinateur. Les codes ne pointent vers rien, et ils ne séparent bonheur de honneur que par deux caractères.
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
AmbiguityAmbiguïté
Il est encore là means he is still there, when you have been waiting for him
to leave. It means he is there again, when he also came yesterday. Same four
words, and English has no one word that covers both: the translation has to
commit to still or to again. You make that choice from context, instantly
and usually without registering that a choice existed.
Ambiguity like this runs through language at every level:
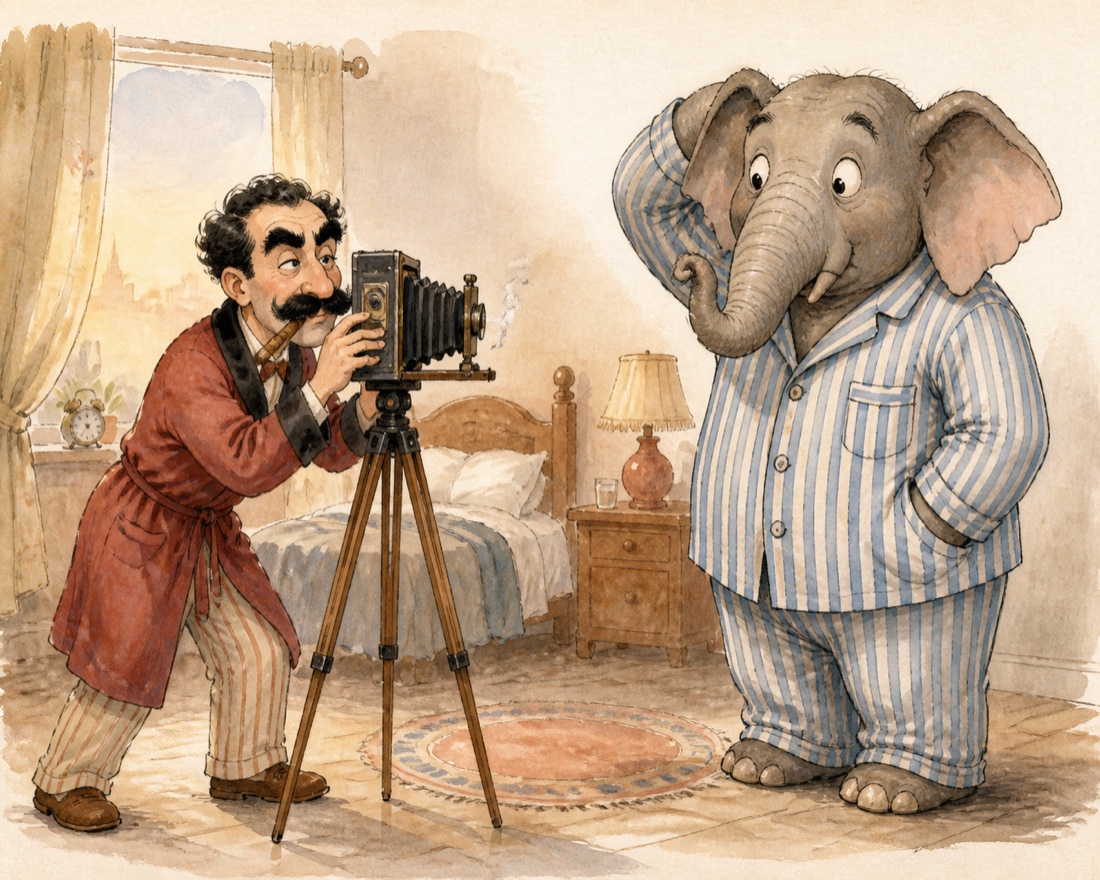
Structure. Groucho Marx, in Animal Crackers: “One morning I shot an
elephant in my pajamas. How he got in my pajamas, I don’t know.” The joke is
the second sentence taking the reading you did not. In my pajamas can hang
from shot or from elephant, both are grammatical, and nothing but your
sense of what is likely picked one.
Figure 2. Illustration of “One morning I shot an elephant in my pajamas. How he got in my pajamas, I don’t know.” Image generated withImage générée avec ChatGPT 5.6 Sol.
The promptLa requête
I want to generate an image to illustrate Groucho Marx's joke "One morning I shot an elephant in my pajamas. How he got into my pajamas I'll never know." Can you generate an image of a moustached person with big eyebrows and a cigar, shooting a picture of an elephant wearing pajamas? Make it resemble a watercolour picture.
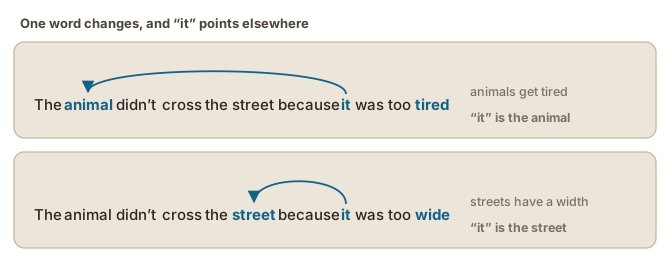
Reference. In the animal didn’t cross the street because it was too
tired, the word it points at the animal; make the ending too wide and
the same word points at the street. Nothing in the grammar decides; what
streets and animals can be does.
Figure 3. One word at the end changes, and the pronoun points at the other noun. The grammar is identical in both.
The same property makes this hard for machines and invisible to people.
Resolving it was too wide takes knowledge about streets; resolving encore
takes the surrounding sentences. You bring that knowledge for free. A
computer has to be given it, in a form it can compute with.
Your professional reflex, it depends on the context, is the requirement
that word-by-word approaches to language technology could not satisfy.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Il est encore là veut dire qu’il n’est pas encore parti, quand vous
attendiez qu’il parte. Cela veut dire qu’il est revenu, quand il était déjà venu
la veille. Les quatre mêmes mots, et l’anglais n’a aucun mot qui couvre les deux
sens : la traduction doit trancher entre still et again. Vous faites ce
choix à partir du contexte, immédiatement et sans même remarquer qu’un choix
se présentait.
Une ambiguïté de ce genre traverse la langue à tous les niveaux :
La structure. Groucho Marx, dans Animal Crackers : « One morning I
shot an elephant in my pajamas. How he got in my pajamas, I don’t know. »
La blague tient à la deuxième phrase, qui prend le sens que vous n’aviez pas
retenu. In my pajamas peut se rattacher à shot ou à elephant, les deux
sont grammaticaux, et rien d’autre que votre idée du vraisemblable n’en a
choisi un.
Figure 2. Illustration de « One morning I shot an elephant in my pajamas. How he got in my pajamas, I don’t know. » Image generated withImage générée avec ChatGPT 5.6 Sol.
The promptLa requête
I want to generate an image to illustrate Groucho Marx's joke "One morning I shot an elephant in my pajamas. How he got into my pajamas I'll never know." Can you generate an image of a moustached person with big eyebrows and a cigar, shooting a picture of an elephant wearing pajamas? Make it resemble a watercolour picture.
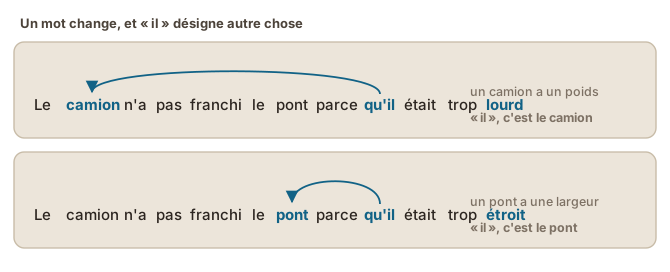
La référence. Dans le camion n’a pas franchi le pont parce qu’il était
trop lourd, le mot il désigne le camion ; mettez trop étroit à la fin et
le même mot désigne le pont. Les deux noms sont masculins, donc la grammaire
ne tranche pas ; ce sont les propriétés des camions et des ponts qui le
font.
Figure 3. Un mot change à la fin, et le pronom désigne l'autre nom. La grammaire est identique dans les deux cas.
C’est la même propriété qui rend la chose difficile pour une machine et
invisible pour une personne. Résoudre trop étroit demande de savoir ce
qu’est un pont ; résoudre encore demande les phrases autour. Vous apportez
ce savoir gratuitement. Il faut le donner à un ordinateur, sous une forme
avec laquelle il peut calculer.
Votre réflexe professionnel, cela dépend du contexte, est l’exigence à
laquelle les approches mot à mot de la technologie langagière n’ont pas pu
répondre.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Variation and exceptionsVariation et exceptions
Language never stands still or stays uniform. The French of a Montréal
contract, a Paris news site and a group chat differ in vocabulary, spelling
and syntax while all being French. New words arrive continuously (selfie,
deepfake and a steady stream of borrowed tech vocabulary; covid did not
exist in 2019 and was unavoidable a year later), old words shift sense, and
real text is full of typos, abbreviations and creative usage that no
dictionary anticipated.
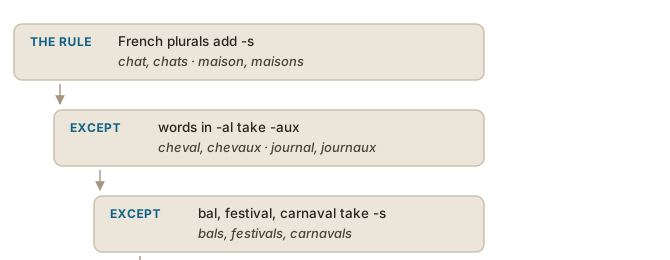
And where language does follow rules, as the expression goes, the exception
proves the rule. French plurals add -s, except -al words taking -aux,
except bals and festivals; English past tenses add -ed, except a few
hundred of the most frequent verbs. Writing the rule is quick. The real
challenge is writing the exceptions, the exceptions to the exceptions, and
the way the rules interact with one another: each addition fixes some cases
and breaks others, and the effort of maintaining the set grows with its size.
Figure 4. Writing the rule is quick. The real challenge is its exceptions, their exceptions, and how they interact with the rest of the system.
This is the concrete experience behind the move to learning from
data (see also the Four paradigms page, in the Foundations of AI & NLP module) (voir aussi la page Quatre paradigmes, dans le module Fondements de l'IA et du TAL). A statistical system does
not need the exception list written out. Given enough text, the exceptions
are in the data, with their frequencies attached.
The catch is the phrase given enough text. A system that learns language
from data inherits the language of that data, its regions, registers and
blind spots included, and that inheritance can be measured directly on the
languages a model handles worst (see also the Consequences of tokenization chapter) (voir aussi le chapitre Conséquences de la jetonisation).
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
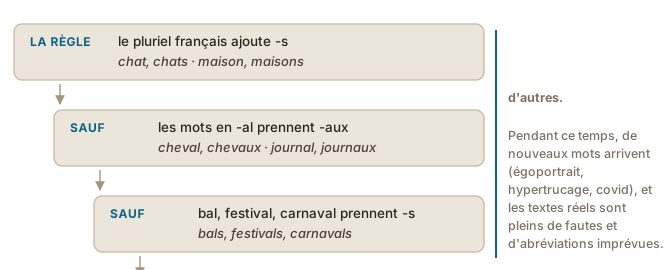
La langue ne s’arrête jamais et ne reste jamais uniforme. Le français d’un
contrat montréalais, d’un site d’information parisien et d’un fil de
clavardage diffère par le vocabulaire, l’orthographe et la syntaxe tout en
restant du français. De nouveaux mots arrivent continuellement (égoportrait,
hypertrucage et un flux constant de vocabulaire technique emprunté ;
covid n’existait pas en 2019 et était incontournable un an plus tard), des
mots anciens changent de sens, et les textes réels sont pleins de fautes de
frappe, d’abréviations et d’usages inventifs qu’aucun dictionnaire n’avait
prévus.
Et là où la langue suit bel et bien des règles, comme dit l’expression,
l’exception confirme la règle. Le pluriel français ajoute -s, sauf les mots
en -al qui prennent -aux, sauf bals et festivals ; le prétérit anglais
ajoute -ed, sauf quelques centaines des verbes les plus fréquents. Écrire la
règle est rapide. La vraie difficulté est d’écrire les exceptions, les
exceptions aux exceptions et la façon dont les règles interagissent entre
elles : chaque ajout corrige des cas et en casse d’autres, et l’effort
d’entretien croît avec la taille du jeu de règles.
Figure 4. Écrire la règle est rapide. La vraie difficulté, ce sont ses exceptions, les exceptions de celles-ci, et la façon dont elles interagissent avec le reste du système.
C’est l’expérience concrète qui explique le passage à l’apprentissage à partir
de données (see also the Four paradigms page, in the Foundations of AI & NLP module) (voir aussi la page Quatre paradigmes, dans le module Fondements de l'IA et du TAL). Un système statistique
n’a pas besoin qu’on lui écrive la liste des exceptions. Avec assez de texte,
les exceptions sont dans les données, avec leurs fréquences.
Le piège tient dans l’expression avec assez de texte. Un système qui
apprend la langue à partir de données hérite de la langue de ces
données, avec ses régions, ses registres et ses angles morts, et cet héritage
se mesure directement sur les langues qu’un modèle traite le plus
mal (see also the Consequences of tokenization chapter) (voir aussi le chapitre Conséquences de la jetonisation).
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
From words to numbersDes mots aux nombres
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
A number for each wordUn nombre par mot
If words have to become numbers, the obvious first move is a list: a
dictionary with its entries numbered.
Every word now has a number, and the conversion is trivial in both
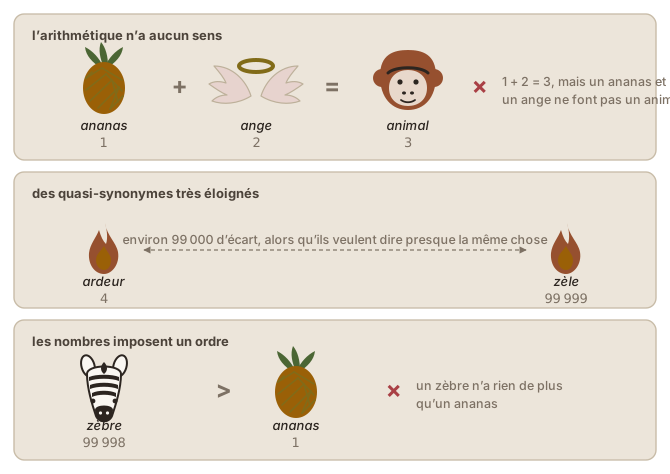
directions. But, as Figure 1figure 1 shows,
there are three specific issues, where such numbers miss some essential part
of what would make them useful.
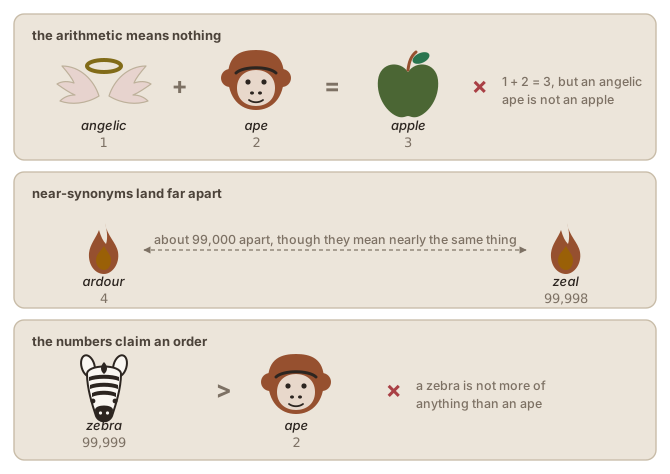
Figure 1. Three issues with one number per word: the arithmetic means nothing, near-synonyms land far apart, and the numbers claim an order the words do not have.
Arithmetic on these numbers is meaningless. One plus two is three, so an
angelic (1) ape (2) makes an apple (3)? Any calculation a system
performs on the codes manipulates alphabetical position, which has nothing
to do with what the words mean.
The numbers place related words no closer than unrelated ones. Ardour (4)
and zeal (99,998) are near-synonyms sitting about 99,000 apart, farther
from each other than either is from apple. A translation system needs
exactly the opposite: words with similar meanings should have similar
representations.
A single number per word smuggles in an ordering. 99,999 is bigger than 2,
but zebra is not more of anything than ape. A model fed these codes
risks attaching meaning to the size of the number, where the only thing
behind it is alphabetical order.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Si les mots doivent devenir des nombres, le premier réflexe est d’en faire une
liste : un dictionnaire dont les entrées sont numérotées.
Chaque mot a maintenant un nombre, et la conversion se fait sans effort dans
les deux sens. Mais, comme le montre la Figure 1figure 1,
trois problèmes précis apparaissent, où de tels nombres passent à côté de ce
qui les rendrait utiles.
Figure 1. Trois problèmes d'un nombre par mot : l'arithmétique n'a aucun sens, des quasi-synonymes se retrouvent très éloignés, et les nombres imposent un ordre que les mots n'ont pas.
L’arithmétique sur ces nombres n’a aucun sens. Un plus deux font trois : un
ananas (1) et un ange (2) donneraient donc un animal (3) ? Tout calcul
effectué sur ces codes manipule une position alphabétique, qui n’a rien à
voir avec le sens des mots.
Les nombres ne rapprochent pas les mots apparentés plus que les mots sans
rapport. Ardeur (4) et zèle (99 999) sont des quasi-synonymes séparés par
environ 99 000, plus loin l’un de l’autre que chacun ne l’est d’animal. Un
système de traduction a besoin exactement de l’inverse : des mots de sens
proches devraient avoir des représentations proches.
Un seul nombre par mot introduit un ordre en douce. 99 998 est plus grand que
1, mais un zèbre n’a rien de plus qu’un ananas. Un modèle nourri de ces
codes risque de prêter un sens à la taille du nombre, alors que la seule chose
derrière elle est l’ordre alphabétique.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
VectorsLes vecteurs
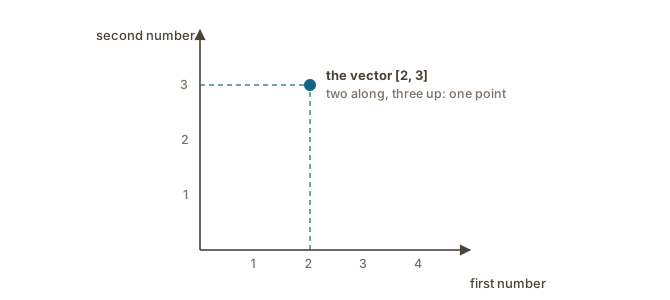
The word vector sounds more technical than what it names.
Read [2, 3] as directions on a map: two steps along the horizontal axis,
three along the vertical, and you have marked a point. A vector with three
numbers marks a point in three-dimensional space, and nothing stops a vector
from having three hundred numbers; the space can no longer be drawn or
imagined, but the mathematics works the same way.
Figure 2. A vector read as coordinates: the list [2, 3] marks one point in a two-dimensional space.
Points, unlike bare code numbers, have geometry. Two points can be close
together or far apart; a cluster of points forms a group; a direction in the
space can be followed. If each word is placed at a point, then closeness in
the space becomes available to represent closeness in meaning, which a single
number per word had no way to express.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
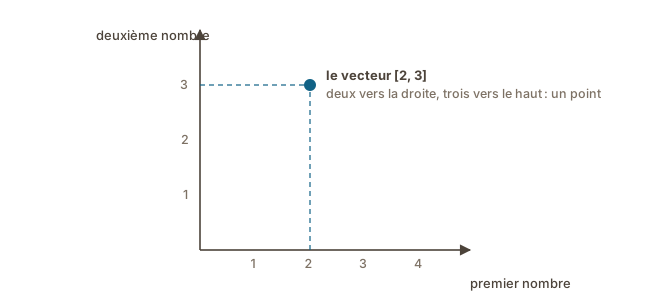
Le mot vecteur a l’air plus technique que ce qu’il désigne.
[2, 3] se lit comme des indications sur une carte : deux pas le long de l’axe
horizontal, trois le long de l’axe vertical, et un point est marqué. Un vecteur
de trois nombres marque un point dans un espace à trois dimensions, et rien
n’empêche un vecteur d’avoir trois cents nombres ; l’espace ne peut alors plus
être dessiné ni imaginé, mais les mathématiques fonctionnent de la même façon.
Figure 2. Un vecteur lu comme des coordonnées : la liste [2, 3] marque un point dans un espace à deux dimensions.
Les points, contrairement à de simples numéros de code, ont une géométrie. Deux
points peuvent être proches ou éloignés ; un ensemble de points forme un
groupe ; une direction peut être suivie dans l’espace. Si chaque mot est placé
en un point, la proximité dans l’espace devient disponible pour représenter la
proximité de sens, ce qu’un seul nombre par mot n’avait aucun moyen d’exprimer.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
One-hot vectorsLes vecteurs 1 parmi n
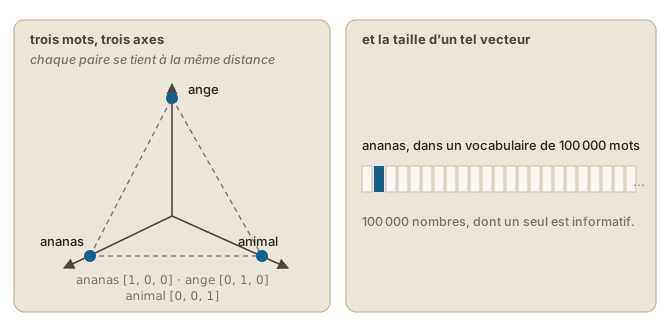
The first vector representation of words that the field actually used works
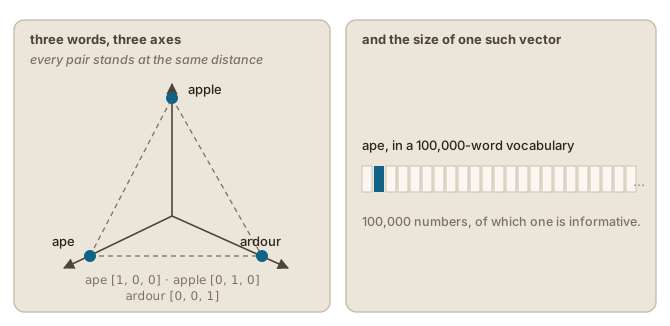
like a row of switches with one of them on. Each word in a 100,000-word
vocabulary gets its own position, and is represented as a vector of 100,000
numbers: zeros everywhere, except a single 1 at that word’s position.
The false ordering is gone. No word’s vector is larger than another’s;
zebra is no longer “more” than ape. In the geometry of the space, each
word now owns its own axis, and every pair of words stands at exactly the
same distance, like the corners of a perfectly symmetric figure.
Figure 3. Each word owns an axis, so no word is larger than another and every pair stands at the same distance. Almost the whole vector is zeros.
Exactly the same distance is also the new problem. Ardour is now precisely
as different from zeal as from zebra: the representation contains no
similarity information at all, for anyone. It identifies words the way a
locker number identifies a student, saying nothing about them.
There is a practical objection too. These vectors are enormous, and almost
all of their content is zeros: 100,000 numbers per word, of which one is
informative.
The numbered list crammed every word onto one axis and invented differences;
the one-hot vector gives every word its own axis and erases all resemblance.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
La première représentation vectorielle des mots que le domaine ait réellement
utilisée fonctionne comme une rangée d’interrupteurs dont un seul est allumé.
Chaque mot d’un vocabulaire de 100 000 mots reçoit sa propre position et est
représenté par un vecteur de 100 000 nombres : des zéros partout, sauf un seul
1 à la position de ce mot.
L’ordre trompeur a disparu. Le vecteur d’un mot n’est jamais plus grand que
celui d’un autre ; zèbre n’est plus « plus » qu’ananas. Dans la géométrie de
l’espace, chaque mot possède désormais son propre axe, et chaque paire de mots
se tient exactement à la même distance, comme les sommets d’une figure
parfaitement symétrique.
Figure 3. Chaque mot possède son axe, donc aucun mot n'est plus grand qu'un autre et chaque paire se tient à la même distance. Presque tout le vecteur est fait de zéros.
Cette distance identique est aussi le nouveau problème. Ardeur est maintenant
exactement aussi différent de zèle que de zèbre : la représentation ne
contient aucune information de similarité, pour personne. Elle identifie les
mots comme un numéro de casier identifie un étudiant, sans rien dire de lui.
Il y a aussi une objection pratique. Ces vecteurs sont énormes et leur contenu
est presque entièrement fait de zéros : 100 000 nombres par mot, dont un seul
est informatif.
La liste numérotée entassait tous les mots sur un seul axe et inventait des
différences ; le vecteur 1 parmi n donne à chaque mot son propre axe et efface
toute ressemblance. Ce qu’il faut se situe entre les deux : des vecteurs comptant
un nombre modeste de dimensions, partagées par tous les mots, où les valeurs
placent les mots de sens proches près les uns des autres.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Word embeddingsPlongements lexicaux
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
All words equally differentTous les mots à égale distance
Numbers that say how words relate. So far cat is exactly as far from
dog as it is from democracy.
A representation that stays manageable and still says something.
Giving every word its own slot takes tens of thousands of numbers to say one
thing, and all but one of them are zero.
A representation that can change with the sentence.Bank does not mean
the same thing in every sentence it appears in, and one fixed set of numbers
per word cannot follow that.
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Ce que les deux chapitres précédents ont établi
L’idée
Ce qu’elle apporte
Ce qu’elle coûte
Un nombre par mot, par ordre alphabétique
Un identifiant
Un ordre et une arithmétique qui ne veulent rien dire
Des coordonnées dans un espace, donc des distances
Rien encore : l’espace reste à construire
Un vecteur 1 parmi n
Une identité sans faux ordre
Toutes les paires à égale distance ; 99 999 zéros par mot
Ce qui manque encore
Des nombres qui disent comment les mots se rapportent. Jusqu’ici, chat
est exactement aussi loin de chien que de démocratie.
Une représentation qui reste maniable et qui dit quelque chose. Donner à
chaque mot sa propre case demande des dizaines de milliers de nombres pour
dire une seule chose, et tous sauf un valent zéro.
Une représentation qui peut changer avec la phrase.Livres ne veut pas
dire la même chose dans toutes les phrases où le mot apparaît, et un seul jeu
de nombres fixe par mot ne peut pas suivre.
Ce chapitre répond aux deux premiers points. Le troisième demande un chapitre
à lui seul (see also the Contextual embeddings chapter) (voir aussi le chapitre Plongements contextuels).
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Dimensions with meaningDes dimensions qui veulent dire quelque chose
Words as coordinates
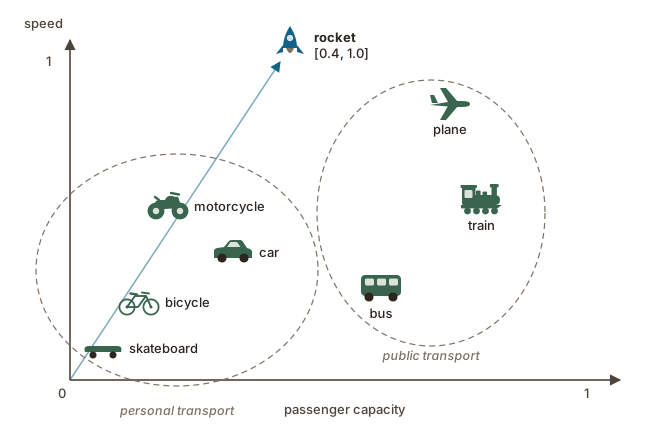
Suppose you want to place words in a two-dimensional space. You give the
horizontal axis one meaning and the vertical axis another, then put each word
where it belongs relative to those two meanings. Every word ends up with
coordinates, which is to say a vectorvectorvecteurmachine learningapprentissage automatiqueAn ordered list of numbers.Liste ordonnée de nombres.: here a list of
two numbers, one per axis. Those numbers do more than locate the word. They say
how it stands on each of the two meanings, and how far it is from every other
word in the same space.
Speed and capacity
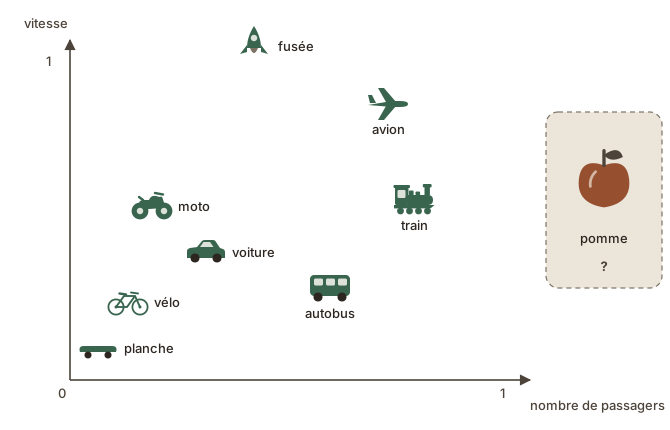
Figure 1. Two hand-picked dimensions, passenger capacity and speed. Every vehicle gets a vector, and groups form that nobody drew.
The idea is worked out for means of transport in
Figure 1figure 1.
The horizontal axis is passenger capacity and the vertical axis is speed, and
most people would agree on roughly where each vehicle goes. A skateboard scores
low on both: it does not travel fast and it carries one person. A rocket has
maximal speed and more moderate capacity, giving it the vector [0.4, 1.0]. Where
a one-hot vector only identified a word, that pair of numbers says something
about the thing named, and it fixes how far the rocket stands from every other
vehicle in the space.
Placing words this way also makes groups form on their own. Personal transport
gathers on the left, public transport on the right, and the rocket sits apart,
which is where it belongs. Nobody drew those groups; they follow from the
coordinates.
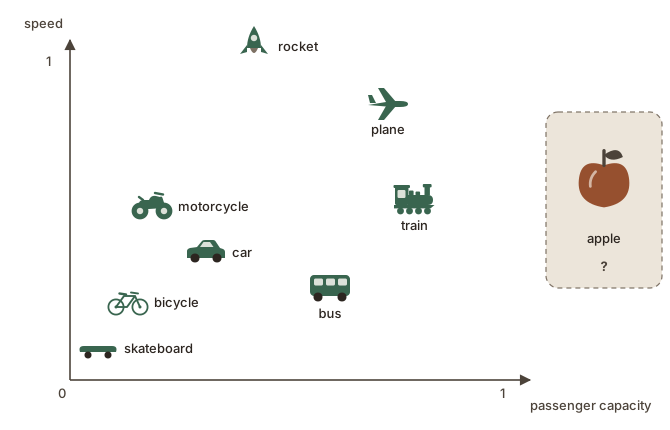
Where the apple goes
So far this looks like a promising way to turn words into lists of numbers that
mean something. Then: where would you put an apple in this space? The
question makes no sense, because speed and capacity say nothing about an apple.
Figure 2. The same two axes, and an apple that neither of them measures.
Two things follow. A space that fits a whole vocabulary needs many more than
two dimensions, since it has to suit everything from skateboard to ardour.
And once there are hundreds of dimensions and tens of thousands of words,
neither the axes nor the positions can be chosen by a person.
Which leaves the question: how can numbers like these be found automatically,
for every word in a vocabulary?
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Les mots comme coordonnées
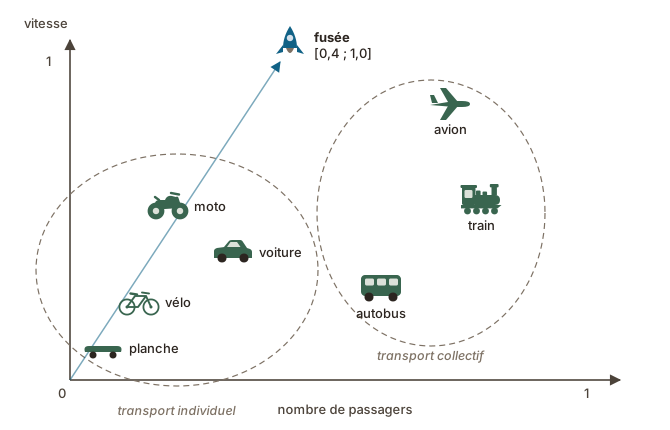
Supposons que vous vouliez placer des mots dans un espace à deux dimensions.
Vous donnez un sens à l’axe horizontal et un autre à l’axe vertical, puis vous
posez chaque mot là où il se situe par rapport à ces deux sens. Chaque mot se
retrouve avec des coordonnées, c’est-à-dire un vecteurvectorvecteurmachine learningapprentissage automatiqueAn ordered list of numbers.Liste ordonnée de nombres. :
ici une liste de deux nombres, un par axe. Ces nombres font plus que localiser
le mot. Ils disent comment il se situe sur chacun des deux sens, et à quelle
distance il se trouve de tous les autres mots du même espace.
La vitesse et le nombre de passagers
Figure 1. Deux dimensions choisies à la main, le nombre de passagers et la vitesse. Chaque véhicule reçoit un vecteur, et des groupes se forment que personne n'a dessinés.
L’idée est développée pour des moyens de transport dans la
Figure 1figure 1.
L’axe horizontal est le nombre de passagers et l’axe vertical la vitesse, et la
plupart des gens s’entendraient sur la place approximative de chaque véhicule.
La planche est basse sur les deux : elle ne va pas vite et elle transporte une
personne. La fusée a une vitesse maximale et une capacité plus modeste, ce qui
lui donne le vecteur [0,4 ; 1,0]. Là où un vecteur 1 parmi n ne faisait
qu’identifier un mot, cette paire de nombres dit quelque chose de la chose
nommée, et elle fixe la distance entre la fusée et tous les autres véhicules de
l’espace.
Placer les mots de cette façon fait aussi apparaître des groupes d’eux-mêmes.
Le transport individuel se rassemble à gauche, le transport collectif à droite,
et la fusée reste à part, là où elle a sa place. Personne n’a dessiné ces
groupes ; ils découlent des coordonnées.
Où placer la pomme
Jusqu’ici, voilà une manière prometteuse de transformer des mots en listes de
nombres qui veulent dire quelque chose. Puis : où placeriez-vous une pomme dans
cet espace ? La question n’a aucun sens, parce que la vitesse et le nombre de
passagers ne disent rien d’une pomme.
Figure 2. Les deux mêmes axes, et une pomme que ni l'un ni l'autre ne mesure.
Deux conséquences. Un espace qui accueille un vocabulaire entier a besoin de
bien plus de deux dimensions, puisqu’il doit convenir à tout, de planche à
ardeur. Et dès qu’il y a des centaines de dimensions et des dizaines de
milliers de mots, ni les axes ni les positions ne peuvent être choisis par une
personne.
Reste la question : comment trouver automatiquement de tels nombres, pour
chaque mot d’un vocabulaire ?
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
The company a word keepsLa compagnie que tient un mot
Five blanks
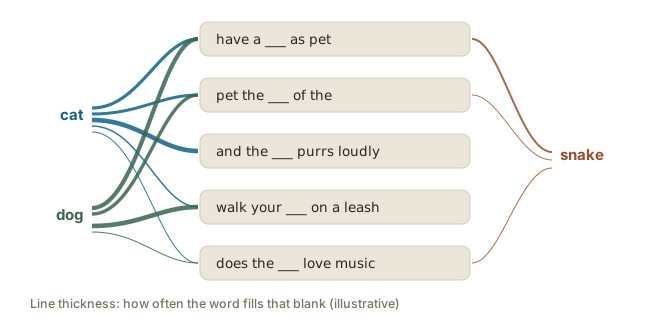
Suppose you are given five fragments of text, each with one word missing:
have a ___ as pet
pet the ___ of the
and the ___ purrs loudly
walk your ___ on a leash
does the ___ love music
Which words could fill the blank? Cat goes into the first three without any
trouble; the leash makes you hesitate. Dog goes into the pet, the petting and
the leash, and fails at the purring. The last fragment takes any of them, which
is why it tells you so little. So the two words share most of their contexts,
and the ones they do not share are exactly the ones you would expect: a cat
purrs, a dog is walked.
Now try snake. It fits have a ___ as pet, and after that it gets harder: a
snake does not purr, and a snake on a leash is a very big stretch. Snake
shares one or two contexts with cat and dog and not the rest. A word like
democracy fits none of the five.
Not only whether a word can fill a blank counts, but how often it does.
Cat turns up before purrs far more often than after walk your, and a
system that counts contexts in a large collection of text sees that difference
directly.
Figure 3. Similar words fill similar blanks, and how often they do is the part that counts. Cat and dog share most of their contexts; snake shares far fewer.
What the blanks show
Words with related meanings turn up in similar contexts, and the more two
words’ contexts overlap, the closer their meanings tend to be. Linguists
formulated this in the 1950s, Joos, Harris and Firth among them (Jurafsky &
Martin, 2026), and Firth put it in one sentence: “You shall know a word by the
company it keeps” (Firth, 1957).
Why this suits a machine
The idea is useful for a machine because of what it does not require:
No definitions. Nobody has to say what cat means.
No labels. Nobody has to mark examples by hand.
No hand-picked axes. Nobody chooses the dimensions of the space, or where
each word goes on them.
It does require text, in quantity. Contexts are observable: any large
collection of text shows directly which words surround which. So a system can
build a workable stand-in for meaning just by reading enough text.
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Cinq trous
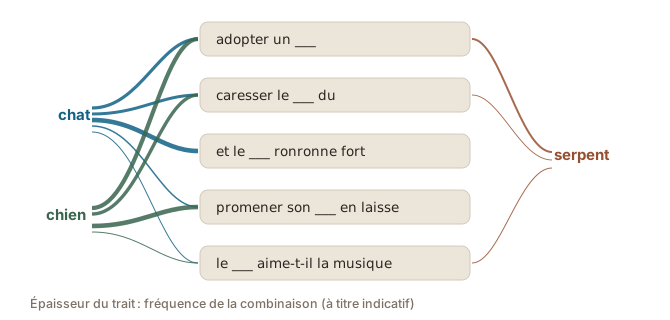
Supposons qu’on vous donne cinq fragments de texte, chacun avec un mot
manquant :
adopter un ___
caresser le ___ du
et le ___ ronronne fort
promener son ___ en laisse
le ___ aime-t-il la musique
Quels mots pourraient remplir le trou ? Chat entre sans peine dans les trois
premiers ; la laisse fait hésiter. Chien entre dans l’adoption, la caresse et
la laisse, et échoue sur le ronronnement. Le dernier fragment accepte n’importe
lequel des trois, et c’est pourquoi il vous apprend si peu. Les deux mots
partagent donc la plupart de leurs contextes, et ceux qu’ils ne partagent pas
sont exactement ceux qu’on attendrait : un chat ronronne, on promène un chien.
Essayez maintenant serpent. Il va avec adopter un ___, et ensuite, cela se
complique : un serpent ne ronronne pas, et un serpent en laisse, c’est
vraiment tiré par les cheveux. Serpent partage un ou deux contextes avec
chat et chien, et pas le reste. Un mot comme démocratie ne remplit
aucun des cinq.
Il ne suffit pas qu’un mot puisse remplir un trou : la fréquence à laquelle
il le fait compte aussi. Chat précède ronronne bien plus souvent
qu’il ne suit promener son, et un système qui compte les contextes dans un
grand ensemble de textes voit cette différence directement.
Figure 3. Des mots semblables remplissent des trous semblables, et la fréquence est la part qui compte. Chat et chien partagent la plupart de leurs contextes ; serpent en partage bien moins.
Ce que montrent les trous
Les mots dont le sens est apparenté apparaissent dans des contextes semblables,
et plus les contextes de deux mots se recoupent, plus leurs sens ont tendance à
être proches. Des linguistes l’ont formulé dans les années 1950, Joos, Harris
et Firth parmi eux (Jurafsky et Martin, 2026), et Firth l’a résumé en une
phrase : « You shall know a word by the company it keeps » (Firth, 1957).
Pourquoi cela convient à une machine
L’idée est utile à une machine par ce qu’elle n’exige pas :
Aucune définition. Personne n’a à dire ce que chat veut dire.
Aucune annotation. Personne n’a à marquer des exemples à la main.
Aucun axe choisi à la main. Personne ne choisit les dimensions de
l’espace, ni la place de chaque mot sur celles-ci.
Il faut en revanche du texte, en quantité. Les contextes sont observables :
n’importe quel grand ensemble de textes montre directement quels mots
entourent quels autres. Un système peut donc se construire un substitut
utilisable du sens simplement en lisant assez de texte.
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Embeddings learned from textDes plongements appris à partir de textes
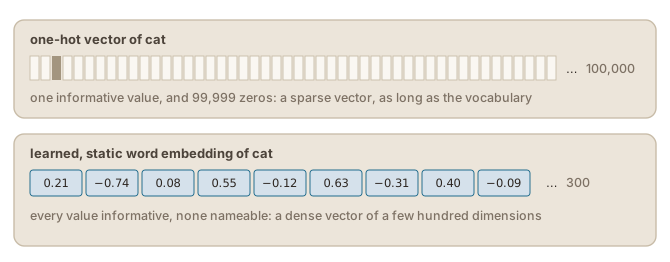
Every property of these vectors contrasts with the one-hot representation:
Short instead of vocabulary-sized. Typically 100 to 300 dimensions rather
than one per word.
Dense instead of sparse. Every position has a meaningful value rather
than a zero.
Distance means something.Cat and dog end up close, snake farther,
democracy elsewhere entirely, because their contexts imposed it
during training.
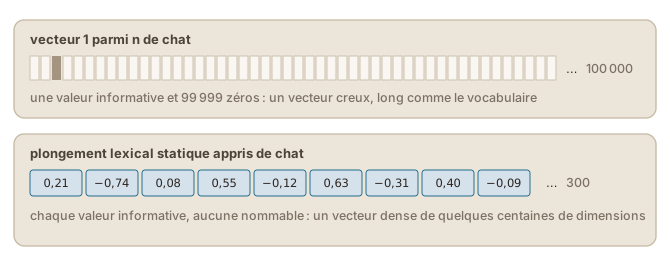
Figure 4. The same word in the two representations. The learned vector is short and dense, and no single one of its values can be read on its own.
No readable axes
The example with our means of transport showed axes that were interpretable:
speed and capacity. The learned dimensions are not. They do not correspond to
any nameable property, and looking at one value tells you nothing. In this
representation a word’s meaning is the whole pattern of all its values
together, and only comparisons between whole vectors are meaningful.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013a). Efficient Estimation of Word Representations in Vector Space. arXiv preprint arXiv:1301.3781 (ICLR 2013 Workshop Track). https://arxiv.org/abs/1301.3781
Pennington, J., Socher, R., & Manning, C. (2014). GloVe: Global Vectors for Word Representation. Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP). https://doi.org/10.3115/v1/D14-1162
Court, dense, et des distances qui veulent dire quelque chose
Chaque propriété de ces vecteurs contraste avec la représentation 1 parmi n :
Court plutôt que long comme le vocabulaire. Typiquement de 100 à 300
dimensions, plutôt qu’une par mot.
Dense plutôt que creux. Chaque position porte une valeur informative
plutôt qu’un zéro.
La distance veut dire quelque chose.Chat et chien se retrouvent
proches, serpent plus loin, démocratie tout à fait ailleurs, parce que
leurs contextes l’ont imposé pendant l’entraînement.
Figure 4. Le même mot dans les deux représentations. Le vecteur appris est court et dense, et aucune de ses valeurs ne se lit isolément.
Des axes illisibles
L’exemple des moyens de transport montrait des axes interprétables : la vitesse
et le nombre de passagers. Les dimensions apprises ne le sont pas. Elles ne
correspondent à aucune propriété nommable, et regarder une seule valeur ne dit
rien. Dans cette représentation, le sens d’un mot est le motif complet de
toutes ses valeurs prises ensemble, et seules les comparaisons entre vecteurs
entiers ont un sens.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013a). Efficient Estimation of Word Representations in Vector Space. arXiv preprint arXiv:1301.3781 (ICLR 2013 Workshop Track). https://arxiv.org/abs/1301.3781
Pennington, J., Socher, R., & Manning, C. (2014). GloVe: Global Vectors for Word Representation. Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP). https://doi.org/10.3115/v1/D14-1162
Arithmetic with meaningsDe l'arithmétique avec des sens
Take the vector for king, subtract the vector for man, and add the vector
for woman. The point you land on is nearest the word queen (Mikolov et al.,
2013b). Nothing in the training aimed at this. It falls out of the geometry:
the displacement from man to king encodes something like royalty, and
applying that same displacement to woman arrives near queen.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 5. Subtracting man from king leaves the crown, and adding woman to the crown arrives at queen.
One direction among many
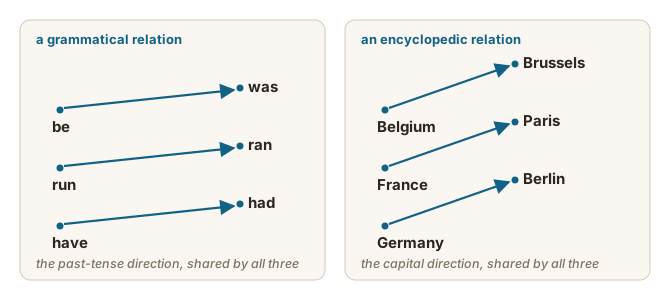
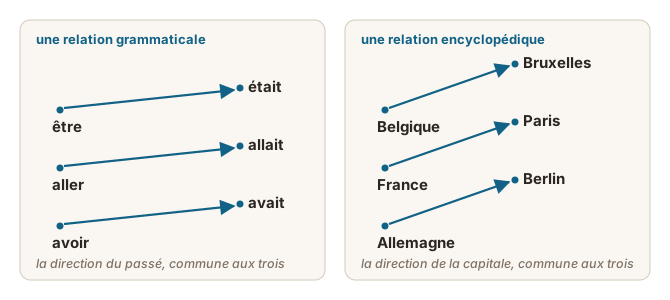
The royalty direction is one of many. Mikolov et al. (2013b) tested the pattern
systematically on grammatical relations, a thousand questions each for
comparatives (good is to better as rough is to rougher), plurals (year
is to years) and verb tense (see is to saw as return is to returned),
and found it there too. Encyclopedic relations behave the
same way, a country and its capital among them (Jurafsky & Martin, 2026). The
axes are still unreadable. The meaning is in the directions between whole
vectors, and those can be looked for after the fact.
Figure 6. A grammatical relation and an encyclopedic one, each a direction that every pair shares.
Carnegie Mellon’s browser demo does exactly that. The three screenshots below
were taken from it on 9 September 2026, and the demo can change. They are dense, and
a click opens each one larger.
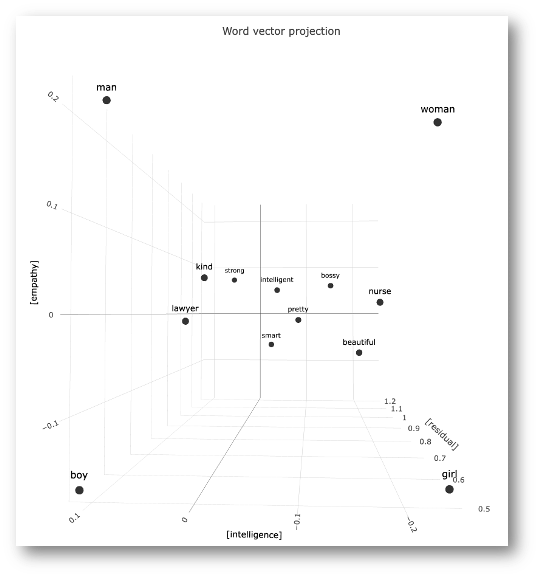
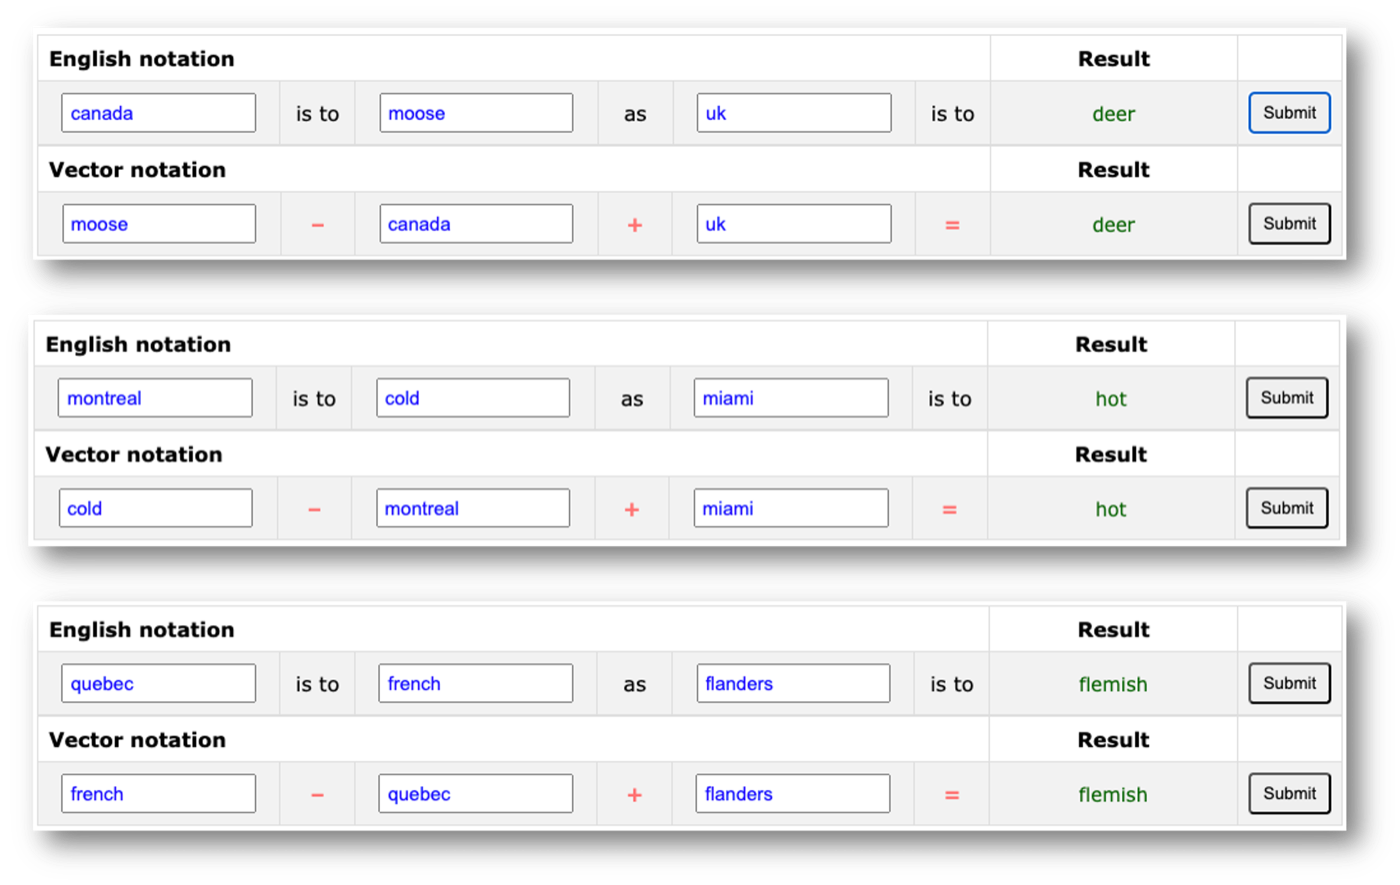
Figure 7. The space projected onto two directions named by words: intelligence and empathy. The axes were chosen after training, not built into it. Figure 8. Three analogies on the demo's word2vec vectors. Canada is to moose as UK is to deer, Montreal is to cold as Miami is to hot, Quebec is to French as Flanders is to Flemish. Each analogy is typed in words above and as vector arithmetic below, and the two forms return the same word.
The same arithmetic on stereotypes
The arithmetic works on stereotypes too. In embeddings trained on Google News
articles, man is to computer programmer as woman is to homemaker, and
occupation words divide along a gender direction the same way king and
queen divide along a royalty one (Bolukbasi et al., 2016).
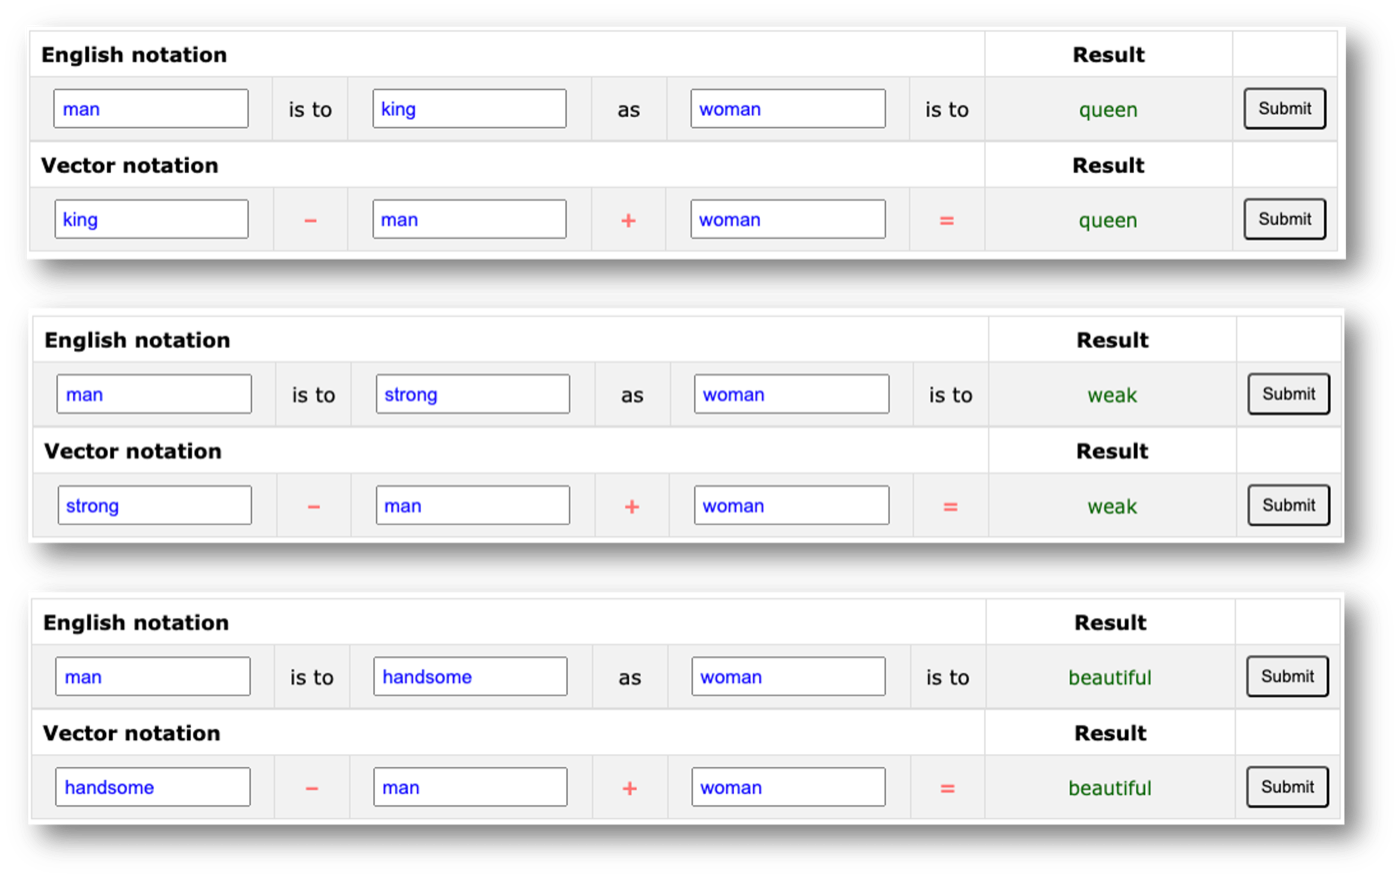
Figure 9. The same demo, on the same word2vec vectors. Man is to king as woman is to queen, the textbook analogy. Then man is to strong as woman is to weak, and man is to handsome as woman is to beautiful.
No programmer decided to put woman further from doctor and closer to
nurse. The bias comes from the text: the vectors record how the words are
used across millions of sentences, and people wrote those sentences. The method
is working as designed. The consequences reach everything built on embeddings
since (see also the Critical issues with LLMs module) (voir aussi le module Enjeux critiques des GML).
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Mikolov, T., Yih, W., & Zweig, G. (2013b). Linguistic Regularities in Continuous Space Word Representations. Proceedings of the 2013 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies. https://aclanthology.org/N13-1090/
Prenez le vecteur de roi, soustrayez le vecteur de homme, puis ajoutez le
vecteur de femme. Le point où vous arrivez a pour plus proche voisin le mot
reine (Mikolov et al., 2013b). Rien dans l’entraînement ne visait ce
résultat. Il découle de la géométrie : le déplacement de homme vers roi
encode quelque chose comme la royauté, et appliquer ce même déplacement à
femme arrive près de reine.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 5. Soustraire homme de roi laisse la couronne, et ajouter femme à la couronne arrive à reine.
Une direction parmi bien d’autres
La direction de la royauté est l’une parmi bien d’autres. Mikolov et al.
(2013b) ont éprouvé le motif de façon systématique sur des relations
grammaticales, mille questions chacune pour les comparatifs (good est à
better ce que rough est à rougher), les pluriels (year est à years)
et le temps des verbes (see est à saw ce que return est à returned), et
il tenait. Les relations encyclopédiques se comportent
de la même manière, dont celle d’un pays et de sa capitale (Jurafsky et Martin,
2026). Les axes restent illisibles. Le sens est dans les directions entre
vecteurs entiers, et celles-ci peuvent se chercher après coup.
Figure 6. Une relation grammaticale et une relation encyclopédique, chacune une direction que toutes les paires partagent.
La démonstration en ligne de Carnegie Mellon fait exactement cela. Les trois
captures ci-dessous en viennent, prises le 9 septembre 2026, et la démonstration peut
changer. Elles sont denses ; un clic ouvre chacune en plus grand.
Figure 7. L'espace projeté sur deux directions nommées par des mots : l'intelligence et l'empathie. Les axes ont été choisis après l'entraînement, ils n'y étaient pas intégrés. Figure 8. Trois analogies sur les vecteurs word2vec de la démonstration. Canada est à moose ce que UK est à deer, Montreal est à cold ce que Miami est à hot, Quebec est à French ce que Flanders est à Flemish. Chaque analogie est saisie en mots au-dessus et en arithmétique vectorielle au-dessous, et les deux formes renvoient le même mot.
La même arithmétique sur les stéréotypes
L’arithmétique fonctionne aussi sur les stéréotypes. Dans des plongements
entraînés sur des articles de Google News, man est à computer programmer ce
que woman est à homemaker, et les noms de métiers se répartissent selon une
direction de genre exactement comme roi et reine se répartissent selon une
direction de royauté (Bolukbasi et al., 2016).
Figure 9. La même démonstration, sur les mêmes vecteurs word2vec. Man est à king ce que woman est à queen, l'analogie des manuels. Puis man est à strong ce que woman est à weak, et man est à handsome ce que woman est à beautiful.
Aucun programmeur n’a décidé d’éloigner woman de doctor et de la rapprocher
de nurse. Le biais vient des textes : les vecteurs enregistrent la manière
dont les mots sont employés à travers des millions de phrases, et ce sont des
personnes qui ont écrit ces phrases. La méthode fonctionne comme prévu. Les
conséquences touchent tout ce qui a été construit sur des plongements
depuis (see also the Critical issues with LLMs module) (voir aussi le module Enjeux critiques des GML).
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Mikolov, T., Yih, W., & Zweig, G. (2013b). Linguistic Regularities in Continuous Space Word Representations. Proceedings of the 2013 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies. https://aclanthology.org/N13-1090/
The limits of static vectorsLes limites des vecteurs statiques
Three limitations
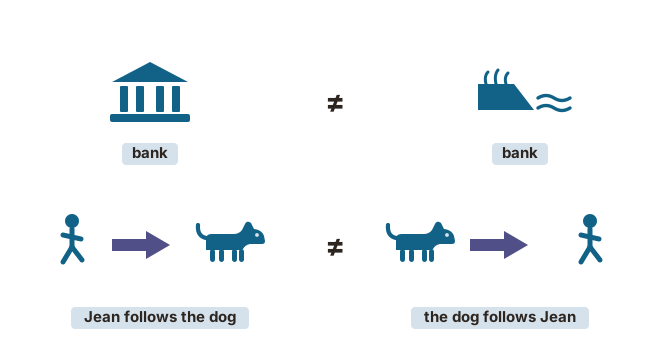
Figure 10. One form carrying two senses, and one set of words in two orders. A fixed vector per word can tell neither pair apart.
New words get nothing
An embedding model has one vector for each word that occurred in its training text, so a word
coined last year, a rare technical term or a typo has no vector and no
representation at all. Morphologically rich languages make this worse, since
their productive compounds and inflections produce forms no training corpus
contains. Modern systems dissolve the problem by working with pieces of words
instead (see also the Tokenization chapter) (voir aussi le chapitre Jetonisation).
One vector averages every sense
Bank is a financial institution in I deposited money at the bank and a
strip of riverside in we picnicked on the river bank. A single vector for
bank has to serve both sentences, so it lands somewhere between finance and
geography, a compromise that is wrong everywhere. It is not even a fair
compromise: the vector is an average over occurrences, so it sits nearest
whichever sense is commonest in the training text, and the rarer sense is
served worst. Translation feels this early, since choosing between rive and
banque is exactly a decision about which sense is active.
Order is invisible
The dog follows Jean and Jean follows the dog contain the same words and do
not describe the same walk, so any representation built by combining fixed
word vectors struggles to tell them apart. Meaning depends on arrangement, and
per-word vectors have nowhere to put arrangement.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Trois limites
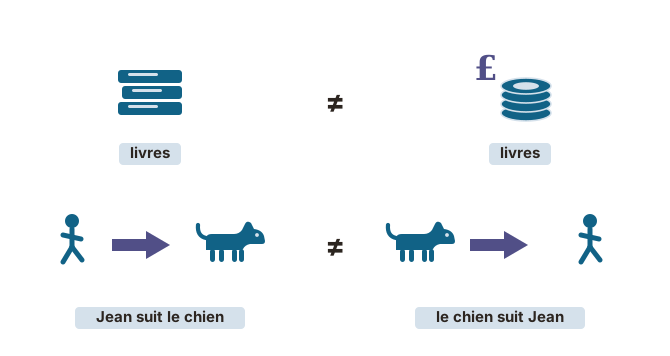
Figure 10. Une forme pour deux sens, et un même ensemble de mots dans deux ordres. Un vecteur fixe par mot ne distingue ni l'une ni l'autre paire.
Les mots nouveaux n’obtiennent rien
Un modèle de plongements a un vecteur pour chaque mot rencontré à
l’entraînement : un mot forgé l’an dernier, un terme technique rare ou une
coquille n’a donc aucun vecteur et aucune représentation. Les langues à
morphologie riche aggravent la situation, puisque leurs composés et leurs
flexions productives produisent des formes qu’aucune base d’apprentissage ne
contient. Les systèmes modernes dissolvent le problème en travaillant sur des
morceaux de mots (see also the Tokenization chapter) (voir aussi le chapitre Jetonisation).
Un seul vecteur fait la moyenne de tous les sens
Livres désigne une monnaie dans j’ai changé mille livres et des ouvrages
dans j’ai emprunté trois livres. Un vecteur unique pour livres doit servir
aux deux phrases : il atterrit donc quelque part entre la finance et la
lecture, un compromis qui a tort partout. Ce n’est même pas un compromis
équitable : le vecteur est une moyenne sur les occurrences, il se place donc au
plus près du sens le plus fréquent dans les textes d’entraînement, et c’est le
sens le plus rare qui est le plus mal servi. La traduction s’en aperçoit tôt,
puisque choisir entre pounds et books est exactement une décision sur le
sens actif.
L’ordre est invisible
Jean suit le chien et le chien suit Jean contiennent les mêmes mots et ne
décrivent pas la même promenade ; toute représentation construite en combinant
des vecteurs de mots fixes a donc du mal à les distinguer. Le sens dépend de
l’agencement, et des vecteurs par mot n’ont nulle part où mettre l’agencement.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Contextual embeddingsPlongements contextuels
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
One word, many vectorsUn mot, plusieurs vecteurs
Three sentences, one word
Take three sentences with bank in them:
I deposited money at the bank.
We picnicked on the river bank.
The plane will bank left.
You would translate the word three different ways: banque, rive, virer.
A fixed embedding gives all three the same vector.
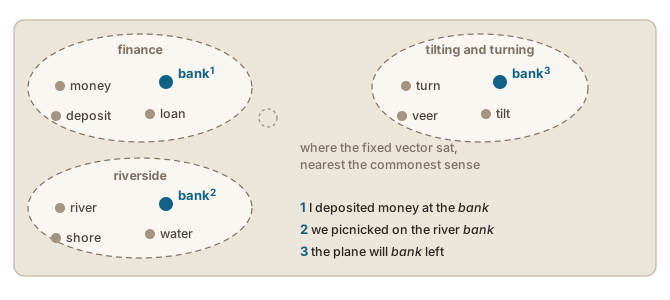
Figure 1. One vector per occurrence: the three senses land in three places, and the point where the fixed vector sat is left empty.
A vector per occurrence
A contextual embedding sides with the translator. Instead of storing one
finished vector per word, the model computes a vector for each occurrence, at
the moment of use, from the whole sentence around it:
the bank beside deposited and money comes out near the vocabulary of
finance;
the one beside river and picnicked, near geography;
the one after will, in verb territory.
Same word, three vectors, each shaped by its company. Models that work this
way arrived in the late 2010s, and ELMo was the landmark (Peters et al., 2018).
Nobody lists the senses of bank or writes a rule to pick one. The senses
simply stop being merged, because there is no single vector left for them to
be merged into.
One consequence is easy to miss. A word no longer has “its vector”, the kind
you could print in a table. It has a vector in each sentence, so the question
“what does the model think bank means?” only has answers of the form “here,
in this sentence”. Word meaning in isolation, the thing a dictionary records,
has quietly left the system.
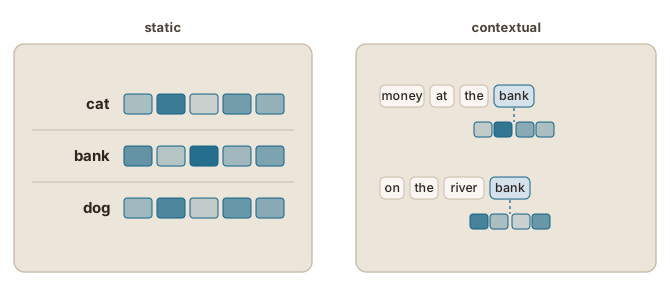
Figure 2. On the left, one row per word, a table you can look up. On the right, no table: each occurrence of bank is given a vector in its own sentence, and the two are not the same.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013a). Efficient Estimation of Word Representations in Vector Space. arXiv preprint arXiv:1301.3781 (ICLR 2013 Workshop Track). https://arxiv.org/abs/1301.3781
Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., et al. (2018). Deep Contextualized Word Representations. Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers). https://doi.org/10.18653/v1/N18-1202
Trois phrases, un seul mot
Prenons trois phrases contenant bank :
I deposited money at the bank.
We picnicked on the river bank.
The plane will bank left.
Vous traduiriez le mot de trois façons différentes : banque, rive, virer.
Un plongement fixe donne le même vecteur aux trois.
Figure 1. Un vecteur par occurrence : les trois sens atterrissent en trois endroits, et le point où se trouvait le vecteur fixe reste vide.
Un vecteur par occurrence
Un plongement contextuel donne raison à la traductrice ou au traducteur. Au
lieu de conserver un vecteur tout fait par mot, le modèle calcule un vecteur pour
chaque occurrence, au moment de l’usage, à partir de toute la phrase qui
l’entoure :
le bank voisin de deposited et de money ressort près du vocabulaire de
la finance ;
celui qui voisine avec river et picnicked, près de la géographie ;
celui qui suit will, du côté des verbes.
Même mot, trois vecteurs, chacun façonné par sa compagnie. Les modèles qui
fonctionnent ainsi arrivent à la fin des années 2010, et ELMo en est le jalon
(Peters et al., 2018).
Personne ne dresse la liste des sens de bank ni n’écrit de règle pour en
choisir un. Les sens cessent simplement d’être fusionnés, parce qu’il ne reste
aucun vecteur unique dans lequel les fusionner.
Une conséquence passe facilement inaperçue. Un mot n’a plus « son vecteur »,
celui qu’on pourrait imprimer dans un tableau. Il a un vecteur dans chaque
phrase, si bien que la question « que pense le modèle du sens de bank ? »
n’admet que des réponses de la forme « ici, dans cette phrase ». Le sens d’un
mot hors contexte, ce que consigne un dictionnaire, a discrètement quitté le
système.
Figure 2. À gauche, une rangée par mot, un tableau consultable. À droite, aucun tableau : chaque occurrence de bank reçoit un vecteur dans sa propre phrase, et les deux ne sont pas les mêmes.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013a). Efficient Estimation of Word Representations in Vector Space. arXiv preprint arXiv:1301.3781 (ICLR 2013 Workshop Track). https://arxiv.org/abs/1301.3781
Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., et al. (2018). Deep Contextualized Word Representations. Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers). https://doi.org/10.18653/v1/N18-1202
Reading in both directionsLire dans les deux sens
Before or after
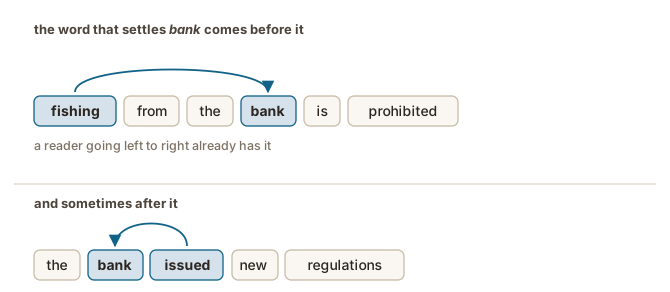
Where does the word that settles the ambiguity sit? Sometimes before the
ambiguous word: in fishing from the bank is prohibited, fishing has settled
the sense by the time bank arrives. Sometimes after it: in the bank issued
new regulations, the deciding word only comes once bank has been read.
Figure 3. The word that settles an ambiguity comes before it in one sentence and after it in the other. A model reading strictly left to right has only half of that context.
Reading both ways
ELMo already used both sides, but shallowly: one model read the sentence left
to right, a second read it right to left, and their outputs were joined at the
end, so the two directions were never combined during training (Devlin et al., 2019).
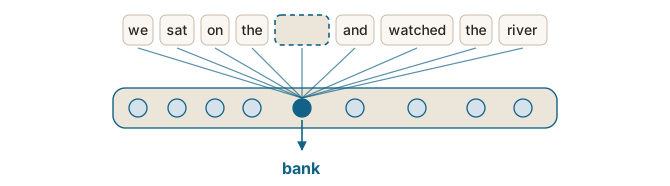
BERT is the model that put the two together.ELMo and BERT set a
fashion, and the acronyms that followed were bent to land on Sesame Street
characters: ERNIE, Grover, Big Bird.
Figure 4. Every token of the sentence, on both sides of the gap, feeds the position where the word is missing, and the model restores it from all of them.
Every layer of the model therefore draws on both sides at once. The
architecture underneath makes that
possible (see also the Attention & transformers chapter) (voir aussi le chapitre Attention et transformeurs).
BERT reported new best results on eleven language-processing tasks, and this
methodology became the standard: pretrain one model on raw text, then fine-tune
it for each task. For translation, where the
whole source text is there before any output is produced, reading it in both
directions is the natural design.
What it costs
Two things.
Computation. A fresh vector per occurrence, from the whole sentence, costs
far more than looking up a stored one, so these models need serious hardware.
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019). BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers). https://doi.org/10.18653/v1/N19-1423
Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., et al. (2018). Deep Contextualized Word Representations. Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers). https://doi.org/10.18653/v1/N18-1202
Avant ou après
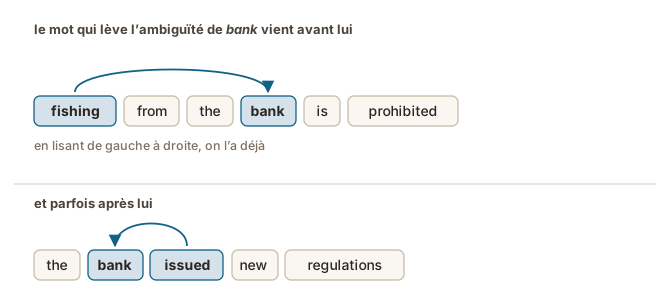
Où se trouve le mot qui lève l’ambiguïté ? Parfois avant le mot ambigu : dans
fishing from the bank is prohibited, fishing a déjà fixé le sens quand
bank arrive. Parfois après lui : dans the bank issued new regulations, le
mot décisif ne vient qu’une fois bank lu.
Figure 3. Le mot qui lève une ambiguïté vient avant elle dans une phrase et après elle dans l'autre. Un modèle qui lit strictement de gauche à droite n'a que la moitié de ce contexte.
Lire dans les deux sens
ELMo utilisait déjà les deux côtés, mais superficiellement : un modèle lisait
la phrase de gauche à droite, un second la lisait de droite à gauche, et leurs
sorties étaient réunies à la fin, si bien que les deux sens ne se rencontraient
jamais pendant l’entraînement (Devlin et al., 2019).
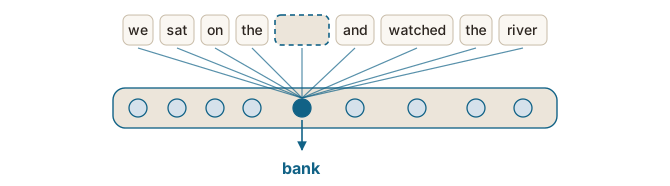
BERT est le modèle qui a réuni les deux.ELMo et BERT ont lancé une
mode, et les acronymes qui ont suivi ont été tordus pour tomber sur des
personnages de Sesame Street : ERNIE, Grover, Big Bird.
Figure 4. Chaque jeton de la phrase, des deux côtés du trou, alimente la position où le mot manque, et le modèle le rétablit à partir de tous.
Chaque couche du modèle puise donc des deux côtés à la fois. L’architecture
sous-jacente rend cela
possible (see also the Attention & transformers chapter) (voir aussi le chapitre Attention et transformeurs).
BERT a établi de nouveaux records sur onze tâches de traitement
de la langue, et cette méthodologie est devenue la norme : préentraîner un
modèle sur du texte brut, puis l’affiner pour chaque tâche. En traduction, où
tout le texte de départ est là avant qu’aucune sortie ne soit produite, le lire
dans les deux sens est la conception naturelle.
Ce que cela coûte
Deux choses.
Le calcul. Un vecteur neuf par occurrence, à partir de toute la phrase,
coûte bien plus cher que d’en consulter un déjà rangé : ces modèles exigent
donc du matériel sérieux.
Le domaine a jugé que la précision valait les deux.
Sources
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019). BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers). https://doi.org/10.18653/v1/N19-1423
Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., et al. (2018). Deep Contextualized Word Representations. Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers). https://doi.org/10.18653/v1/N18-1202
Using a pretrained modelUtiliser un modèle préentraîné
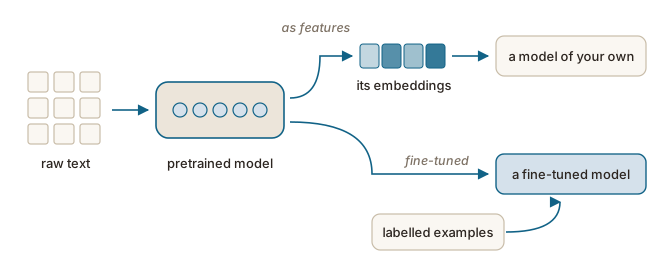
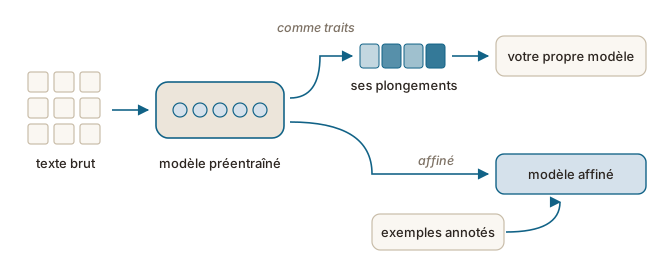
Its embeddings can be taken as they are and fed into a model of your own, which
is how ELMo was used. Or the whole model can be kept and fine-tuned: a small
output layer is added and trained on labelled examples for one task, so that
what the model learned about language carries over to it (Devlin et al.,
2019) (see also the Fine-tuning chapter, in the LLM lifecycle module) (voir aussi le chapitre Affinage, dans le module Cycle de vie des GML). Sentiment analysis,
named-entity recognition and question answering were all built that way, and
the task-specific training is small beside the pretraining.
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019). BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers). https://doi.org/10.18653/v1/N19-1423
Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., et al. (2018). Deep Contextualized Word Representations. Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers). https://doi.org/10.18653/v1/N18-1202
Attention & transformersAttention et transformeurs
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
The bottleneckLe goulot d'étranglement
Context matters
Texts are full of context-dependent choices and interpretations, at every
scale:
the word that settles an ambiguity, thirty words earlier in the same sentence;
the latter, referring to something named three sentences ago;
a pronoun pointing back two paragraphs;
a term defined in the introduction and used throughout.
One pass, and no going back
Before the transformer, a model read a sentence the way it arrives: one word at
a time, updating a running summary as it went. ELMo was still built that way in
2018, with two passes over the sentence, each of them one word at a time
(Peters et al., 2018).
That sounds natural, because it is how you read too. You commit as you go, and
a later word sometimes breaks the reading you committed to: the horse raced
past the barn fell sends you back to the beginning. Sentences like that are
called garden-path sentences, tricking you into one reading at the beginning
and making you reconsider at the end. Without the ability to go backwards,
models would not be able to deal with this.
Processing one word at a time in order has a structural weakness as well.
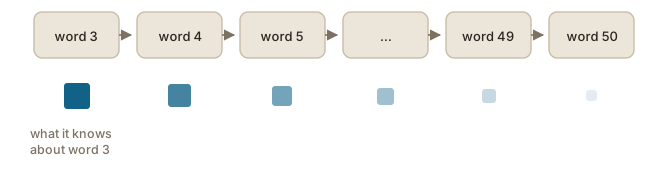
Everything the model knows about word 3 has to survive, inside that running
summary, through the processing of words 4, 5 and 6 to matter at word 50. Each step blurs it a little, like a game of broken
telephone.A party game: one player whispers a phrase to the next
along a line, each passing on what they think they heard, and the last says
aloud what reached them. Over a short span the message arrives; over
a long one what arrives is a paraphrase of a paraphrase.
Figure 1. Word 3 reaching word 50 through every step in between.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Maruf, S., Saleh, F., & Haffari, G. (2021). A survey on document-level neural machine translation: Methods and evaluation. ACM Computing Surveys, 54(2), article 45. https://doi.org/10.1145/3441691
Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., et al. (2018). Deep Contextualized Word Representations. Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers). https://doi.org/10.18653/v1/N18-1202
Voita, E., Sennrich, R., & Titov, I. (2019). When a good translation is wrong in context: Context-aware machine translation improves on deixis, ellipsis, and lexical cohesion. Proceedings of the 57th Annual Meeting of the ACL, 1198–1212. https://aclanthology.org/P19-1116/
Le contexte compte
Les textes sont pleins de choix et d’interprétations qui dépendent du contexte,
à toutes les échelles :
le mot qui lève une ambiguïté, trente mots plus tôt dans la même phrase ;
ce dernier, qui renvoie à quelque chose nommé trois phrases plus haut ;
un pronom qui renvoie deux paragraphes en arrière ;
un terme défini dans l’introduction et employé partout ensuite.
Un seul passage, sans retour
Avant le transformeur, un modèle lisait une phrase telle qu’elle arrive : un
mot à la fois, en mettant à jour un résumé courant à mesure. ELMo était encore
construit ainsi en 2018, avec deux passages sur la phrase, chacun un mot à la
fois (Peters et al., 2018).
Cela paraît naturel, parce que c’est aussi votre façon de lire. Vous vous
engagez à mesure, et un mot plus loin brise parfois la lecture à laquelle vous
vous étiez engagé : the horse raced past the barn fell vous renvoie au début.
On appelle ces phrases des phrases-pièges : elles vous entraînent vers une
première lecture, puis vous forcent à revenir sur elle à la fin. Sans la
possibilité de revenir en arrière, les modèles ne sauraient pas s’en tirer.
Traiter un mot à la fois, dans l’ordre, a aussi une faiblesse structurelle.
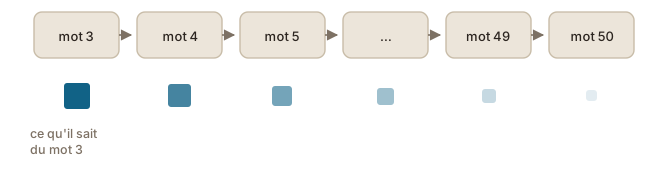
Tout ce que le modèle sait du mot 3 doit survivre, dans ce résumé courant, au
traitement des mots 4, 5 et 6 pour compter encore au mot 50. Chaque étape le
brouille un peu, comme au téléphone
arabe.Un jeu de société : un joueur chuchote une phrase au suivant le
long d’une file, chacun transmet ce qu’il croit avoir entendu, et le dernier
dit à voix haute ce qui lui est parvenu. Sur une courte distance, le
message arrive ; sur une longue, il n’arrive plus que la paraphrase d’une
paraphrase.
Figure 1. Le mot 3 atteignant le mot 50 en passant par toutes les étapes intermédiaires.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Maruf, S., Saleh, F., & Haffari, G. (2021). A survey on document-level neural machine translation: Methods and evaluation. ACM Computing Surveys, 54(2), article 45. https://doi.org/10.1145/3441691
Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., et al. (2018). Deep Contextualized Word Representations. Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers). https://doi.org/10.18653/v1/N18-1202
Voita, E., Sennrich, R., & Titov, I. (2019). When a good translation is wrong in context: Context-aware machine translation improves on deixis, ellipsis, and lexical cohesion. Proceedings of the 57th Annual Meeting of the ACL, 1198–1212. https://aclanthology.org/P19-1116/
All words at onceTous les mots à la fois
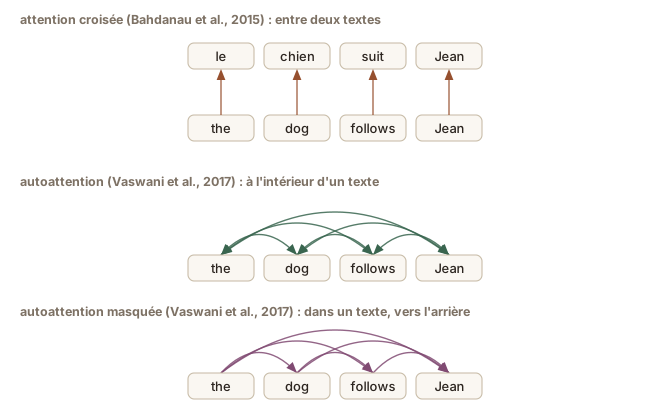
Attention is all you need
The 2017 paper that changed the field has its thesis in its title: “Attention
Is All You Need” (Vaswani et al., 2017). The architecture it introduced, the
transformer, drops reading order entirely. All the words of the input are
processed at the same time, and each word can draw information directly from
any other, whatever the distance between them. The first word of a long sentence no
longer has to survive a relay to reach the last: the two are one connection
apart.
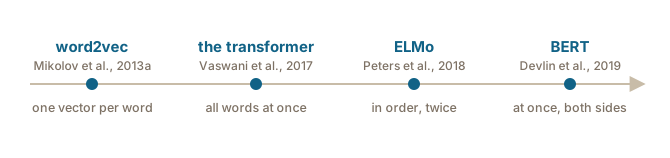
Figure 2. The order they arrived in. ELMo came after the transformer without using it; BERT is built on it, which is how it reads a whole sentence at once.
What about word order?
Dropping sequence creates an obvious problem. If nothing is processed “first”,
how does the model know that the dog follows Jean differs from Jean follows
the dog? The words alone no longer say.
The transformer’s answer is to make position part of each word’s
representation. Before processing starts, every word’s vector is combined with
a numerical encoding of where in the text it sits, like page numbers on a
manuscript that has been taken apart: the pages can then be handled in any
order without the original arrangement being lost.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 3. The sentence arrives in order, each word is given its position, and from then on the arrangement no longer keeps that order: only the positional encoding remembers it, while the words are processed all at once, each connected to every other.
Sources
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019). BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers). https://doi.org/10.18653/v1/N19-1423
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013a). Efficient Estimation of Word Representations in Vector Space. arXiv preprint arXiv:1301.3781 (ICLR 2013 Workshop Track). https://arxiv.org/abs/1301.3781
Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., et al. (2018). Deep Contextualized Word Representations. Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers). https://doi.org/10.18653/v1/N18-1202
L’article de 2017 qui a changé le domaine annonce sa thèse dans son titre :
« Attention Is All You Need » (Vaswani et al., 2017). L’architecture qu’il
présente, le transformeur, abandonne complètement l’ordre de lecture. Tous les
mots de l’entrée sont traités en même temps, et chaque mot peut puiser de
l’information directement dans n’importe quel autre, quelle que soit la
distance. Le premier mot d’une longue phrase n’a plus à survivre à une course
de relais pour atteindre le dernier : les deux sont à une seule connexion l’un
de l’autre.
Figure 2. L'ordre dans lequel ils sont arrivés. ELMo vient après le transformeur sans s'en servir ; BERT est construit sur lui, et c'est ainsi qu'il lit une phrase entière d'un coup.
Et l’ordre des mots ?
Abandonner la séquence crée un problème évident. Si rien n’est traité « en
premier », comment le modèle sait-il que le chien suit Jean diffère de Jean
suit le chien ? Les mots seuls ne le disent plus.
La réponse du transformeur est de faire de la position une partie de la
représentation de chaque mot. Avant que le traitement commence, le vecteur de
chaque mot est combiné à un encodage numérique de sa place dans le texte, comme
des numéros de page sur un manuscrit qu’on a défait : les pages peuvent ensuite
être manipulées dans n’importe quel ordre sans que l’agencement d’origine soit
perdu.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 3. La phrase arrive dans l'ordre, chaque mot reçoit sa position, et à partir de là l'agencement ne conserve plus cet ordre : seul l'encodage positionnel s'en souvient, tandis que les mots sont traités tous à la fois, chacun relié à tous les autres.
Sources
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019). BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers). https://doi.org/10.18653/v1/N19-1423
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013a). Efficient Estimation of Word Representations in Vector Space. arXiv preprint arXiv:1301.3781 (ICLR 2013 Workshop Track). https://arxiv.org/abs/1301.3781
Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., et al. (2018). Deep Contextualized Word Representations. Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers). https://doi.org/10.18653/v1/N18-1202
Reading in both directions settled one question, whether the word that decides
comes before or after (see also the Contextual embeddings chapter) (voir aussi le chapitre Plongements contextuels).
It leaves another. Once every word is connected to every other, not all of
those connections are worth the same, and the more context there is, the less
of it counts equally.
Reading the bank was steep, you connect bank with steep and settle on the
riverside sense without noticing you did it. The attention mechanism is the
transformer’s version of that reflex: for each word, attention weights say how
much every other word in the text should influence its representation.
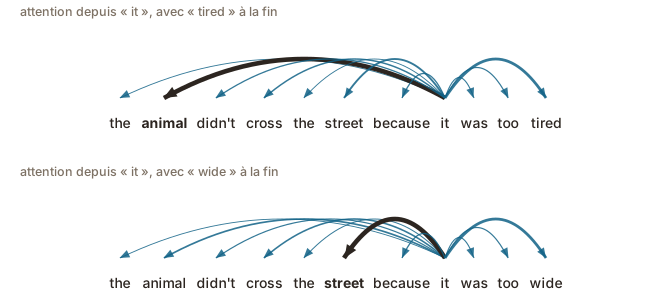
Too tired, too wide
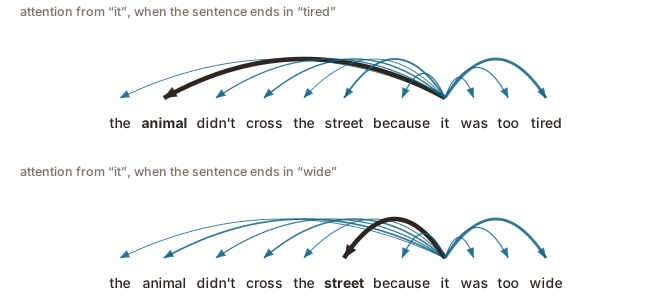
The classic demonstration comes from the transformer paper itself (Vaswani et
al., 2017; visualization by Vig, 2019). Compare:
the animal didn’t cross the street because it was too tired
the animal didn’t cross the street because it was too wide
Changing a single word at the very end changes the meaning of the whole
sentence, by changing which word we link it to: a tired it is the animal, a
wide it is the street. Inside a trained transformer, the attention weights
from it visibly shift between the two sentences, toward animal in the first
and toward street in the second.
Figure 4. Attention from the pronoun to every word of the sentence, thicker where the weight is higher. One changed word at the end moves the heaviest arc from the animal to the street. Drawn after the visualization in Vig (2019).
Nobody programmed the fact that streets are wide and animals get tired. That
came out of patterns across millions of sentences: the distributional idea
again, now applied to relationships inside a sentence rather than to which
words resemble each other.
Learned once, worked out every time
Two different things are called weights here, and they are worth telling
apart.
The attention weights are worked out. They say how much each word of the
text at hand should draw on each other word. The model computes them from
those words, using the weights it learned, and computes them again for the
next text. Nothing about the model changes while it does.
So the arcs in the figure above were not stored anywhere and looked up. They
were computed for that sentence, and the other sentence gives other arcs.
This is the machinery the contextual-embeddings chapter left unexplained: the
vector for this occurrence of bank is assembled from the words its attention
selected, in the proportions it
learned (see also the Contextual embeddings chapter) (voir aussi le chapitre Plongements contextuels).
So what is self-attention?
Attention always runs between two sets of words: the ones being given a
representation, and the ones they draw on. Self-attention is the case where
both sets are the same text. That happens everywhere above, each word
of the sentence weighted against the other words of that same sentence.
The other case runs between two different texts, a source and the translation
being written from
it (see also the Encoders and decoders page) (voir aussi la page Encodeurs et décodeurs).
That use came first: attention was built for translation (Bahdanau et al.,
2015), and the step taken in 2017 was to use it inside a single text as well
(Vaswani et al., 2017).
Figure 5. The same mechanism in the three configurations a translator is likely to come across, in the order they appeared. Each keeps its colour wherever it turns up again. Others exist and are left aside here.
Bahdanau, D., Cho, K., & Bengio, Y. (2015). Neural Machine Translation by Jointly Learning to Align and Translate. Third International Conference on Learning Representations (ICLR 2015), oral presentation; arXiv:1409.0473. https://arxiv.org/abs/1409.0473
Vig, J. (2019). A Multiscale Visualization of Attention in the Transformer Model. Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics: System Demonstrations, 37–42. https://aclanthology.org/P19-3007/
Mais quel contexte ?
Lire dans les deux sens a réglé une question, celle de savoir si le mot décisif
vient avant ou après (see also the Contextual embeddings chapter) (voir aussi le chapitre Plongements contextuels).
Il en reste une autre. Dès que chaque mot est relié à tous les autres, toutes
ces liaisons ne valent pas la même chose, et plus il y a de contexte, moins toutes ses
parties comptent autant.
En lisant the bank was steep, vous rapprochez bank de steep et vous
retenez le sens du bord de rivière sans vous en apercevoir. Le mécanisme
d’attention est la version qu’en donne le transformeur : pour chaque mot, des
poids d’attention disent à quel point chacun des autres mots du texte doit
influencer sa représentation.
Trop fatigué, trop large
La démonstration classique vient de l’article même du transformeur (Vaswani et
al., 2017 ; visualisation de Vig, 2019). Comparez :
the animal didn’t cross the street because it was too tired
the animal didn’t cross the street because it was too wide
Changer un seul mot tout à la fin change le sens de la phrase entière, en
changeant le mot auquel on rattache it : un it fatigué est l’animal, un
it large est la rue. Dans un transformeur entraîné, les poids d’attention
depuis it se déplacent visiblement entre les deux phrases, vers animal dans
la première et vers street dans la seconde.
Figure 4. L'attention depuis le pronom vers chaque mot de la phrase, plus épaisse là où le poids est plus élevé. Un seul mot changé à la fin déplace l'arc le plus épais de l'animal vers la rue. D'après la visualisation de Vig (2019).
Personne n’a programmé le fait que les rues sont larges et que les animaux se
fatiguent. Cela est ressorti de motifs relevés dans des millions de phrases :
l’idée distributionnelle de nouveau, appliquée cette fois aux relations à
l’intérieur d’une phrase plutôt qu’à la ressemblance entre les mots.
Appris une fois, établi chaque fois
Deux choses différentes s’appellent ici des poids, et elles valent la peine
d’être distinguées.
Les poids d’attention sont établis. Ils disent à quel point chaque mot du
texte en cours doit puiser dans chacun des autres. Le modèle les calcule à
partir de ces mots, avec les poids qu’il a appris, et les calcule de nouveau
pour le texte suivant. Rien du modèle ne change pendant ce temps.
Les arcs de la figure ci-dessus n’étaient donc rangés nulle part avant d’être
consultés. Ils ont été calculés pour cette phrase, et l’autre phrase donne
d’autres arcs.
C’est le mécanisme que le chapitre sur les plongements contextuels laissait
inexpliqué : le vecteur de cette occurrence de bank est assemblé à partir des
mots que son attention a retenus, dans les proportions
apprises (see also the Contextual embeddings chapter) (voir aussi le chapitre Plongements contextuels).
Alors, qu’est-ce que l’autoattention ?
L’attention s’exerce toujours entre deux ensembles de mots : ceux à qui l’on donne
une représentation, et ceux dans lesquels ils puisent. L’autoattention est le
cas où les deux ensembles sont le même texte. C’est ce qui se passe partout
ci-dessus, chaque mot de la phrase pesé par rapport aux autres mots de cette
même phrase.
Dans l’autre cas, elle s’exerce entre deux textes différents, un texte de départ et la
traduction qu’on en
écrit (see also the Encoders and decoders page) (voir aussi la page Encodeurs et décodeurs).
Cet usage est venu le premier : l’attention a été conçue pour la traduction
(Bahdanau et al., 2015), et le pas franchi en 2017 a été de s’en servir aussi à
l’intérieur d’un seul texte (Vaswani et al., 2017).
Figure 5. Le même mécanisme dans les trois configurations qu'une traductrice ou un traducteur est susceptible de rencontrer, dans l'ordre de leur apparition. Chacune garde sa couleur partout où elle réapparaît. D'autres existent et sont laissées de côté ici.
Bahdanau, D., Cho, K., & Bengio, Y. (2015). Neural Machine Translation by Jointly Learning to Align and Translate. Third International Conference on Learning Representations (ICLR 2015), oral presentation; arXiv:1409.0473. https://arxiv.org/abs/1409.0473
Vig, J. (2019). A Multiscale Visualization of Attention in the Transformer Model. Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics: System Demonstrations, 37–42. https://aclanthology.org/P19-3007/
The encoder takes the source and turns it into contextual
representations, all words at the same time.
The decoder writes the target one word at a time, and at each word it
looks in two directions: back over what it has already written, and across at
the encoder’s representations of the source.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 6. Simplified schematic of an encoder-decoder mechanism, illustrated with a translation task.
Figure 6figure 6 follows
one sentence through both halves, le chien suit Jean becoming the dog
follows Jean, caught at the moment the decoder produces follows. Training is
over by then, so the figure shows one pass through a finished
model (see also the Attention page) (voir aussi la page L'attention).
Training a translation model in the first place is a subject of its
own (see also the What machine translation is chapter, in the Machine translation module) (voir aussi le chapitre Qu'est-ce que la traduction automatique, dans le module Traduction automatique).
Back, with masked self-attention. That same vector also draws on what the
decoder has already written, the and dog. The fourth slot is empty,
because the words after the one being produced do not exist yet, so attention
over the target runs backwards only.
Out of the decoder. The finished vector is mapped back to a word.
Direction belongs to the attention, not to the turning of words into vectors
and back.
Encoder, decoder, or both?
Both halves are made of the same attention layers, so a model can keep one or
keep both. The choice follows from the shape of the task: what goes in,
and what has to come out.
The line is not a wall. A decoder-only model translates perfectly well when
the source and its translation are given to it as one running text, which
happens whenever a translation is asked of a
chatbot (see also the Machine translation module) (voir aussi le module Traduction automatique).
Sources
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019). BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers). https://doi.org/10.18653/v1/N19-1423
Radford, A., Kim, J. W., Xu, T., Brockman, G., McLeavey, C., & Sutskever, I. (2023). Robust speech recognition via large-scale weak supervision. Proceedings of the 40th International Conference on Machine Learning (PMLR 202), 28492–28518. https://proceedings.mlr.press/v202/radford23a.html
L’encodeur prend le texte de départ et le transforme en représentations
contextuelles, tous les mots en même temps.
Le décodeur écrit le texte d’arrivée un mot à la fois, et à chaque mot il
regarde dans deux directions : en arrière sur ce qu’il a déjà écrit, et de
l’autre côté vers les représentations du texte de départ produites par
l’encodeur.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 6. Schéma simplifié d'un mécanisme encodeur-décodeur, illustré par une tâche de traduction.
La Figure 6figure 6 suit
une phrase à travers les deux moitiés, le chien suit Jean devenant the dog
follows Jean, saisie au moment où le décodeur produit follows.
L’entraînement est terminé à ce stade : la figure montre donc un seul passage
dans un modèle
achevé (see also the Attention page) (voir aussi la page L'attention).
L’entraînement d’un modèle de traduction est un sujet à part
entière (see also the What machine translation is chapter, in the Machine translation module) (voir aussi le chapitre Qu'est-ce que la traduction automatique, dans le module Traduction automatique).
En arrière, avec l’autoattention masquée. Ce même vecteur puise aussi
dans ce que le décodeur a déjà écrit, the et dog. La quatrième place est
vide, parce que les mots qui suivent celui qu’on produit n’existent pas
encore : l’attention sur le texte d’arrivée ne va donc que vers l’arrière.
Hors du décodeur. Le vecteur terminé est ramené à un mot.
La direction appartient à l’attention, non au passage des mots aux vecteurs et
des vecteurs aux mots.
Encodeur, décodeur ou les deux ?
Les deux moitiés sont faites des mêmes couches d’attention : un modèle peut
donc n’en garder qu’une, ou garder les deux. Le choix découle de la forme de la
tâche : ce qui entre, et ce qui doit sortir.
La frontière n’est pas un mur. Un modèle à décodeur seul traduit très bien
quand le texte de départ et sa traduction lui sont donnés comme un seul texte
courant, ce qui arrive chaque fois qu’on demande une traduction à un agent
conversationnel (see also the Machine translation module) (voir aussi le module Traduction automatique).
Sources
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019). BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers). https://doi.org/10.18653/v1/N19-1423
Radford, A., Kim, J. W., Xu, T., Brockman, G., McLeavey, C., & Sutskever, I. (2023). Robust speech recognition via large-scale weak supervision. Proceedings of the 40th International Conference on Machine Learning (PMLR 202), 28492–28518. https://proceedings.mlr.press/v202/radford23a.html
Scale and the context windowL'échelle et la fenêtre contextuelle
Why “large” starts here
The transformer improved quality, and the deeper change was economic. A
sequential model processes words like customers in a single queue: one at a
time, however fast each step is. A transformer opens every checkout lane at
once, which is exactly the workload graphics processors are built for.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 7. Left, each step feeds the next, so the words are worked through in order. Right, nothing waits: every word is worked on in the same step, and every word is connected to every other.
Training on text collections that were unthinkably large in 2016 became
routine within a few years, and model and data sizes grew by orders of
magnitude (Hoffmann et al., 2022). Every system in the LLM lifecycle module is
a transformer at heart (see also the LLM lifecycle module) (voir aussi le module Cycle de vie des GML); without parallel
processing, “large” would have stayed out of reach.
The cost of attention
Attention weighs every pair of words, so doubling the length of a text roughly
quadruples the work. Somewhere, every model has to cap how much text it
processes at once, and that cap is the context window: the
reason a chatbot loses the thread of a long conversation, and the reason
“translate this 200-page document in one go” is not how any of these systems
works (see also the Counting in tokens page) (voir aussi la page Compter en jetons).
Le transformeur a amélioré la qualité, et le changement le plus profond a été
économique. Un modèle séquentiel traite les mots comme des clients dans une
seule file : un à la fois, aussi rapide que soit chaque étape. Un transformeur
ouvre toutes les caisses en même temps, ce qui est exactement la charge de
travail pour laquelle les processeurs graphiques sont faits.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 7. À gauche, chaque étape alimente la suivante : les mots sont donc traités dans l'ordre. À droite, rien n'attend : tous les mots sont traités à la même étape, et chaque mot est relié à tous les autres.
Entraîner sur des ensembles de textes d’une taille inimaginable en 2016 est devenu courant
en quelques années, et la taille des modèles comme celle des données ont
augmenté de plusieurs ordres de grandeur (Hoffmann et al., 2022). Tous les
systèmes du module sur le cycle de vie des GML sont des transformeurs au
fond (see also the LLM lifecycle module) (voir aussi le module Cycle de vie des GML) ; sans le traitement parallèle, le « grand »
serait resté hors de portée.
Le coût de l’attention
L’attention pèse chaque paire de mots : doubler la longueur d’un texte
quadruple donc à peu près le travail. Chaque modèle doit plafonner quelque part
la quantité de texte qu’il traite d’un coup, et ce plafond est la fenêtre
contextuelle : la raison pour laquelle un agent conversationnel perd le fil
d’une longue conversation, et la raison pour laquelle « traduis-moi ce document
de 200 pages d’un coup » n’est pas la façon dont ces systèmes
fonctionnent (see also the Counting in tokens page) (voir aussi la page Compter en jetons).
The impact on machine translationL'incidence sur la traduction automatique
Read before you translate
When you translate, you need context before you can commit. You cannot start
rendering a sentence on its first word: you read ahead, a few words at least,
to see where it is going. Consider for instance the English-to-French
translation in Figure 8figure 8.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 8. Word by word, English on the left and French on the right. Three choices have to be made before the word that settles them arrives.
Nobody gave the model that map. It worked it out from millions of translated
sentence pairs, four and a half million for the English-German system of the
original paper (Vaswani et al., 2017).
Voita, E., Sennrich, R., & Titov, I. (2019). When a good translation is wrong in context: Context-aware machine translation improves on deixis, ellipsis, and lexical cohesion. Proceedings of the 57th Annual Meeting of the ACL, 1198–1212. https://aclanthology.org/P19-1116/
Lire avant de traduire
Quand vous traduisez, il vous faut du contexte avant de pouvoir vous engager.
Vous ne pouvez pas commencer à rendre une phrase dès son premier mot : vous
lisez plus loin, quelques mots au moins, pour voir où elle va. Prenez par
exemple la traduction de l’anglais vers le français de la
Figure 8figure 8.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 8. Mot à mot, l'anglais à gauche et le français à droite. Trois choix doivent être faits avant que le mot qui les règle arrive.
Personne n’a donné cette carte au modèle. Il l’a établie à partir de millions
de paires de phrases traduites, quatre millions et demi pour le système
anglais-allemand de l’article d’origine (Vaswani et al., 2017).
Voita, E., Sennrich, R., & Titov, I. (2019). When a good translation is wrong in context: Context-aware machine translation improves on deixis, ellipsis, and lexical cohesion. Proceedings of the 57th Annual Meeting of the ACL, 1198–1212. https://aclanthology.org/P19-1116/
TokenizationJetonisation
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
What are tokens?Qu'est-ce qu'un jeton ?
Not words, but tokens
Everything so far has said word: a vector for each word, attention between
words. That is a simplification.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 1. The same sentence read three ways. The token split and IDs are the real output of OpenAI's o200k_base tokenizer (checked 29 August 2026).
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Pas des mots, mais des jetons
Tout ce qui précède a dit mot : un vecteur par mot, de l’attention entre les
mots. C’est une simplification.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 1. La même phrase lue de trois façons. Le découpage en jetons et les identifiants sont la sortie réelle du segmenteur o200k_base d'OpenAI (vérifiée le 29 août 2026).
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 2. From your sentence to the vectors the model works on. The split shown is real o200k_base output (tiktokenizer.vercel.app, checked 29 August 2026).
Spaces belong to the word that follows
The spaces are inside the tokens. In this tokenizer a space belongs to the word
that follows it, which is why two of the boxes carry one and the first does
not. The same word is therefore a different token at the start of a line and in
the middle of a sentence, and a text already cut on its spaces is counted
differently.
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 2. De votre phrase aux vecteurs sur lesquels le modèle travaille. Le découpage montré est la sortie réelle d'o200k_base (tiktokenizer.vercel.app, vérifiée le 29 août 2026).
Les espaces appartiennent au mot qui suit
Les espaces sont à l’intérieur des jetons. Dans ce segmenteur, une espace
appartient au mot qui la suit, ce qui explique que deux des cases en portent
une et que la première n’en porte pas. Un même mot est donc un jeton différent
au début d’une ligne et au milieu d’une phrase, et un texte déjà découpé sur
ses espaces se compte autrement.
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Why not simply use words or characters?Pourquoi ne pas simplement prendre les mots ou les caractères ?
Vocabulary
Every model has a fixed list of tokens, chosen before training starts and never
added to afterwards. Every text it will ever read or write has to be expressed
using the tokens in that list, and whatever is not in the list cannot be
represented at all.
How long that list should be is the question this page turns on, and the two
obvious answers sit at either end.
Figure 3. The two obvious answers, and what is wrong with each. Image generated withImage générée avec Gemini.
One number per word?
Each token would then be a unit that means something. But a list of words runs
into three walls at once.
Rare entries stay poorly learned. A word seen a handful of times in
training gets a vector built from those few occurrences, which is not enough
to place it usefully. Enlarging the list adds entries of exactly that kind.
Every entry costs. The model keeps one row of numbers per entry, and at
every step it scores every entry in the list to decide what comes next. A
longer list means more memory and more computing, for entries that are
mostly rare.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 4. A vocabulary of whole words: a vector is learned for each word the text contained, and none for the word it never contained.
One number per character?
The list would be tiny, a few hundred entries at most, and nothing would ever
be missing: any text at all can be spelled out, in any language, typos
included. The cost is at the other end. A single character tells you almost
nothing, t on its own means nothing, and a page of text becomes a very
long run of them, as the character row of
Figure 1figure 1 shows.
The model would have to rebuild every word from scratch, every time one occurred.
Pieces in between
New words are mostly made of familiar pieces, and that is the way out. You can
read antibacterial without having seen it before, because anti-, bacteri
and -al are old acquaintances. A vocabulary of pieces, some of them whole
words and some fragments, keeps the common words whole and can still spell out
anything at all, down to single characters in the worst case.
Figure 5. The same phrase represented with four different types of vocabulary, rated for the size of the list, the risk of a word falling outside it, and how much a single token tells you.
Brysbaert, M., Stevens, M., Mandera, P., & Keuleers, E. (2016). How Many Words Do We Know? Practical Estimates of Vocabulary Size Dependent on Word Definition, the Degree of Language Input and the Participant's Age. Frontiers in Psychology, 7, 1116. https://doi.org/10.3389/fpsyg.2016.01116
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Le vocabulaire
Chaque modèle a une liste fixe de jetons, choisie avant le début de
l’entraînement et jamais complétée ensuite. Tout texte qu’il lira ou écrira
doit s’exprimer avec les jetons de cette liste, et ce qui n’y figure pas ne
peut pas être représenté du tout.
Quelle doit être la longueur de cette liste ? C’est la question qui occupe cette
page, et les deux réponses évidentes se trouvent aux deux extrémités.
Figure 3. Les deux réponses évidentes, étiquetées en anglais, et ce qui ne va pas avec chacune. Image generated withImage générée avec Gemini.
Un numéro par mot ?
Chaque jeton serait alors une unité qui veut dire quelque chose. Mais une liste
de mots se heurte à trois murs à la fois.
Les entrées rares restent mal apprises. Un mot vu une poignée de fois à
l’entraînement reçoit un vecteur construit sur ces quelques occurrences, ce
qui ne suffit pas à le placer utilement. Agrandir la liste ajoute des entrées
exactement de ce genre.
Chaque entrée coûte. Le modèle garde une rangée de nombres par entrée,
et à chaque étape il attribue un score à chaque entrée de la liste pour
décider de la suite. Une liste plus longue veut dire plus de mémoire et plus
de calcul, pour des entrées le plus souvent rares.
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 4. Un vocabulaire de mots entiers : un vecteur est appris pour chaque mot que le texte contenait, et aucun pour le mot qu'il n'a jamais contenu.
Un numéro par caractère ?
La liste serait minuscule, quelques centaines d’entrées au plus, et rien ne
manquerait jamais : n’importe quel texte peut s’épeler, dans n’importe quelle
langue, coquilles comprises. Le coût est à l’autre bout. Un caractère isolé ne
dit presque rien, t tout seul ne veut rien dire, et une page de texte devient
une très longue suite de caractères, comme le montre la rangée des caractères
de la
Figure 1figure 1. Le
modèle devrait reconstruire chaque mot depuis le début, chaque fois qu’il en
rencontre un.
Des morceaux entre les deux
Les mots nouveaux sont surtout faits de morceaux familiers, et c’est là que se trouve
l’issue. Vous pouvez lire antibactérien sans l’avoir jamais vu, parce que
anti-, bactér et -ien sont de vieilles connaissances. Un vocabulaire de
morceaux, dont certains sont des mots entiers et d’autres des fragments, garde
les mots courants entiers et peut malgré tout épeler n’importe quoi, jusqu’aux caractères
isolés dans le pire des cas.
Figure 5. La même expression représentée avec quatre types de vocabulaire différents, évalués selon la taille de la liste, le risque qu'un mot en sorte, et ce que dit un seul jeton.
Brysbaert, M., Stevens, M., Mandera, P., & Keuleers, E. (2016). How Many Words Do We Know? Practical Estimates of Vocabulary Size Dependent on Word Definition, the Degree of Language Input and the Participant's Age. Frontiers in Psychology, 7, 1116. https://doi.org/10.3389/fpsyg.2016.01116
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Split the whole corpus into single characters. These are the first
tokens.
Count every pair of adjacent tokens, and merge the most frequent pair
into one new token, everywhere it occurs.
Repeat step 2 until the vocabulary reaches the size you chose.
Learned once, applied forever
Frequent words quickly get their own token (the is one of the first) and
rarer ones stay in a few pieces. Length counts as well as frequency: every
merge joins two neighbours, so a long word needs many of them before it is
whole again, and a short word of the same frequency gets there sooner.
Frequent endings and stems, -ing, -tion, get a token too, because they
recur across thousands of words.
The counting happens once and produces a list of merges. That
list is then applied unchanged to every text the model ever reads, including
yours.
Figure 6. Byte-pair encoding runs twice over in two different senses: once as learning, on a corpus, and then as a lookup applied unchanged to everything the model reads.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Sennrich, R., Haddow, B., & Birch, A. (2016). Neural Machine Translation of Rare Words with Subword Units. Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). https://doi.org/10.18653/v1/P16-1162
Découper tout le corpus en caractères isolés. Ce sont les premiers jetons.
Compter chaque paire de jetons voisins, et fusionner la paire la plus
fréquente en un nouveau jeton, partout où elle apparaît.
Répéter l’étape 2 jusqu’à ce que le vocabulaire atteigne la taille choisie.
Appris une fois, appliqué pour toujours
Les mots fréquents obtiennent vite leur propre jeton (le est l’un des
premiers) et les plus rares restent en quelques morceaux. La longueur compte
aussi, en plus de la fréquence : chaque fusion joint deux voisins, un long mot a donc
besoin de nombreuses fusions avant d’être entier de nouveau, et un mot court de
même fréquence y arrive plus tôt. Les terminaisons et les radicaux fréquents,
-ion, -ment, obtiennent aussi un jeton, parce qu’ils reviennent dans des
milliers de mots.
Le comptage n’a lieu qu’une fois et produit une liste de fusions. Cette liste
est ensuite appliquée sans changement à tous les textes que le modèle lira, y
compris les vôtres.
Figure 6. L'encodage par paires d'octets tourne deux fois en deux sens différents : une fois comme apprentissage, sur un corpus, puis comme consultation appliquée sans changement à tout ce que le modèle lit.
Sources
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Sennrich, R., Haddow, B., & Birch, A. (2016). Neural Machine Translation of Rare Words with Subword Units. Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). https://doi.org/10.18653/v1/P16-1162
BPE by handL'encodage par paires d'octets à la main
Counting pairs, one merge at a time
Here the whole training corpus is three words: representation, retention,
repression. Three steps by hand are enough to see what kind of vocabulary
comes out.
Start by splitting everything into characters, nine distinct ones in all:
r e p r e s e n t a t i o nr e t e n t i o nr e p r e s s i o n
Count adjacent pairs. The pair r e occurs five times (twice in
representation, once in retention, twice in repression), more than any
other, so it becomes the first new token:
re p re s e n t a t i o nre t e n t i o nre p re s s i o n
Recounting and merging seven more times, io then ion, then the three
merges that build repres and the two that make ent, leaves a corpus in
which no pair occurs more than once:
repres ent a t ionre t ent ionrepres s ion
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 7. Every merge is chosen by one number, the count of the pair. No step consults a dictionary or a morphological analysis.
Morphemes by accident
Seven tokens (repres, ent, a, t, ion, re, s) now cover all three
words. Counting pairs and nothing else found ion and ent, real English
morphemes, and repres, a shared stem. It also produced
repres·ent·a·t·ion, which no linguist would propose as a morphological
analysis of representation.
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Sennrich, R., Haddow, B., & Birch, A. (2016). Neural Machine Translation of Rare Words with Subword Units. Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). https://doi.org/10.18653/v1/P16-1162
Compter les paires, une fusion à la fois
Ici, tout le corpus d’entraînement tient en trois mots : representation,
retention, repression. Trois étapes à la main suffisent à voir quel genre
de vocabulaire en sort.
On commence par tout découper en caractères, neuf caractères distincts en
tout :
r e p r e s e n t a t i o nr e t e n t i o nr e p r e s s i o n
On compte les paires voisines. La paire r e apparaît cinq fois (deux fois
dans representation, une fois dans retention, deux fois dans
repression), plus que toute autre ; elle devient donc le premier nouveau
jeton :
re p re s e n t a t i o nre t e n t i o nre p re s s i o n
En recomptant et en fusionnant sept fois de plus, io puis ion, puis les
trois fusions qui construisent repres et les deux qui font ent, on obtient
un corpus où aucune paire n’apparaît plus d’une fois :
repres ent a t ionre t ent ionrepres s ion
Click the drawing, or a line below, to build it up stage by stage.Cliquez sur le dessin, ou sur une ligne ci-dessous, pour le construire étape par étape.
Figure 7. Chaque fusion est choisie par un seul nombre, le compte de la paire. Aucune étape ne consulte de dictionnaire ni d'analyse morphologique.
Des morphèmes par accident
Sept jetons (repres, ent, a, t, ion, re, s) couvrent maintenant
les trois mots. Compter les paires et rien d’autre a trouvé ion et ent, de
vrais morphèmes de l’anglais, et repres, un radical commun. Cela a aussi
produit repres·ent·a·t·ion, qu’aucune linguiste ne proposerait comme analyse
morphologique de representation.
Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
Sennrich, R., Haddow, B., & Birch, A. (2016). Neural Machine Translation of Rare Words with Subword Units. Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). https://doi.org/10.18653/v1/P16-1162
Try and compare tokenizersEssayer et comparer des segmenteurs
Paste and look
Any text pasted into a tokenizer comes back split, token by token.
The two screenshots below were taken on 8 September 2026 with GPT-4o selected, and
cropped to the panels that matter. Both the interface and the splits change, so
what you see today may not match them.
Figure 8. One paste, five languages, 180 tokens on GPT-4o. English runs almost word by word; the further down the list, the more the colours cut inside words. Figure 9. The same five paragraphs as the model receives them. The colours above are for you; this is the input.
What you should see
Common English words are one token each, because the merges that build
them ran often enough.
Rare words and typos shatter.Tokenization itself comes out in two or
three pieces, and htis in more.
Other languages cost more tokens for the same sentence, and the further
a language is from the training text, the more it costs.
One vocabulary per model
The vocabulary behind the splitting is a design decision, and it has grown.
GPT-2 worked with 50,257 tokens (Radford et al., 2019); the tokenizers OpenAI
has released since, in its open
tiktoken library, reach roughly 200,000.
Much of that growth went to non-English text: a recent tokenizer keeps whole
many French and Dutch words an older one fragmented. The differences between
languages shrink without disappearing, and they can be
measured (see also the Consequences of tokenization chapter) (voir aussi le chapitre Conséquences de la jetonisation).
Tiktokenizer offers a choice of models, and the most recent OpenAI one it
lists is GPT-4o. That is the tool lagging rather than anything withheld:
tiktoken maps GPT-5 to the same vocabulary as GPT-4o, so the split above is
the current one. Other companies are less open about this than OpenAI.
Anthropic publishes no tokenizer for Claude, only an
endpoint
that reports how many tokens a text costs, so for those models the count can
be checked and the cuts cannot be seen.
Sennrich, R., Haddow, B., & Birch, A. (2016). Neural Machine Translation of Rare Words with Subword Units. Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). https://doi.org/10.18653/v1/P16-1162
Coller un texte et regarder
N’importe quel texte collé dans un segmenteur en ressort découpé, jeton par
jeton.
Les deux captures ci-dessous ont été prises le 8 septembre 2026 avec GPT-4o
sélectionné, et rognées sur les panneaux qui comptent. L’interface comme les
découpages changent : ce que vous verrez aujourd’hui peut ne pas y
correspondre.
Figure 8. Un seul collage, cinq langues, 180 jetons sur GPT-4o. L'anglais avance presque mot à mot ; plus on descend dans la liste, plus les couleurs coupent à l'intérieur des mots. Figure 9. Les mêmes cinq paragraphes tels que le modèle les reçoit. Les couleurs au-dessus sont pour vous ; ceci est l'entrée.
Ce que vous devriez voir
Les mots anglais courants font un jeton chacun, parce que les fusions qui
les construisent ont tourné assez souvent.
Les mots rares et les coquilles éclatent.Tokenization lui-même ressort
en deux ou trois morceaux, et htis en davantage.
Les autres langues coûtent plus de jetons pour la même phrase, et plus
une langue est éloignée des textes d’entraînement, plus elle coûte cher.
Un vocabulaire par modèle
Le vocabulaire derrière le découpage est une décision de conception, et il a
grandi. GPT-2 travaillait avec 50 257 jetons (Radford et al., 2019) ; les
segmenteurs qu’OpenAI a publiés depuis, dans sa bibliothèque ouverte
tiktoken, atteignent environ 200 000.
Une bonne part de cette croissance est allée aux textes non anglais : un
segmenteur récent garde entiers de nombreux mots français et néerlandais qu’un
ancien fragmentait. Les écarts entre les langues se réduisent sans disparaître,
et ils se
mesurent (see also the Consequences of tokenization chapter) (voir aussi le chapitre Conséquences de la jetonisation).
Tiktokenizer propose un choix de modèles, et le plus récent d’OpenAI qu’il
énumère est GPT-4o. C’est l’outil qui est en retard, non quelque chose qu’on
retiendrait : tiktoken associe GPT-5 au même vocabulaire que GPT-4o, si bien
que le découpage ci-dessus est celui d’aujourd’hui. D’autres entreprises sont
moins ouvertes qu’OpenAI là-dessus. Anthropic ne publie aucun segmenteur pour
Claude, seulement un
point d’accès
qui indique combien de jetons coûte un texte : pour ces modèles, le compte se
vérifie et les coupes ne se voient pas.
Sennrich, R., Haddow, B., & Birch, A. (2016). Neural Machine Translation of Rare Words with Subword Units. Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). https://doi.org/10.18653/v1/P16-1162
Consequences of tokenizationConséquences de la jetonisation
Written in English. The French version was automatically generated
and I have not revised it.
Rédigé en anglais. La version française a été
générée automatiquement et je ne l'ai pas révisée.
The token gap between languagesL'écart de jetons entre les langues
Figure 1. One paste, five languages, at Tiktokenizer with GPT-4o's tokenizer on 8 September 2026. The English line runs almost word by word; the further down the list, the more the colours cut inside words.
The sentences in the capture were written with two uncommon words each, so
the gap they show is at the wide end. A longer text gives a smaller one, and
the vocabulary makes a difference too.
As the results in the table show, English always remains considerably
cheaper. Each new vocabulary has narrowed the gap, but none has closed it: under the 2024
vocabulary French still costs 37 % more tokens than English for the same
content, and Shan eight times more. Petrov et al. (2023) also found the gap
in tokenizers that were deliberately trained to be multilingual, so it is
not a quirk of one company’s vocabulary. Nor is the narrowing guaranteed to
continue: OpenAI has not said which vocabulary GPT-6 uses, so as of
11 September 2026 nothing can be measured for it, and a new vocabulary can also
cost more, as Anthropic’s own
documentation
says of the tokenizer introduced with Claude Opus 4.7, which produces about
30 % more tokens than its predecessor on the same text.
The word column shows that part of
the French gap is French itself, which takes more words than English to say
the same thing; the rest is the tokenizer cutting those words into more
pieces. German comes out with slightly fewer words than English because of
how the language is built: where English writes a compound as two or three
words, German writes one, and each of those long words is then cut into
several tokens. Chinese and Shan have no word count at all, because both are
written without spaces between words, so the concept of a “word” is too
different there to be
comparable (see also the Tokenization (including an example of the rule-based approach) chapter, in the Classical NLP module) (voir aussi le chapitre La segmentation en unités lexicales (y compris un exemple d'approche à base de règles), dans le module TAL classique).
Consequences of less efficient tokenization
Petrov et al. (2023) name three consequences, each with a direct impact for
users:
A fourth consequence is not in their list, but has since also been proven:
Quality. A token that is a whole word, or a meaningful piece of one,
gives the model a better unit to build its representations on than a
fragment cut by frequency, so a language whose words are broken into
fragments is harder to learn from. Training the same model with
tokenizers that compress text more or less shows the correlation: the
more compact the tokenization, the better the model performs afterwards,
most clearly on generation tasks (Goldman et al., 2024). The same is true
across languages. Ali et al. (2024) trained the same LLM on English,
German, French, Italian and Spanish twice, once with an English-centric
tokenizer and once with a tokenizer built for all five languages. With
the English-centric tokenizer, the model performed markedly worse in the
four other languages, and its training cost up to 68 % more, because
every non-English text was longer.
Ali, M., Fromm, M., Thellmann, K., Rutmann, R., Lübbering, M., et al. (2024). Tokenizer Choice For LLM Training: Negligible or Crucial?. Findings of the Association for Computational Linguistics: NAACL 2024, 3907–3924. https://aclanthology.org/2024.findings-naacl.247/
Goldman, O., Caciularu, A., Eyal, M., Cao, K., Szpektor, I., & Tsarfaty, R. (2024). Unpacking Tokenization: Evaluating Text Compression and its Correlation with Model Performance. Findings of the Association for Computational Linguistics: ACL 2024, 2274–2286. https://aclanthology.org/2024.findings-acl.134/
NLLB Team, Costa-jussà, M. R., Cross, J., Çelebi, O., Elbayad, M., et al. (2024). Scaling neural machine translation to 200 languages. Nature, 630, 841–846. https://doi.org/10.1038/s41586-024-07335-x
Figure 1. Un seul collage, cinq langues, à Tiktokenizer avec le segmenteur de GPT-4o, le 8 septembre 2026. La ligne anglaise avance presque mot par mot ; plus on descend dans la liste, plus les couleurs coupent à l'intérieur des mots.
Les phrases de la capture ont été écrites avec deux mots peu courants chacune,
de sorte que l’écart qu’elles montrent est dans le haut de la fourchette. Un
texte plus long en donne un plus petit, et le vocabulaire fait aussi une
différence.
Comme le montrent les résultats du tableau, l’anglais reste toujours nettement
moins cher. Chaque nouveau vocabulaire a réduit l’écart, mais aucun ne l’a
comblé : sous le vocabulaire de 2024, le français coûte encore 37 % de jetons
de plus que l’anglais pour le même contenu, et le shan huit fois plus. Petrov
et al. (2023) ont aussi trouvé l’écart dans des segmenteurs entraînés
délibérément pour être multilingues ; ce n’est donc pas une particularité du
vocabulaire d’une seule entreprise. Rien ne garantit non plus que le
rétrécissement continue : OpenAI n’a pas dit quel vocabulaire GPT-6 utilise,
si bien qu’au 11 septembre 2026 rien ne peut être mesuré pour lui, et un nouveau
vocabulaire peut aussi coûter plus cher, comme la
documentation
d’Anthropic le dit du segmenteur introduit avec Claude Opus 4.7, qui produit
environ 30 % de jetons de plus que son prédécesseur sur le même texte.
La colonne des mots montre qu’une partie de l’écart du français tient au
français lui-même, qui prend plus de mots que l’anglais pour dire la même
chose ; le reste vient du segmenteur, qui découpe ces mots en plus de
morceaux. L’allemand ressort avec un peu moins de mots que l’anglais à cause
de la façon dont la langue est construite : là où l’anglais écrit un mot
composé en deux ou trois mots, l’allemand en écrit un seul, et chacun de ces
longs mots est ensuite découpé en plusieurs jetons. Le chinois et le shan
n’ont pas de compte de mots du tout, parce que les deux s’écrivent sans espaces
entre les mots, de sorte que la notion de « mot » y est trop différente pour
être comparable (see also the Tokenization (including an example of the rule-based approach) chapter, in the Classical NLP module) (voir aussi le chapitre La segmentation en unités lexicales (y compris un exemple d'approche à base de règles), dans le module TAL classique).
Conséquences d’une jetonisation moins efficace
Petrov et al. (2023) nomment trois conséquences, chacune avec un effet direct
pour les utilisateurs :
Une quatrième conséquence ne figure pas dans leur liste, mais a depuis été
démontrée elle aussi :
La qualité. Un jeton qui est un mot entier, ou un morceau de mot porteur
de sens, donne au modèle une meilleure unité sur laquelle construire ses
représentations qu’un fragment découpé selon la fréquence ; une langue dont
les mots sont brisés en fragments est donc plus difficile à apprendre.
Entraîner le même modèle avec des segmenteurs qui compriment plus ou moins
le texte montre la corrélation : plus la jetonisation est compacte, mieux le
modèle se comporte ensuite, le plus nettement sur les tâches de génération
(Goldman et al., 2024). La même chose vaut d’une langue à l’autre. Ali et
al. (2024) ont entraîné le même GML sur l’anglais, l’allemand, le français,
l’italien et l’espagnol deux fois, une fois avec un segmenteur centré sur
l’anglais et une fois avec un segmenteur construit pour les cinq langues.
Avec le segmenteur centré sur l’anglais, le modèle s’est montré nettement
moins bon dans les quatre autres langues, et son entraînement a coûté
jusqu’à 68 % de plus, parce que chaque texte non anglais était plus long.
Ali, M., Fromm, M., Thellmann, K., Rutmann, R., Lübbering, M., et al. (2024). Tokenizer Choice For LLM Training: Negligible or Crucial?. Findings of the Association for Computational Linguistics: NAACL 2024, 3907–3924. https://aclanthology.org/2024.findings-naacl.247/
Goldman, O., Caciularu, A., Eyal, M., Cao, K., Szpektor, I., & Tsarfaty, R. (2024). Unpacking Tokenization: Evaluating Text Compression and its Correlation with Model Performance. Findings of the Association for Computational Linguistics: ACL 2024, 2274–2286. https://aclanthology.org/2024.findings-acl.134/
NLLB Team, Costa-jussà, M. R., Cross, J., Çelebi, O., Elbayad, M., et al. (2024). Scaling neural machine translation to 200 languages. Nature, 630, 841–846. https://doi.org/10.1038/s41586-024-07335-x
In mid-2024 a question made the rounds online: how many rs are there in
strawberry? GPT-4o, a model for which there was a lot of media attention
and hype because it was supposed to be so intelligent and impressive,
stubbornly insisted there were only two. The discrepancy made the example go
viral: this model was able to do much more than humans in some senses, but
could not perform this basic counting task?!
Figure 2. ChatGPT running GPT-4o, mid-2024. Two r's, and a wrong position for both.
Figure 3. The same word inside a sentence, at Tiktokenizer with GPT-4o's tokenizer on 11 September 2026: six tokens, and strawberry is one of them. Figure 4. What you see, and what the model receives. The ID is the real one for the word inside a sentence, under OpenAI's o200k_base tokenizer (checked 11 September 2026).
The same limit affects every task that works on letters: spelling a word
backwards, counting characters for a length limit, building an acronym from
initials, judging a rhyme from its spelling.
The same question two years later
Asked the same question on 11 September 2026, ChatGPT and Claude both answer
three.
Figure 5. ChatGPT running GPT-6 Astra, 11 September 2026. Figure 6. Claude running Fable 5.1, 11 September 2026.
Does this mean the models of 2026 are better than GPT-4o? They are a lot
better, but this question is not the proof of it. A failure this famous ends
up in the training data, and a rule may well have been added so that this one
question gets a good answer. The mechanism has not changed: the model still
receives tokens, and a rarer word, another letter or another language can
find the same limit again.
Can they spell better, then? Yes, but they can still make mistakes.
Anecdotally, what I notice in my own use is that models have become much
more likely to spot a spelling error or a typo when I ask them to review a
document, which they were poor at two years ago.
A third possibility is that a system answers a question like this by writing
a few lines of code and running them. That would be overkill here, and
neither system did it, but models are much better at writing code than at
giving exact answers about letters, and the harnesses now built around them
let them call a tool when one is
relevant.
Sources
Edman, L., Schmid, H., & Fraser, A. (2024). CUTE: Measuring LLMs' Understanding of Their Tokens. Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, 3017–3026. https://aclanthology.org/2024.emnlp-main.177/
Se moquer de GPT-4o, qui ne sait pas compter les lettres
Au milieu de 2024, une question a circulé en ligne : combien y a-t-il de r
dans strawberry ? GPT-4o, un modèle qui avait reçu beaucoup d’attention
médiatique et suscité beaucoup d’enthousiasme parce qu’il était censé être si
intelligent et si impressionnant, soutenait obstinément qu’il n’y en avait que
deux. Le décalage a rendu l’exemple viral : ce modèle pouvait faire bien plus
que les humains à certains égards, mais n’arrivait pas à accomplir cette tâche
de comptage élémentaire ?!
Figure 2. ChatGPT sous GPT-4o, mi-2024. Deux r, et une position fausse pour les deux. La conversation est en anglais.
Figure 3. Le même mot dans une phrase, à Tiktokenizer avec le segmenteur de GPT-4o, le 11 septembre 2026 : six jetons, et strawberry en est un. Figure 4. Ce que vous voyez, et ce que le modèle reçoit. L'identifiant est le vrai, pour le mot dans une phrase, sous le segmenteur o200k_base d'OpenAI (vérifié le 11 septembre 2026).
La même limite touche toute tâche qui porte sur les lettres : épeler un mot à
l’envers, compter des caractères pour respecter une longueur maximale, former
un acronyme à partir d’initiales, juger d’une rime d’après l’orthographe.
La même question deux ans plus tard
Posée le 11 septembre 2026, la même question reçoit la réponse « trois » de ChatGPT
comme de Claude.
Figure 5. ChatGPT sous GPT-6 Astra, le 11 septembre 2026. Figure 6. Claude sous Fable 5.1, le 11 septembre 2026.
Cela veut-il dire que les modèles de 2026 sont meilleurs que GPT-4o ? Ils sont
bien meilleurs, mais cette question n’en est pas la preuve. Un échec aussi
célèbre finit dans les données d’entraînement, et une règle a fort bien pu
être ajoutée pour que cette question précise reçoive une bonne réponse. Le
mécanisme n’a pas changé : le modèle reçoit toujours des jetons, et un mot
plus rare, une autre lettre ou une autre langue peut retrouver la même limite.
Épellent-ils mieux, alors ? Oui, mais ils peuvent encore se tromper. De façon
anecdotique, ce que je constate dans mon propre usage, c’est que les modèles
sont devenus beaucoup plus susceptibles de repérer une faute d’orthographe ou
une coquille quand je leur demande de réviser un document, ce qu’ils faisaient
mal il y a deux ans.
Une troisième possibilité est qu’un système réponde à une question comme
celle-ci en écrivant quelques lignes de code et en les exécutant. Ce serait
disproportionné ici, et aucun des deux systèmes ne l’a fait, mais les modèles
sont bien meilleurs pour écrire du code que pour donner des réponses exactes
sur des lettres, et les environnements construits autour d’eux leur permettent
désormais d’appeler un outil quand c’est
pertinent.
Sources
Edman, L., Schmid, H., & Fraser, A. (2024). CUTE: Measuring LLMs' Understanding of Their Tokens. Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, 3017–3026. https://aclanthology.org/2024.emnlp-main.177/
The ratio depends on the type of text, so this one sample cannot be
generalized too much, but the overall pattern is clear.
Sources
NLLB Team, Costa-jussà, M. R., Cross, J., Çelebi, O., Elbayad, M., et al. (2024). Scaling neural machine translation to 200 languages. Nature, 630, 841–846. https://doi.org/10.1038/s41586-024-07335-x
Le ratio dépend du type de texte, si bien que cet échantillon unique ne peut
pas être trop généralisé, mais la tendance d’ensemble est claire.
Sources
NLLB Team, Costa-jussà, M. R., Cross, J., Çelebi, O., Elbayad, M., et al. (2024). Scaling neural machine translation to 200 languages. Nature, 630, 841–846. https://doi.org/10.1038/s41586-024-07335-x