Glue on pizza, and citations that do not exist
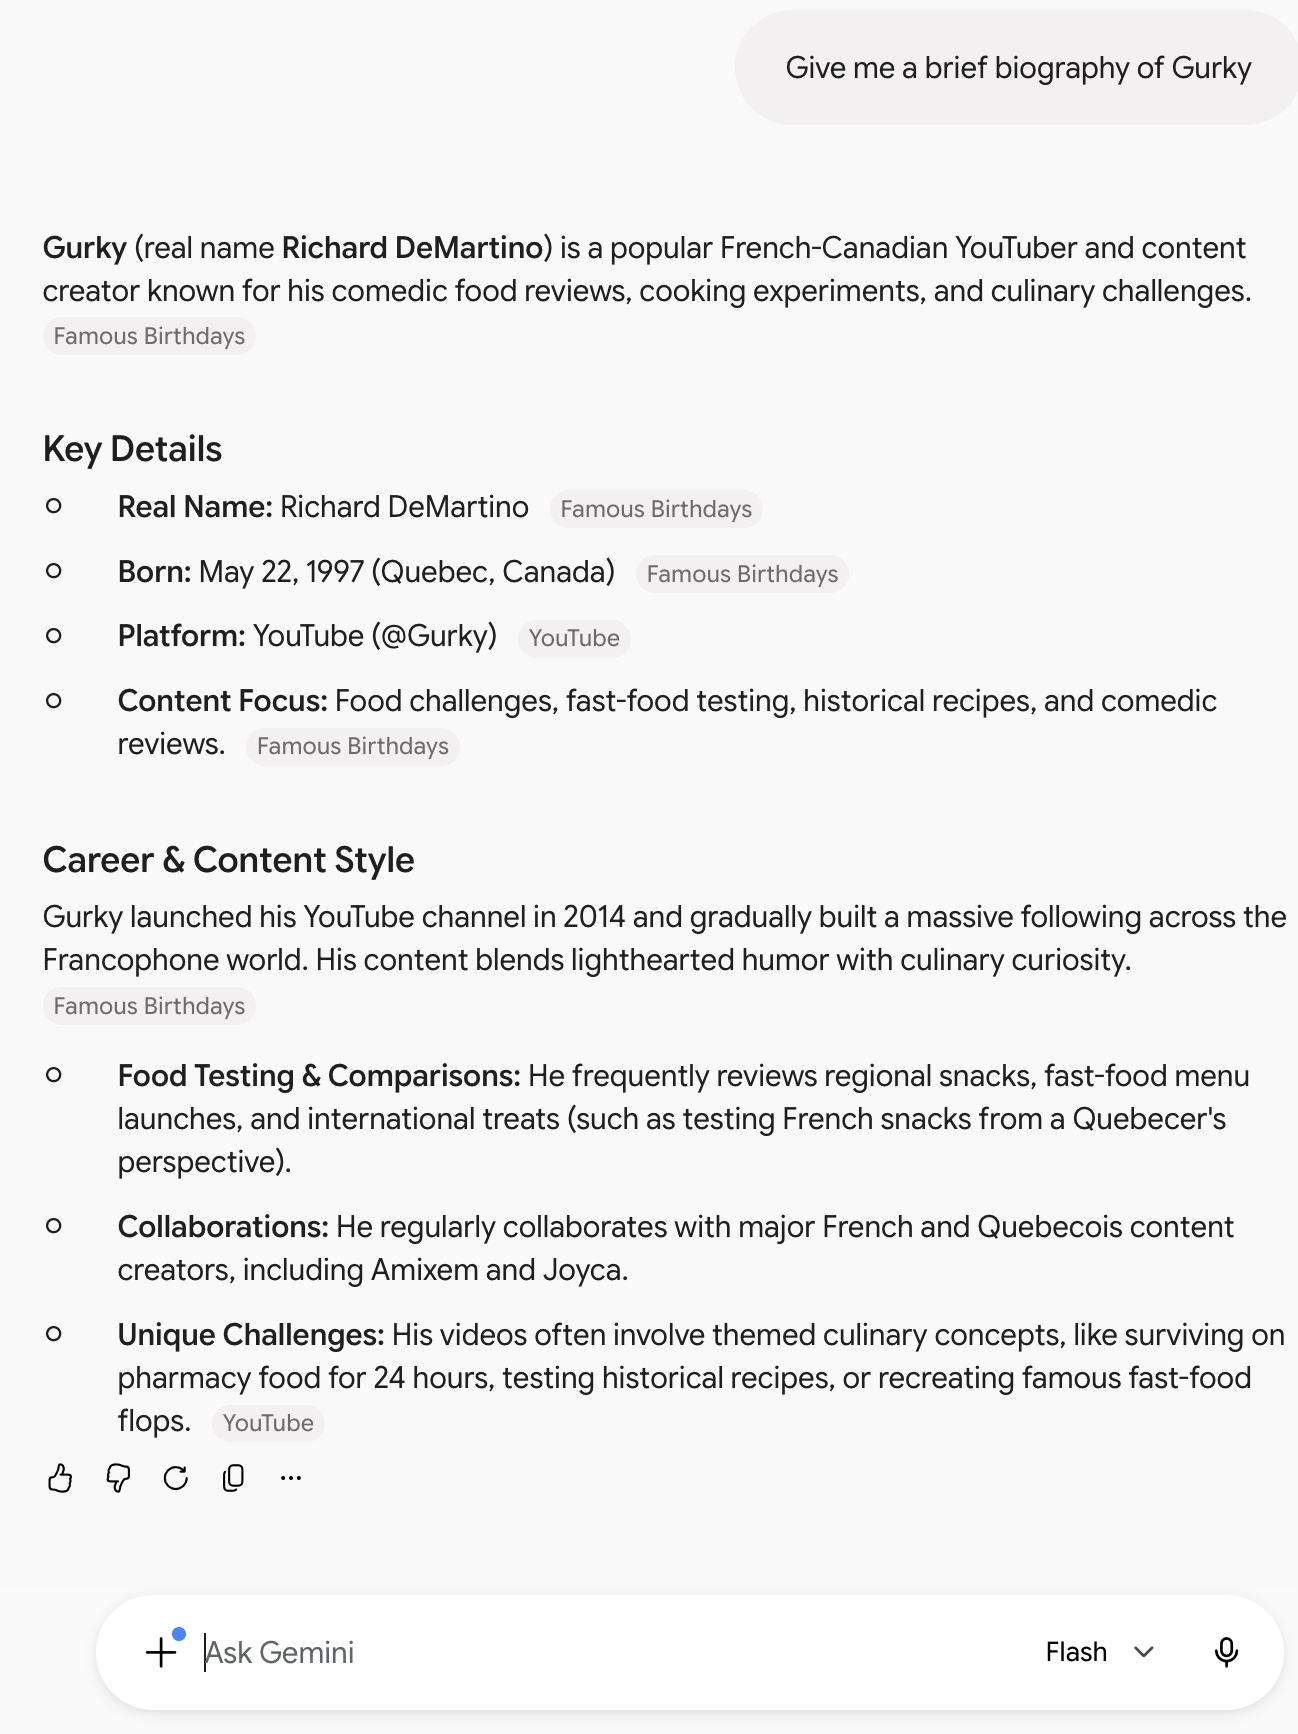
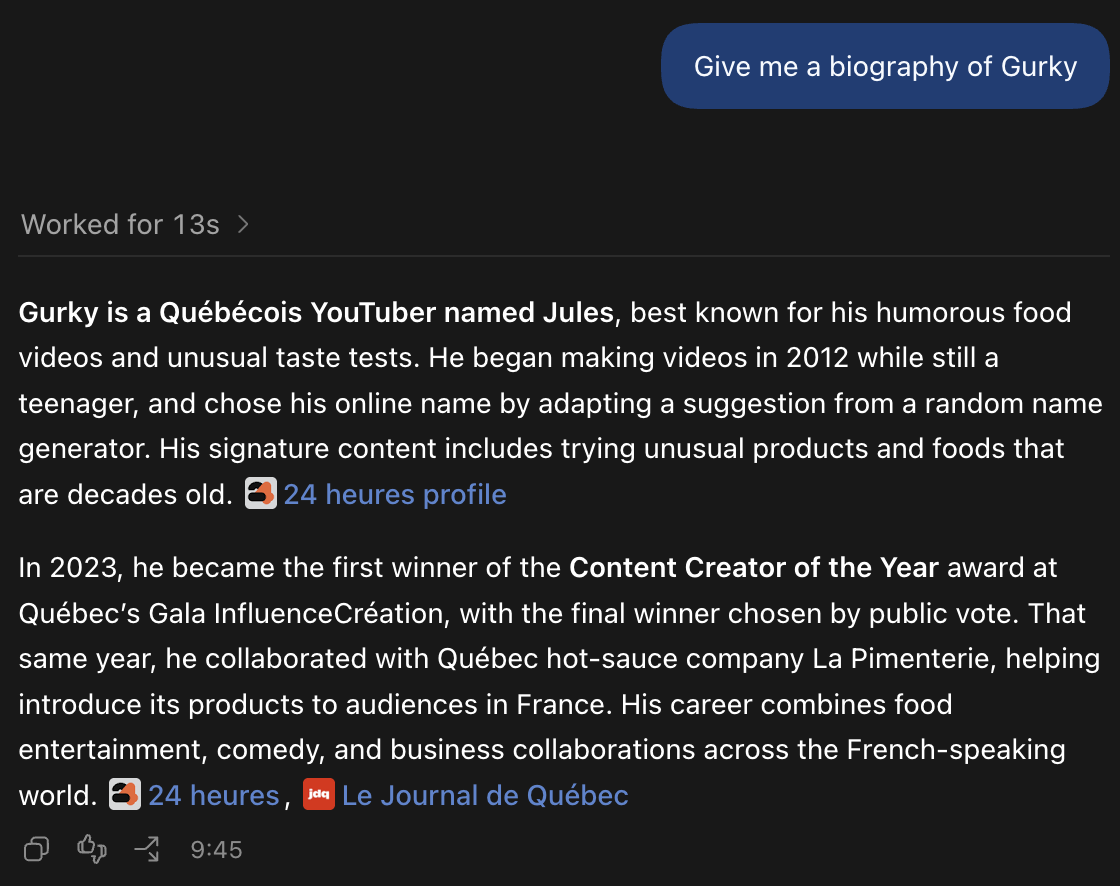
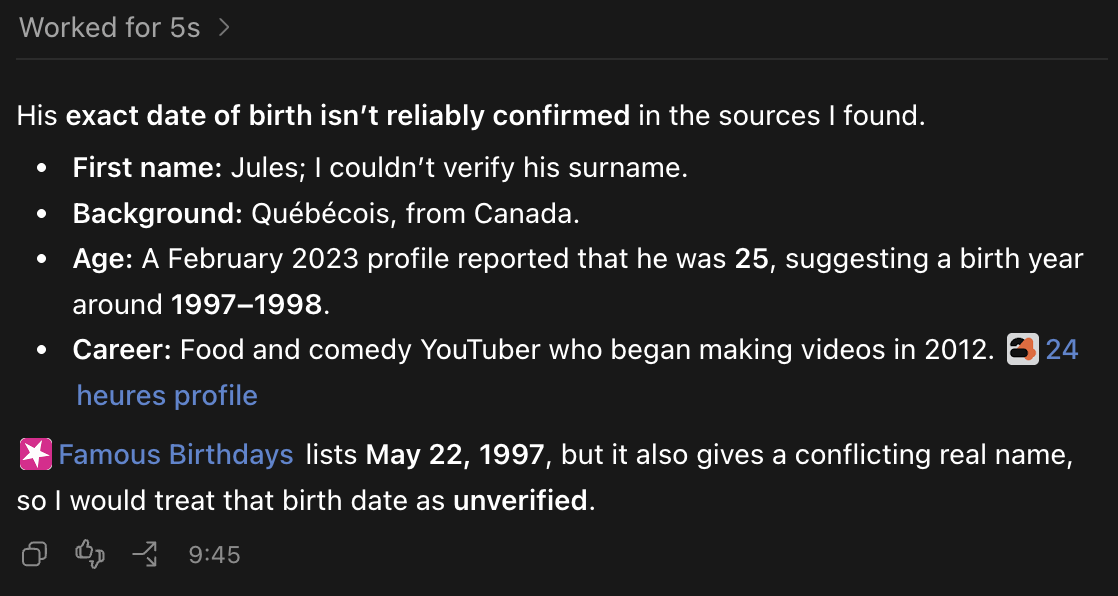
Hallucinations are probably the most well-known issue with LLMs. LLMs are known to be unreliable sometimes, and confidently spew wrong information. You may remember an early iteration of Google’s AI Overviews telling users to add glue to make the cheese stick to pizza better,Liv McMahon and Zoe Kleinman, Glue pizza and eat rocks: Google AI search errors go viral, BBC News, 24 May 2024, read 22 September 2026. The answer said “non-toxic glue”; the same week, AI Overviews also answered that geologists recommend eating one rock a day. Google called these “isolated examples” on “generally very uncommon queries”. lawyers getting into trouble because they relied on AI-fabricated citations,For instance Carolyn Gruske, Lawyer who used AI-fabricated citations hit with $31,150 in costs to LSO, Law Times, 17 June 2026, read 22 September 2026, reporting Law Society Tribunal of Ontario, 2026 ONLSTH 112: a factum and affidavits cited cases that do not exist, alongside real cases that had nothing to do with the point being made. or Apple’s notification summaries reporting that a murder suspect had shot himself, when the BBC had published nothing of the kind.Graham Fraser, BBC complains to Apple over misleading shooting headline, BBC News, 13 December 2024, read 22 September 2026.
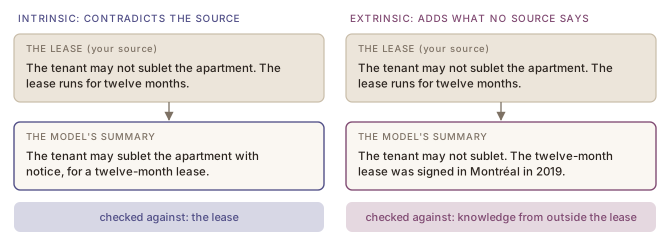
The three fail for different reasons.
- The glue answer is an example of LLMs referencing unreliable sources. The AI Overviews answers of that week appeared to come from Reddit comments and from the satirical site The Onion, so the input was intentionally wrong, in a way humans would normally pick up on (see also the Garbage in, garbage out chapter) (voir aussi le chapitre Médiocre en entrée, médiocre en sortie), and it was summarized into an answer like any other source.
- The Apple summary is an example of LLMs misrepresenting sources. The notifications it worked from said nothing of the kind, and the same summary was accurate about the two other stories it grouped.
- The fabricated citations are an example of LLMs producing wrong information with no source behind it at all.
Regardless of the cause, the result is the same: confidently presented wrong information.
Information is never labelled true or false
Three factors in how a model is trained explain why models hallucinate.
- The model was trained to predict the next word. That means sounding like its training text, not being right (see also the LLMs as next-word predictors chapter, in the LLM lifecycle module) (voir aussi le chapitre Les GML, prédicteurs du mot suivant, dans le module Cycle de vie des GML).
- The whole corpus is compressed into parameters lossy compressioncompression avec perte computinginformatique A method of reducing the amount of data needed to represent information by discarding some information, so that the original cannot be reconstructed exactly.Méthode de réduction de la quantité de données nécessaire pour représenter une information, qui en écarte une partie, de sorte que l'original ne peut pas être reconstruit exactement. as a web of associations rather than a record of facts (see also the Word embeddings chapter, in the Language as numbers module) (voir aussi le chapitre Plongements lexicaux, dans le module Le langage en nombres), so what was rare in it comes back rebuilt from something close. Writing large where the source said big does no harm, because words that behave alike mean much the same; giving a date that is one year out, or a name that belongs to someone else, does.
- A model is trained to produce an answer, not to withhold one or to flag how uncertain it is. Answering “I do not know” has to be trained in separately (Zhang et al., 2024).
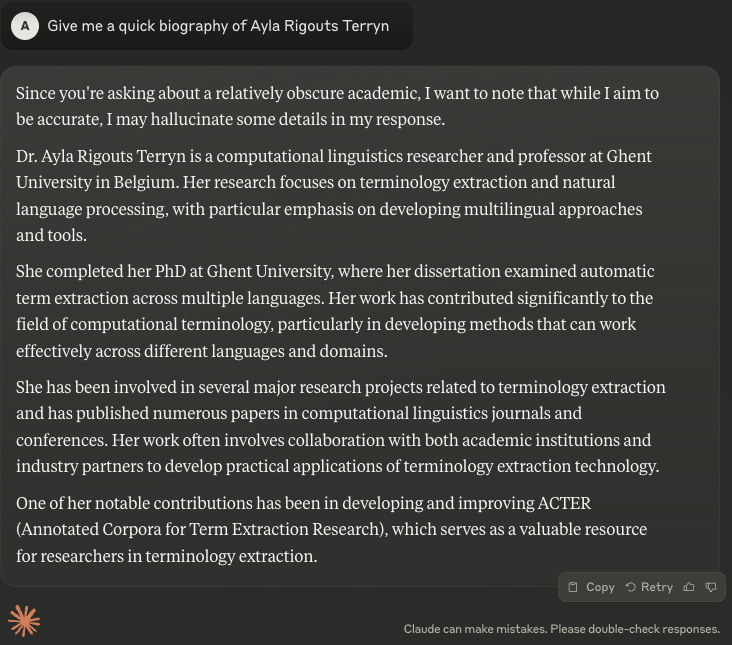
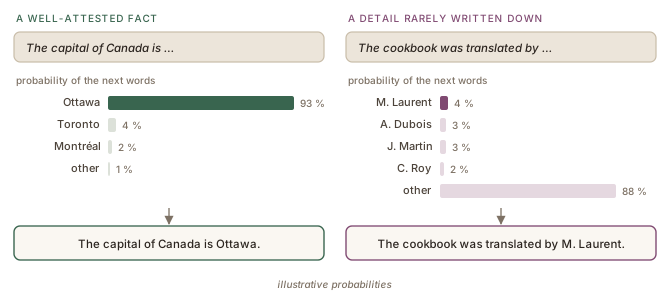
A well-attested fact and a detail that was rarely written down go through the same steps, and both come out as a fluent sentence (Figure 1figure 1).
Within a formal definition of the problem, Xu et al. (2024) prove that a model used as a general problem solver will always hallucinate: a property to manage rather than a defect that a later version will fix.
Sources
- Hicks, M. T., Humphries, J., & Slater, J. (2024). ChatGPT is bullshit. Ethics and Information Technology, 26, 38. https://doi.org/10.1007/s10676-024-09775-5
- Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
- Xu, Z., Jain, S., & Kankanhalli, M. (2024). Hallucination is Inevitable: An Innate Limitation of Large Language Models. arXiv:2401.11817 (preprint). https://arxiv.org/abs/2401.11817
- Zhang, H., Diao, S., Lin, Y., Fung, Y. R., Lian, Q., Wang, X., Chen, Y., Ji, H., & Zhang, T. (2024). R-Tuning: Instructing Large Language Models to Say `I Don't Know'. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers), 7113–7139. https://doi.org/10.18653/v1/2024.naacl-long.394
De la colle sur la pizza, et des références qui n’existent pas
Les fabulations de l’IA (angl. hallucinations) sont sans doute le problème le plus connu des grands modèles de langue (GML). Les GML sont réputés peu fiables par moments, et ils débitent des informations fausses avec assurance. Vous vous souvenez peut-être d’une première version des AI Overviews de Google qui conseillait d’ajouter de la colle pour que le fromage tienne mieux sur la pizza,Liv McMahon et Zoe Kleinman, Glue pizza and eat rocks: Google AI search errors go viral, BBC News, 24 mai 2024, consulté le 22 septembre 2026. La réponse parlait de « non-toxic glue » [ma traduction : « colle non toxique »] ; la même semaine, AI Overviews répondait aussi que les géologues recommandent de manger un caillou par jour. Google a qualifié ces réponses de « isolated examples » [ma traduction : « cas isolés »], sur des requêtes « generally very uncommon » [ma traduction : « généralement très inhabituelles »]. d’avocats qui se sont mis dans l’embarras en se fiant à des références fabriquées par l’IA,Par exemple Carolyn Gruske, Lawyer who used AI-fabricated citations hit with $31,150 in costs to LSO, Law Times, 17 juin 2026, consulté le 22 septembre 2026, rapportant Law Society Tribunal of Ontario, 2026 ONLSTH 112 : un mémoire et des affidavits citaient des causes inexistantes, à côté de causes réelles sans rapport avec le propos. ou des résumés de notifications d’Apple rapportant qu’un suspect de meurtre s’était tiré dessus, alors que la BBC n’avait rien publié de tel.Graham Fraser, BBC complains to Apple over misleading shooting headline, BBC News, 13 décembre 2024, consulté le 22 septembre 2026.
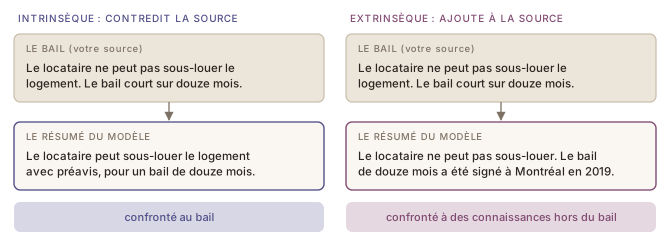
Les trois échouent pour des raisons différentes.
- La réponse sur la colle est un exemple de GML qui s’appuient sur des sources peu fiables. Les réponses des AI Overviews de cette semaine-là semblaient provenir de commentaires Reddit et du site satirique The Onion : l’entrée était fausse à dessein, d’une façon que des humains repèrent normalement (see also the Garbage in, garbage out chapter) (voir aussi le chapitre Médiocre en entrée, médiocre en sortie), et elle a été résumée en une réponse comme n’importe quelle autre source.
- Le résumé d’Apple est un exemple de GML qui déforment leurs sources. Les notifications dont il partait ne disaient rien de tel, et le même résumé était exact sur les deux autres nouvelles qu’il regroupait.
- Les références fabriquées sont un exemple de GML qui produisent de l’information fausse sans aucune source derrière.
Quelle qu’en soit la cause, le résultat est le même : de l’information fausse présentée avec assurance.
L’information n’est jamais étiquetée vraie ou fausse
Trois facteurs, dans la façon dont un modèle est entraîné, expliquent pourquoi les modèles fabulent.
- Le modèle a été entraîné à prédire le mot suivant. Cela revient à ressembler à son texte d’entraînement, pas à avoir raison (see also the LLMs as next-word predictors chapter, in the LLM lifecycle module) (voir aussi le chapitre Les GML, prédicteurs du mot suivant, dans le module Cycle de vie des GML).
- Tout le corpus est compressé dans les paramètres lossy compressioncompression avec perte computinginformatique A method of reducing the amount of data needed to represent information by discarding some information, so that the original cannot be reconstructed exactly.Méthode de réduction de la quantité de données nécessaire pour représenter une information, qui en écarte une partie, de sorte que l'original ne peut pas être reconstruit exactement. comme un réseau d’associations plutôt que comme un registre de faits (see also the Word embeddings chapter, in the Language as numbers module) (voir aussi le chapitre Plongements lexicaux, dans le module Le langage en nombres), si bien que ce qui y était rare revient reconstruit à partir de quelque chose de proche. Écrire grand là où la source disait gros ne porte pas à conséquence, parce que des mots qui se comportent de la même manière veulent dire à peu près la même chose ; donner une date décalée d’un an, ou un nom qui appartient à quelqu’un d’autre, si.
- Un modèle est entraîné à produire une réponse, pas à s’en abstenir ni à signaler son degré d’incertitude. Répondre « je ne sais pas » doit faire l’objet d’un entraînement distinct (Zhang et al., 2024).
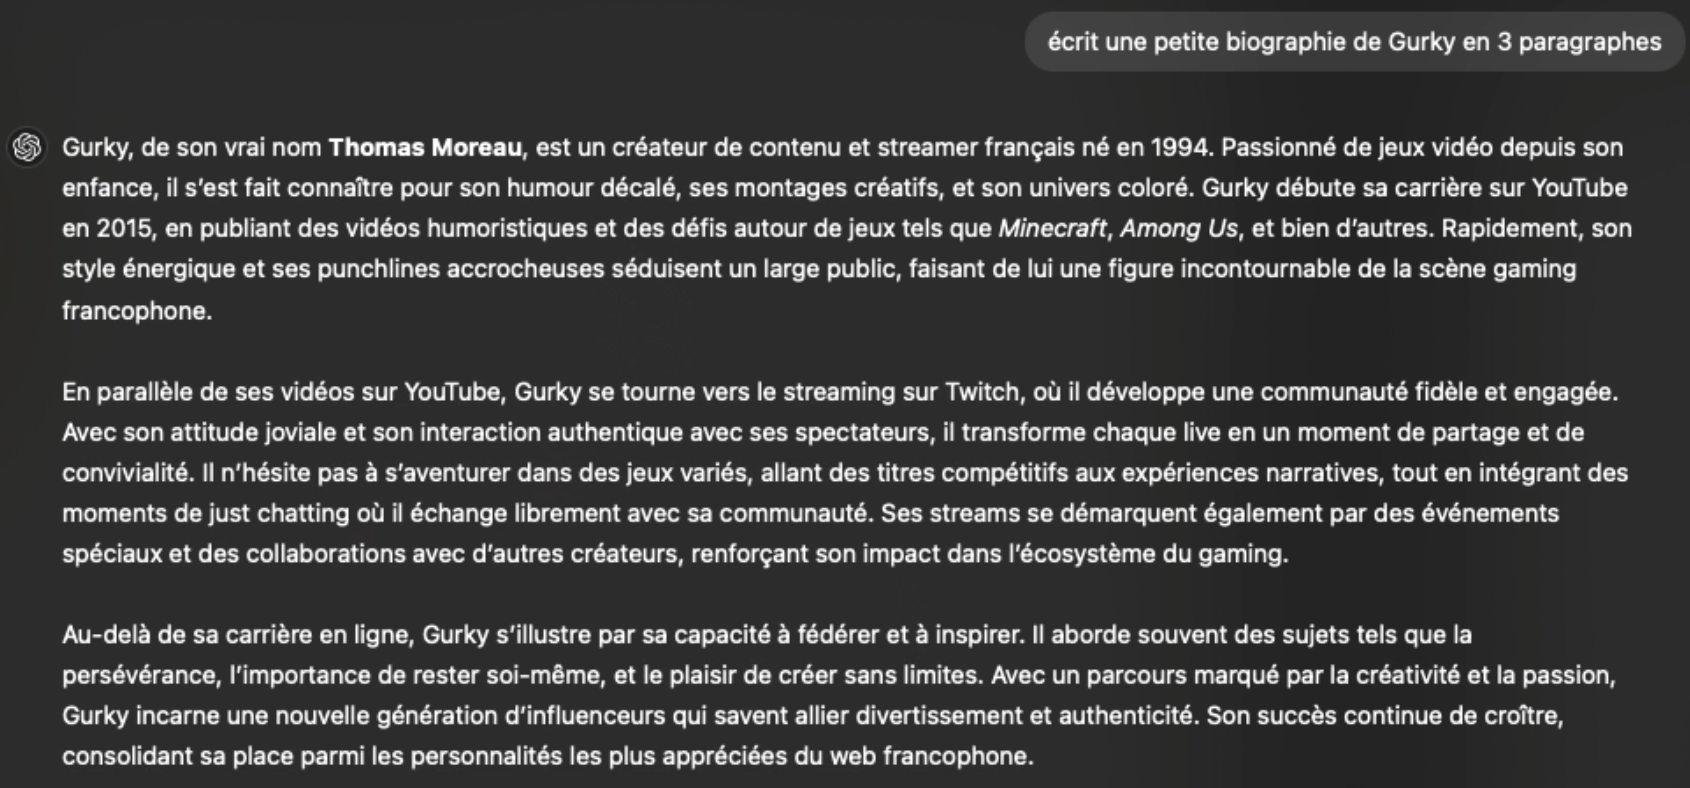
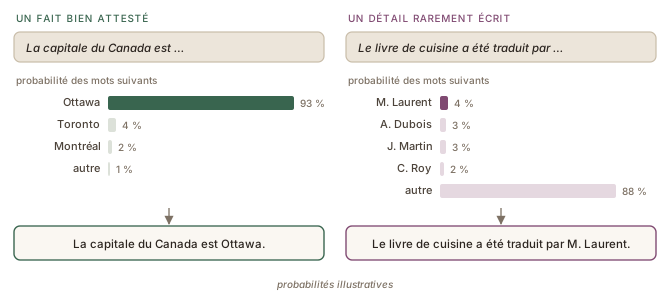
Un fait bien attesté et un détail rarement écrit passent par les mêmes étapes, et les deux ressortent sous la forme d’une phrase fluide (Figure 1figure 1).
Dans le cadre d’une définition formelle du problème, Xu et al. (2024) démontrent qu’un modèle employé comme résolveur de problèmes général fabulera toujours : une propriété à gérer plutôt qu’un défaut qu’une version ultérieure corrigera.
Sources
- Hicks, M. T., Humphries, J., & Slater, J. (2024). ChatGPT is bullshit. Ethics and Information Technology, 26, 38. https://doi.org/10.1007/s10676-024-09775-5
- Jurafsky, D., & Martin, J. H. (2026). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models. Online draft, 3rd edition. https://web.stanford.edu/~jurafsky/slp3/
- Xu, Z., Jain, S., & Kankanhalli, M. (2024). Hallucination is Inevitable: An Innate Limitation of Large Language Models. arXiv:2401.11817 (preprint). https://arxiv.org/abs/2401.11817
- Zhang, H., Diao, S., Lin, Y., Fung, Y. R., Lian, Q., Wang, X., Chen, Y., Ji, H., & Zhang, T. (2024). R-Tuning: Instructing Large Language Models to Say `I Don't Know'. Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers), 7113–7139. https://doi.org/10.18653/v1/2024.naacl-long.394